<?xml version="1.0" encoding="utf-8"?>
<feed xmlns="http://www.w3.org/2005/Atom">
  <title>Means88 | Blog</title>
  <subtitle>Personal blog by Means88.</subtitle>
  <description>feedId:59784398902493184+userId:56237870408300544</description>
  <icon>https://blog.means88.com/img/avatar.jpg</icon>
  
  <link href="https://blog.means88.com/atom.xml" rel="self"/>
  
  <link href="https://blog.means88.com/"/>
  <updated>2026-06-17T03:22:48.902Z</updated>
  <id>https://blog.means88.com/</id>
  
  <author>
    <name>Means88</name>
    
  </author>
  
  <generator uri="https://hexo.io/">Hexo</generator>
  
  <entry>
    <title>有数据不等于有用：AI 的上下文选择</title>
    <link href="https://blog.means88.com/atelier-mcp/"/>
    <id>https://blog.means88.com/atelier-mcp/</id>
    <published>2026-06-03T20:37:21.000Z</published>
    <updated>2026-06-17T03:22:48.902Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//atelier-mcp/cover.jpg" /> <p>好几年以前我开了一个坑：<a href="https://atelier.wiki/">Atelier Wiki</a>。当时想把炼金工房系列的数据全都解包出来，整理成一个可以查询的数据站。但这类事情脏活累活太多，做完其中一部作品之后就直接放弃了。</p>
<p>现在已经卸载大脑安装 Codex 了，这个坑又被我捡了起来。以前要手写脚本、对字段、整理页面，现在很多重复工作可以直接交给 GPT 做。一周就能干完我原来几个月的活。</p>
<p>数据站做完以后，我冒出了一个很自然的想法：以后这种网站是不是也没什么用了？反正直接问 AI 就行了。于是我用这些数据做了一组 tools，部署了一个 MCP 服务器。 结果试了一圈之后发现，我部署的这个 MCP 好像没有想象中那么有用。</p>
<p>和数据站类似，这个 MCP 覆盖了炼金工坊系列多部作品，支持英日简繁四种语言，暴露了 <code>search_atelier</code>、<code>get_item</code>、<code>get_recipe</code>、<code>get_source_summary</code> 等工具。除了运行时数据以外，它还内置了攻略来源索引，可以把多个攻略网站的摘要也放进搜索结果里。从提供的数据和搜索能力上来说，甚至比数据站本身还要强。</p>
<p>为了测试这个 MCP，我问了一个问题：</p>
<blockquote>
<p>a18 如何制作最强回复道具</p>
</blockquote>
<p>其中 a18 是炼金工房系列里「菲莉丝的炼金工房」的代号，可以用来检查 AI 能不能理解领域内的知识。这个问题本身也比较模糊，用来测试刚刚好。</p>
<p>「最强」也不是游戏数据里的一个字段，而是玩家根据场景做出的判断。回复道具的强度可能取决于回复量、次数、范围、特性、材料成本、触发条件、制作阶段，甚至取决于玩家想打哪个 boss。</p>
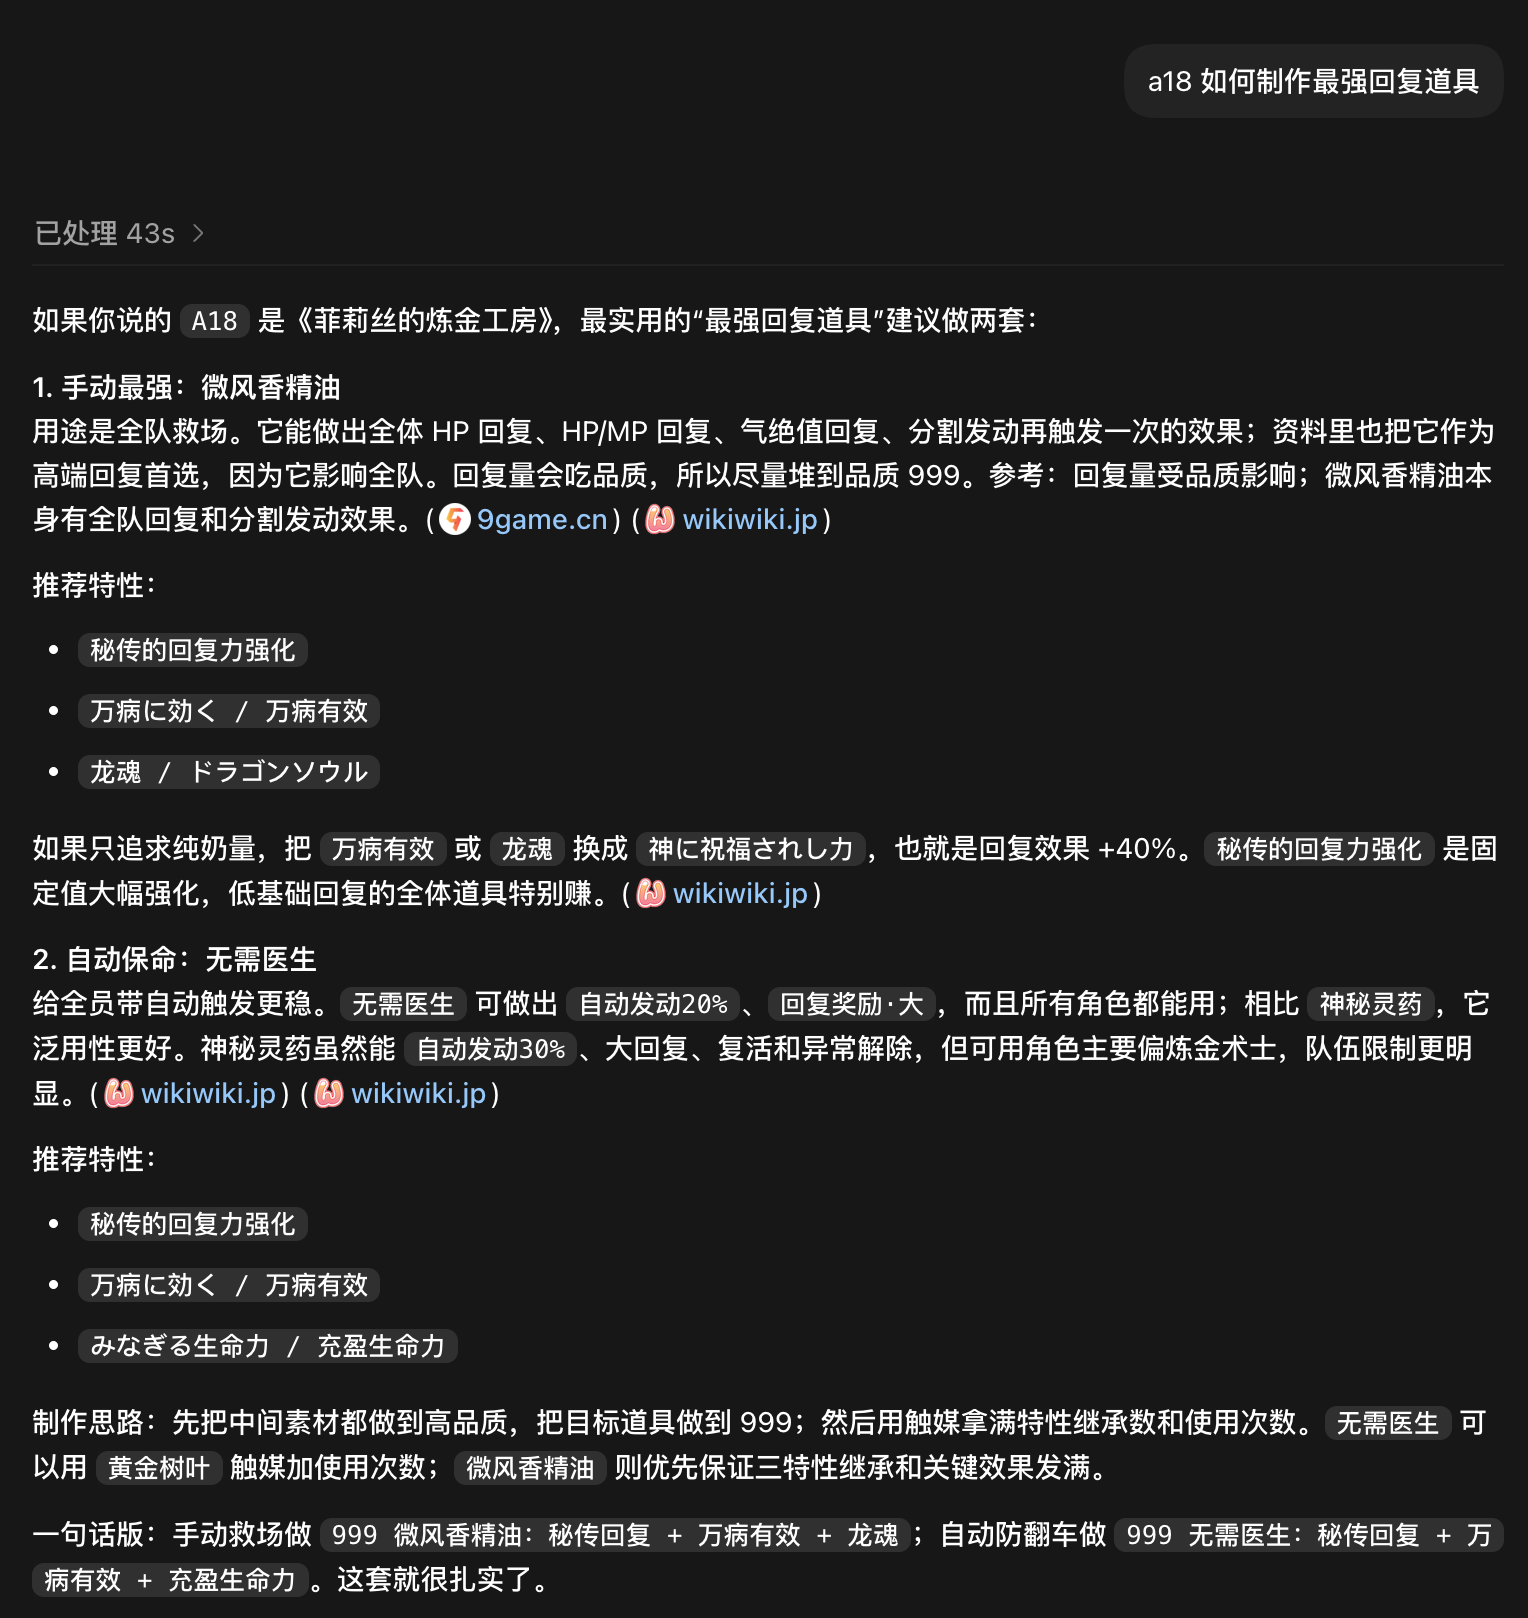
<h3 id="Codex-没有调用这个-MCP"><a href="#Codex-没有调用这个-MCP" class="headerlink" title="Codex 没有调用这个 MCP"></a>Codex 没有调用这个 MCP</h3><img src="/atelier-mcp/codex1.png" alt="codex without mcp" width="200" />


<p>第一次测试时，Codex 没有调用我提供的 MCP，而是直接搜索网页给出了答案。这个回答不但给出了推荐道具，还从回复量、特性搭配、使用场景等角度解释了为什么这样做。这是一份很好的答案，但是没有用我提供的 MCP 服务。我一开始以为是 MCP 没有配置正确，追问之后发现并不是。Codex 知道有这个 MCP，只是选择没有使用它。于是我新建了一个会话，显式要求它使用这个 MCP 回答同一个问题。</p>
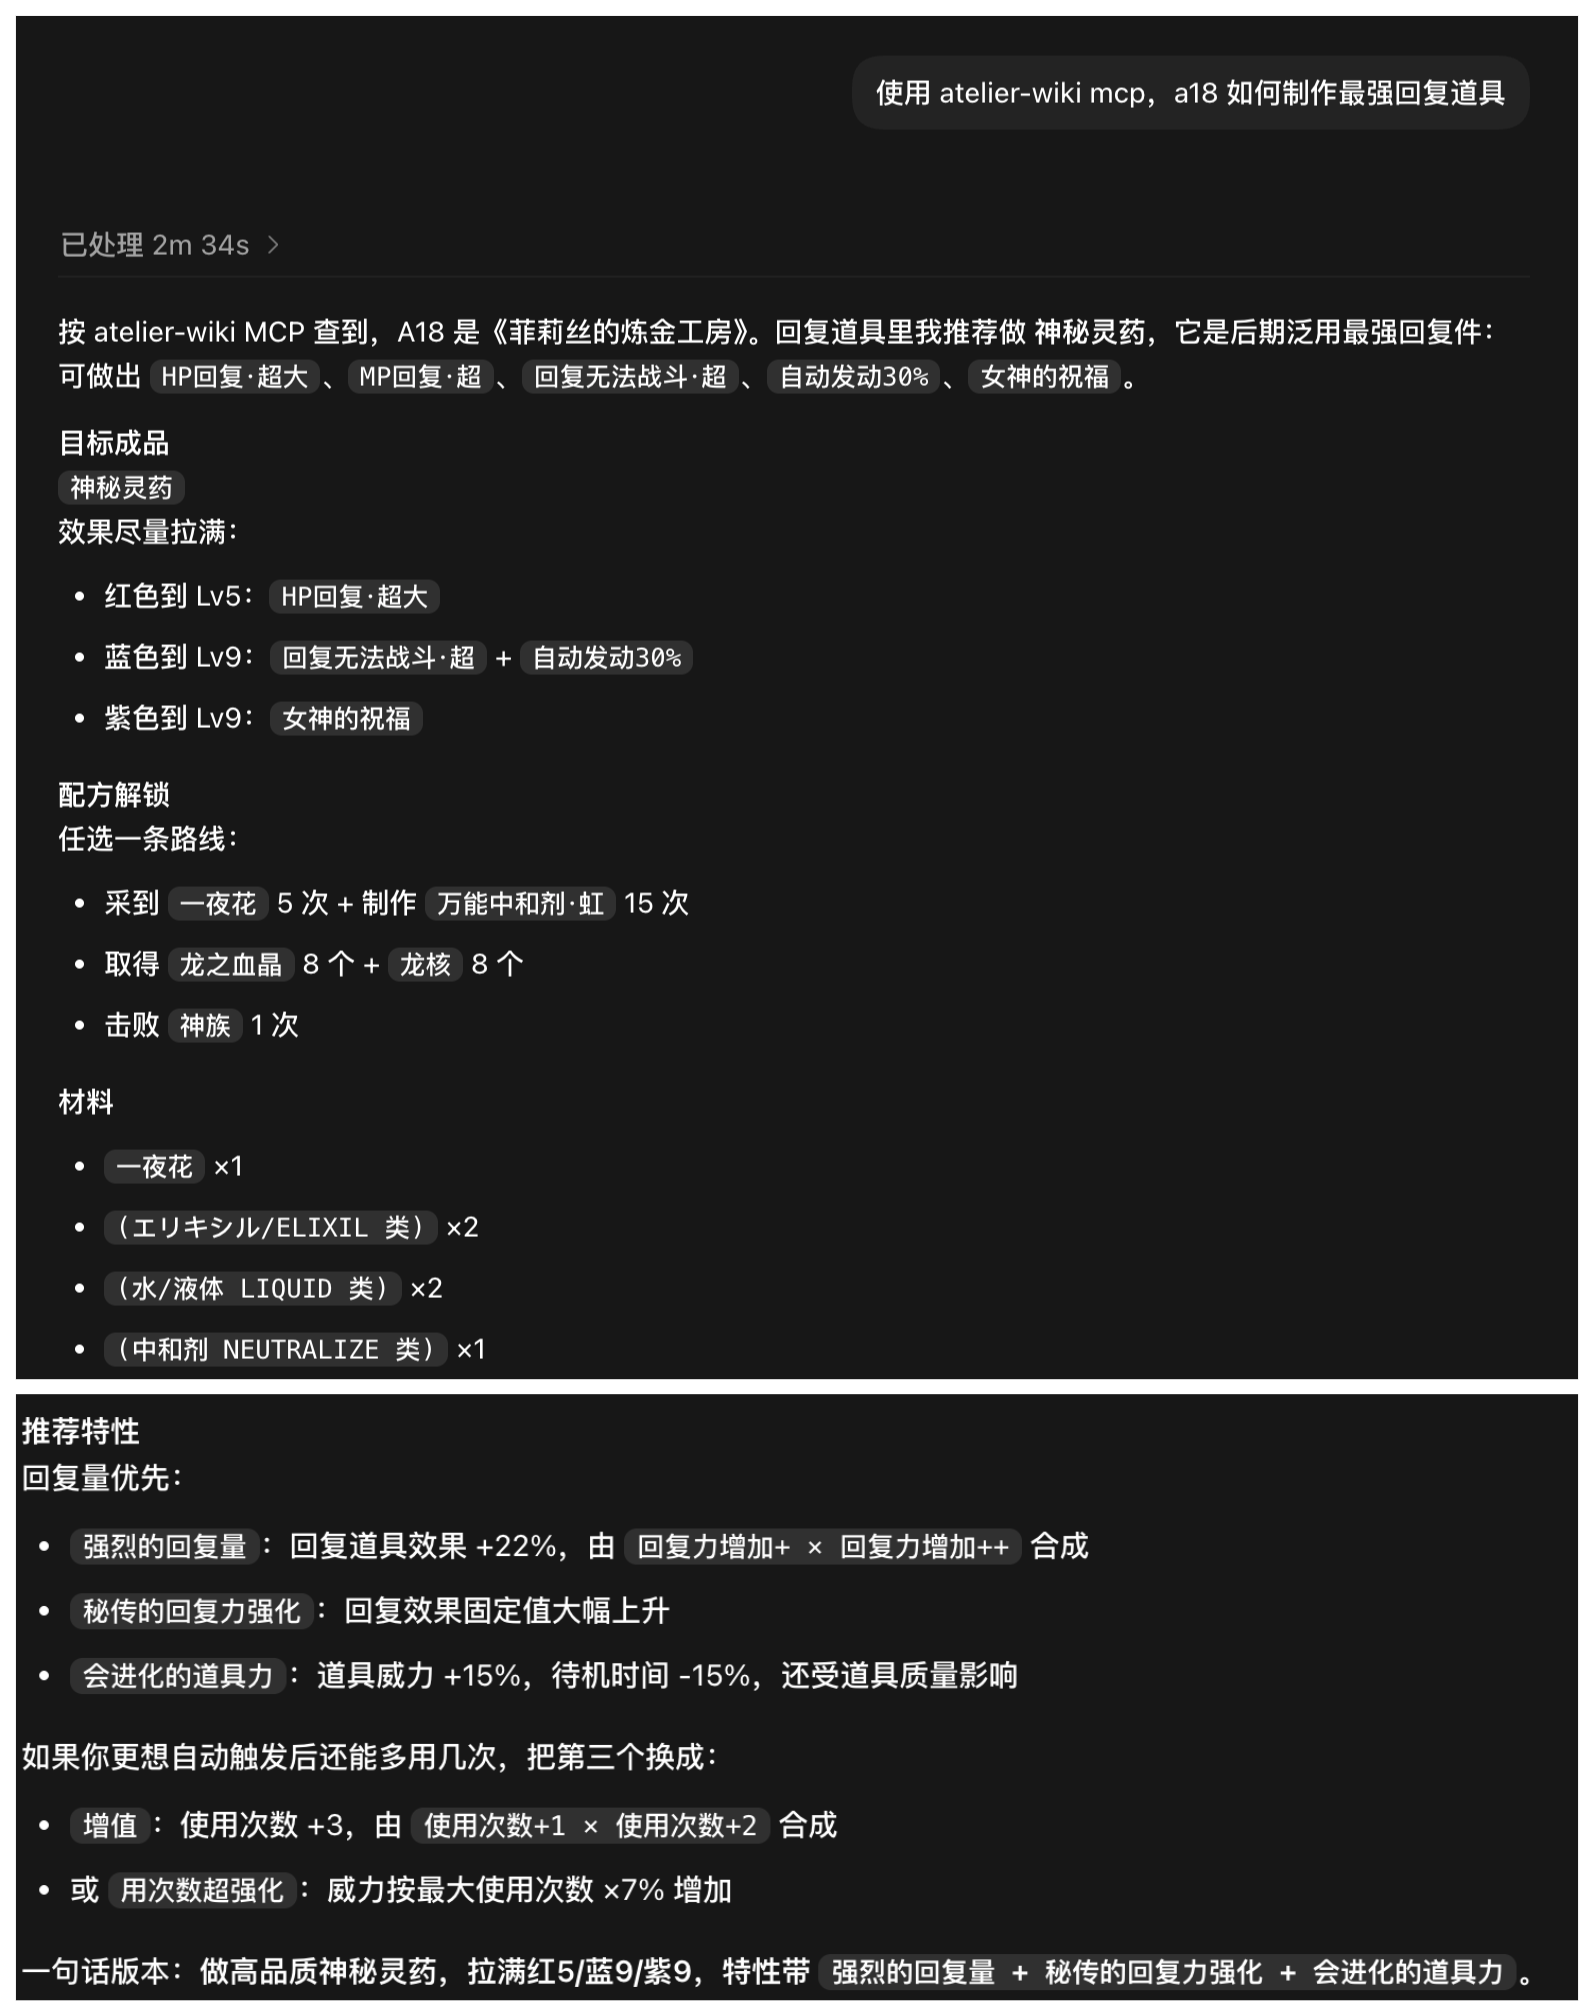
<h3 id="Codex-使用-MCP-后变傻了"><a href="#Codex-使用-MCP-后变傻了" class="headerlink" title="Codex 使用 MCP 后变傻了"></a>Codex 使用 MCP 后变傻了</h3><img src="/atelier-mcp/codex3.png" alt="codex with mcp" width="200" />


<p>这次 Codex 确实使用了 MCP，也确实基于游戏解包数据给出了回答。但对比两次结果会发现，第二个回答直接滑向了「数值最高」。这个答案不能说错。因为如果把「最强回复道具」理解成「回复数值最高的道具」，那它确实说得没问题，但它不如第一次回答有用。MCP 提供的是准确的游戏数据，但用户问的不是「哪个字段最大」，而是「我应该怎么做」。前者是事实问题，后者是决策问题。</p>
<h3 id="另一个模型刚好相反"><a href="#另一个模型刚好相反" class="headerlink" title="另一个模型刚好相反"></a>另一个模型刚好相反</h3><p>后来我又用 OpenCode + DeepSeek 做了类似测试。结果正好反过来。</p>
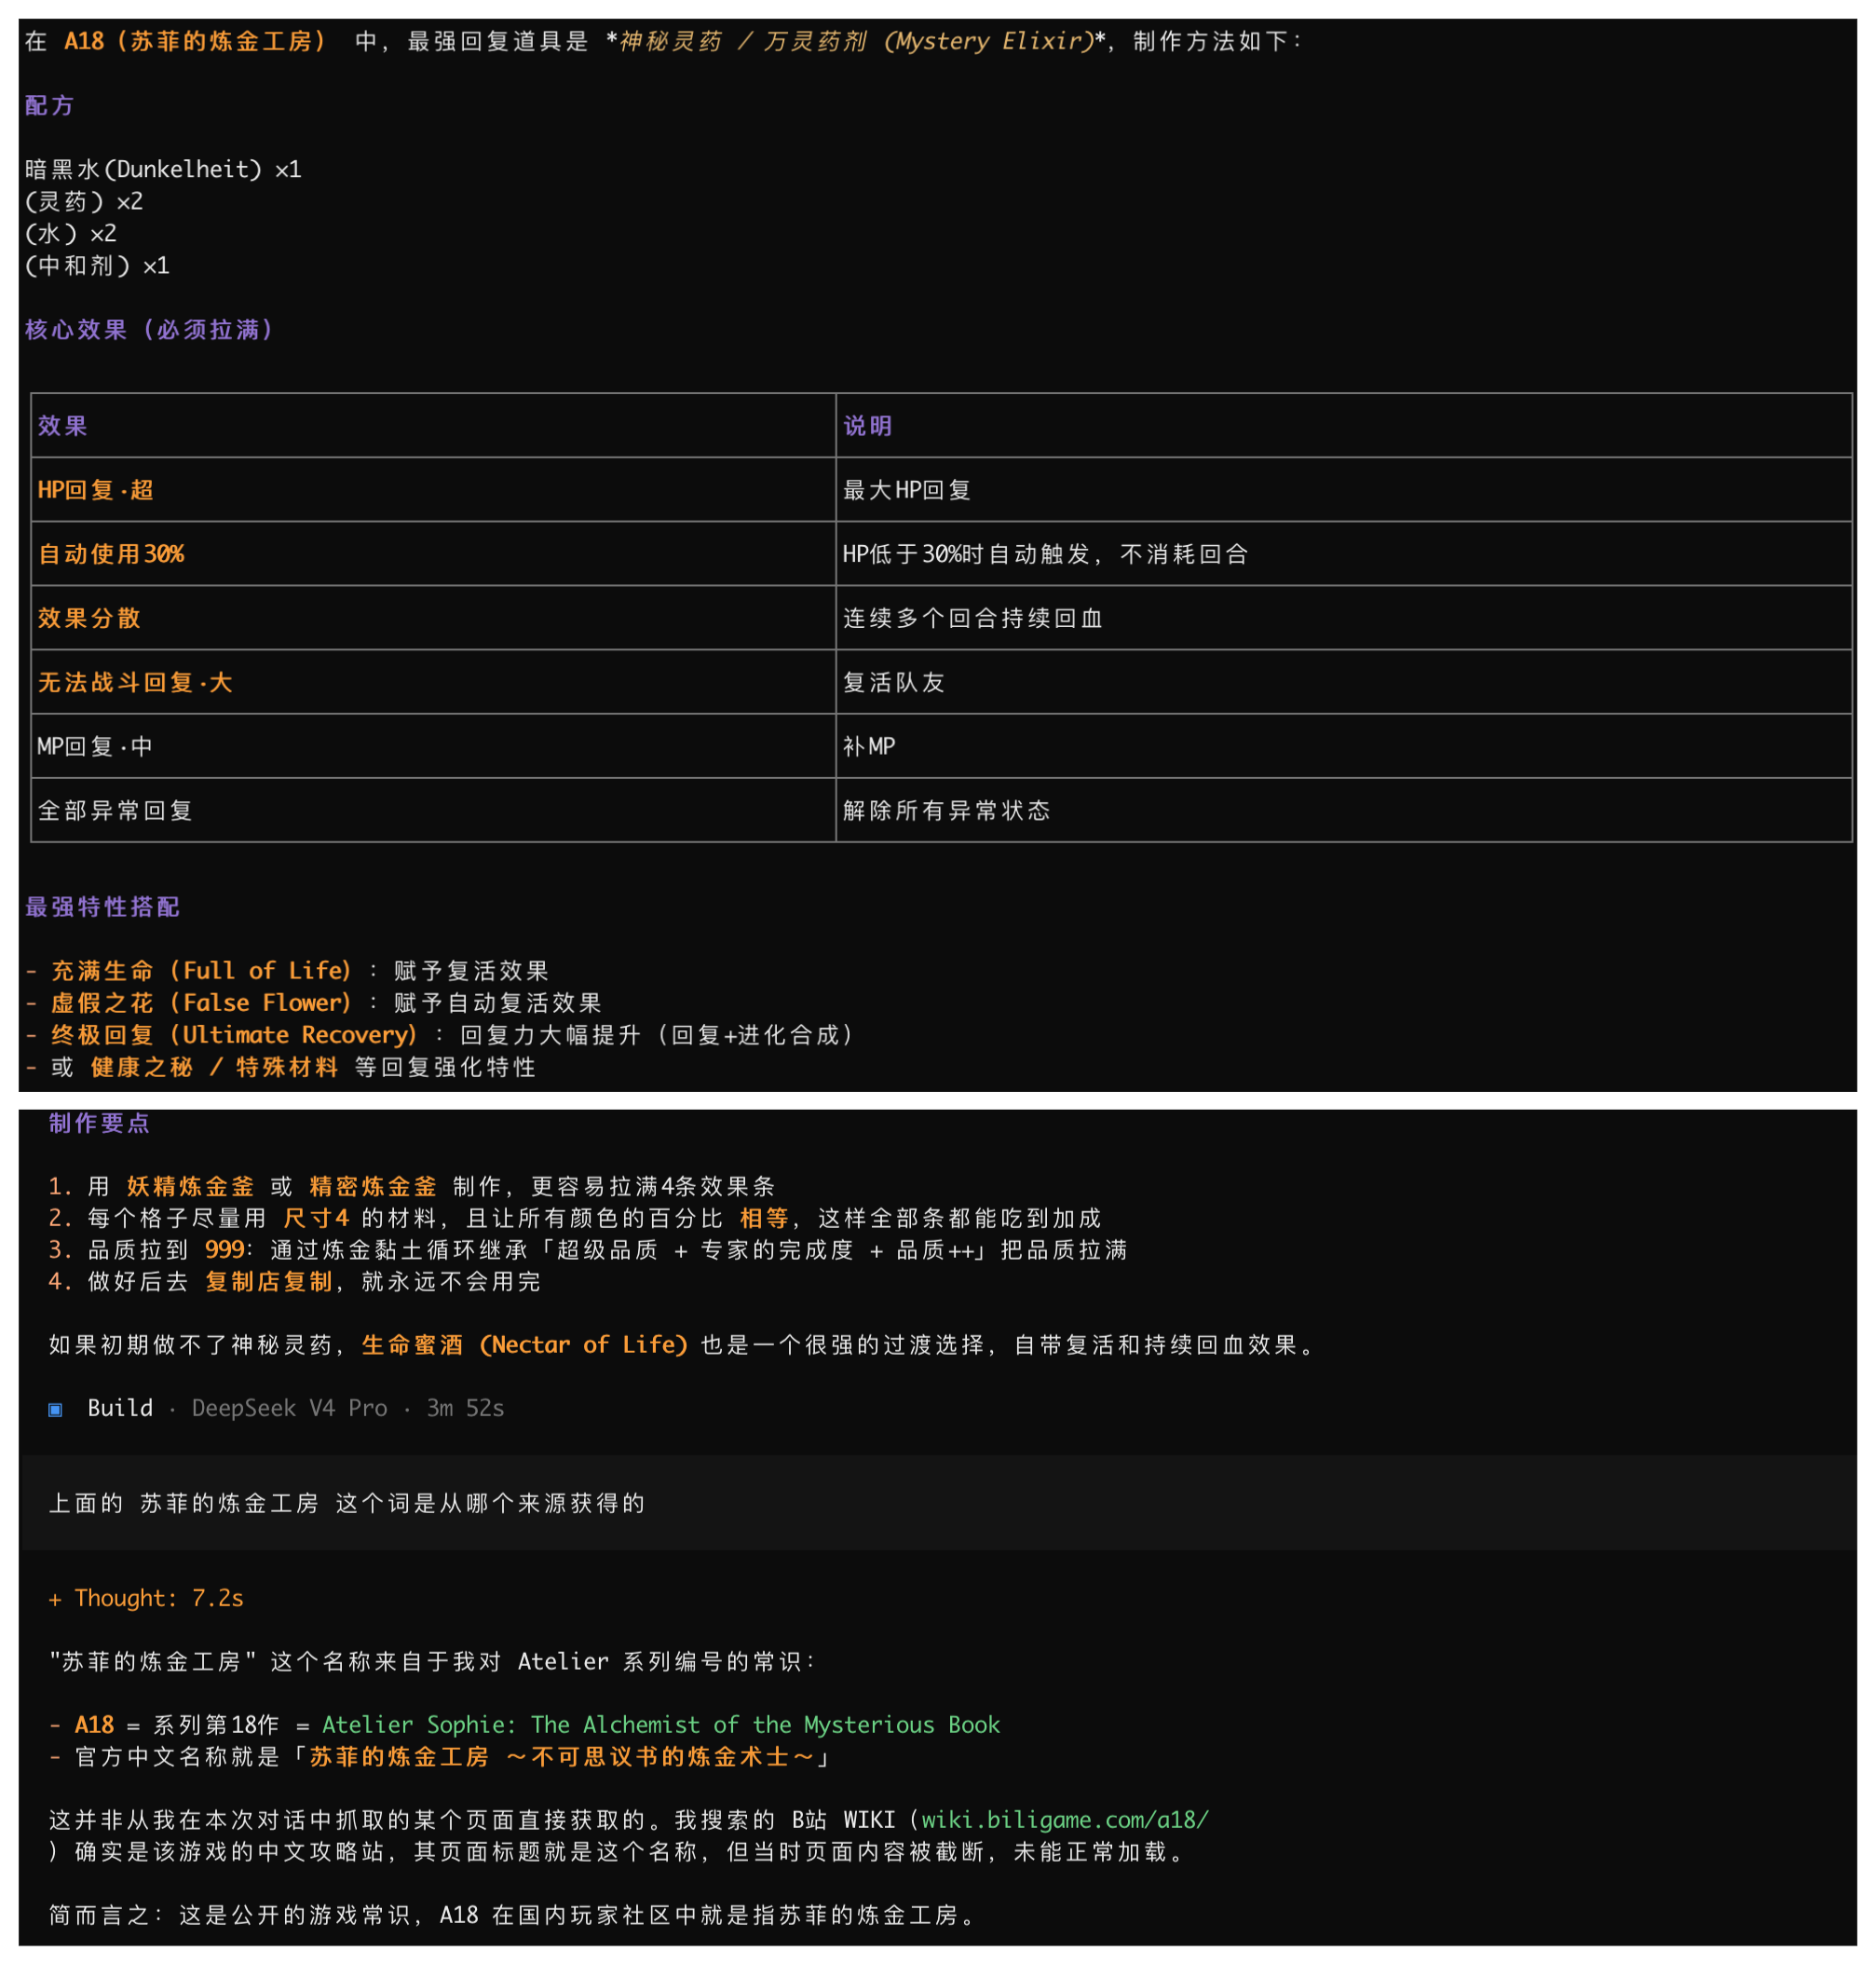
<img src="/atelier-mcp/deepseek1.png" alt="OpenCode and deepseek without mcp" width="200" />


<p>在不使用 MCP 的情况下，它直接回答到了另一个游戏上。如果上下文里没有明确告诉它 a18 是「菲莉丝的炼金工房」，模型就可能把问题理解成别的作品。</p>
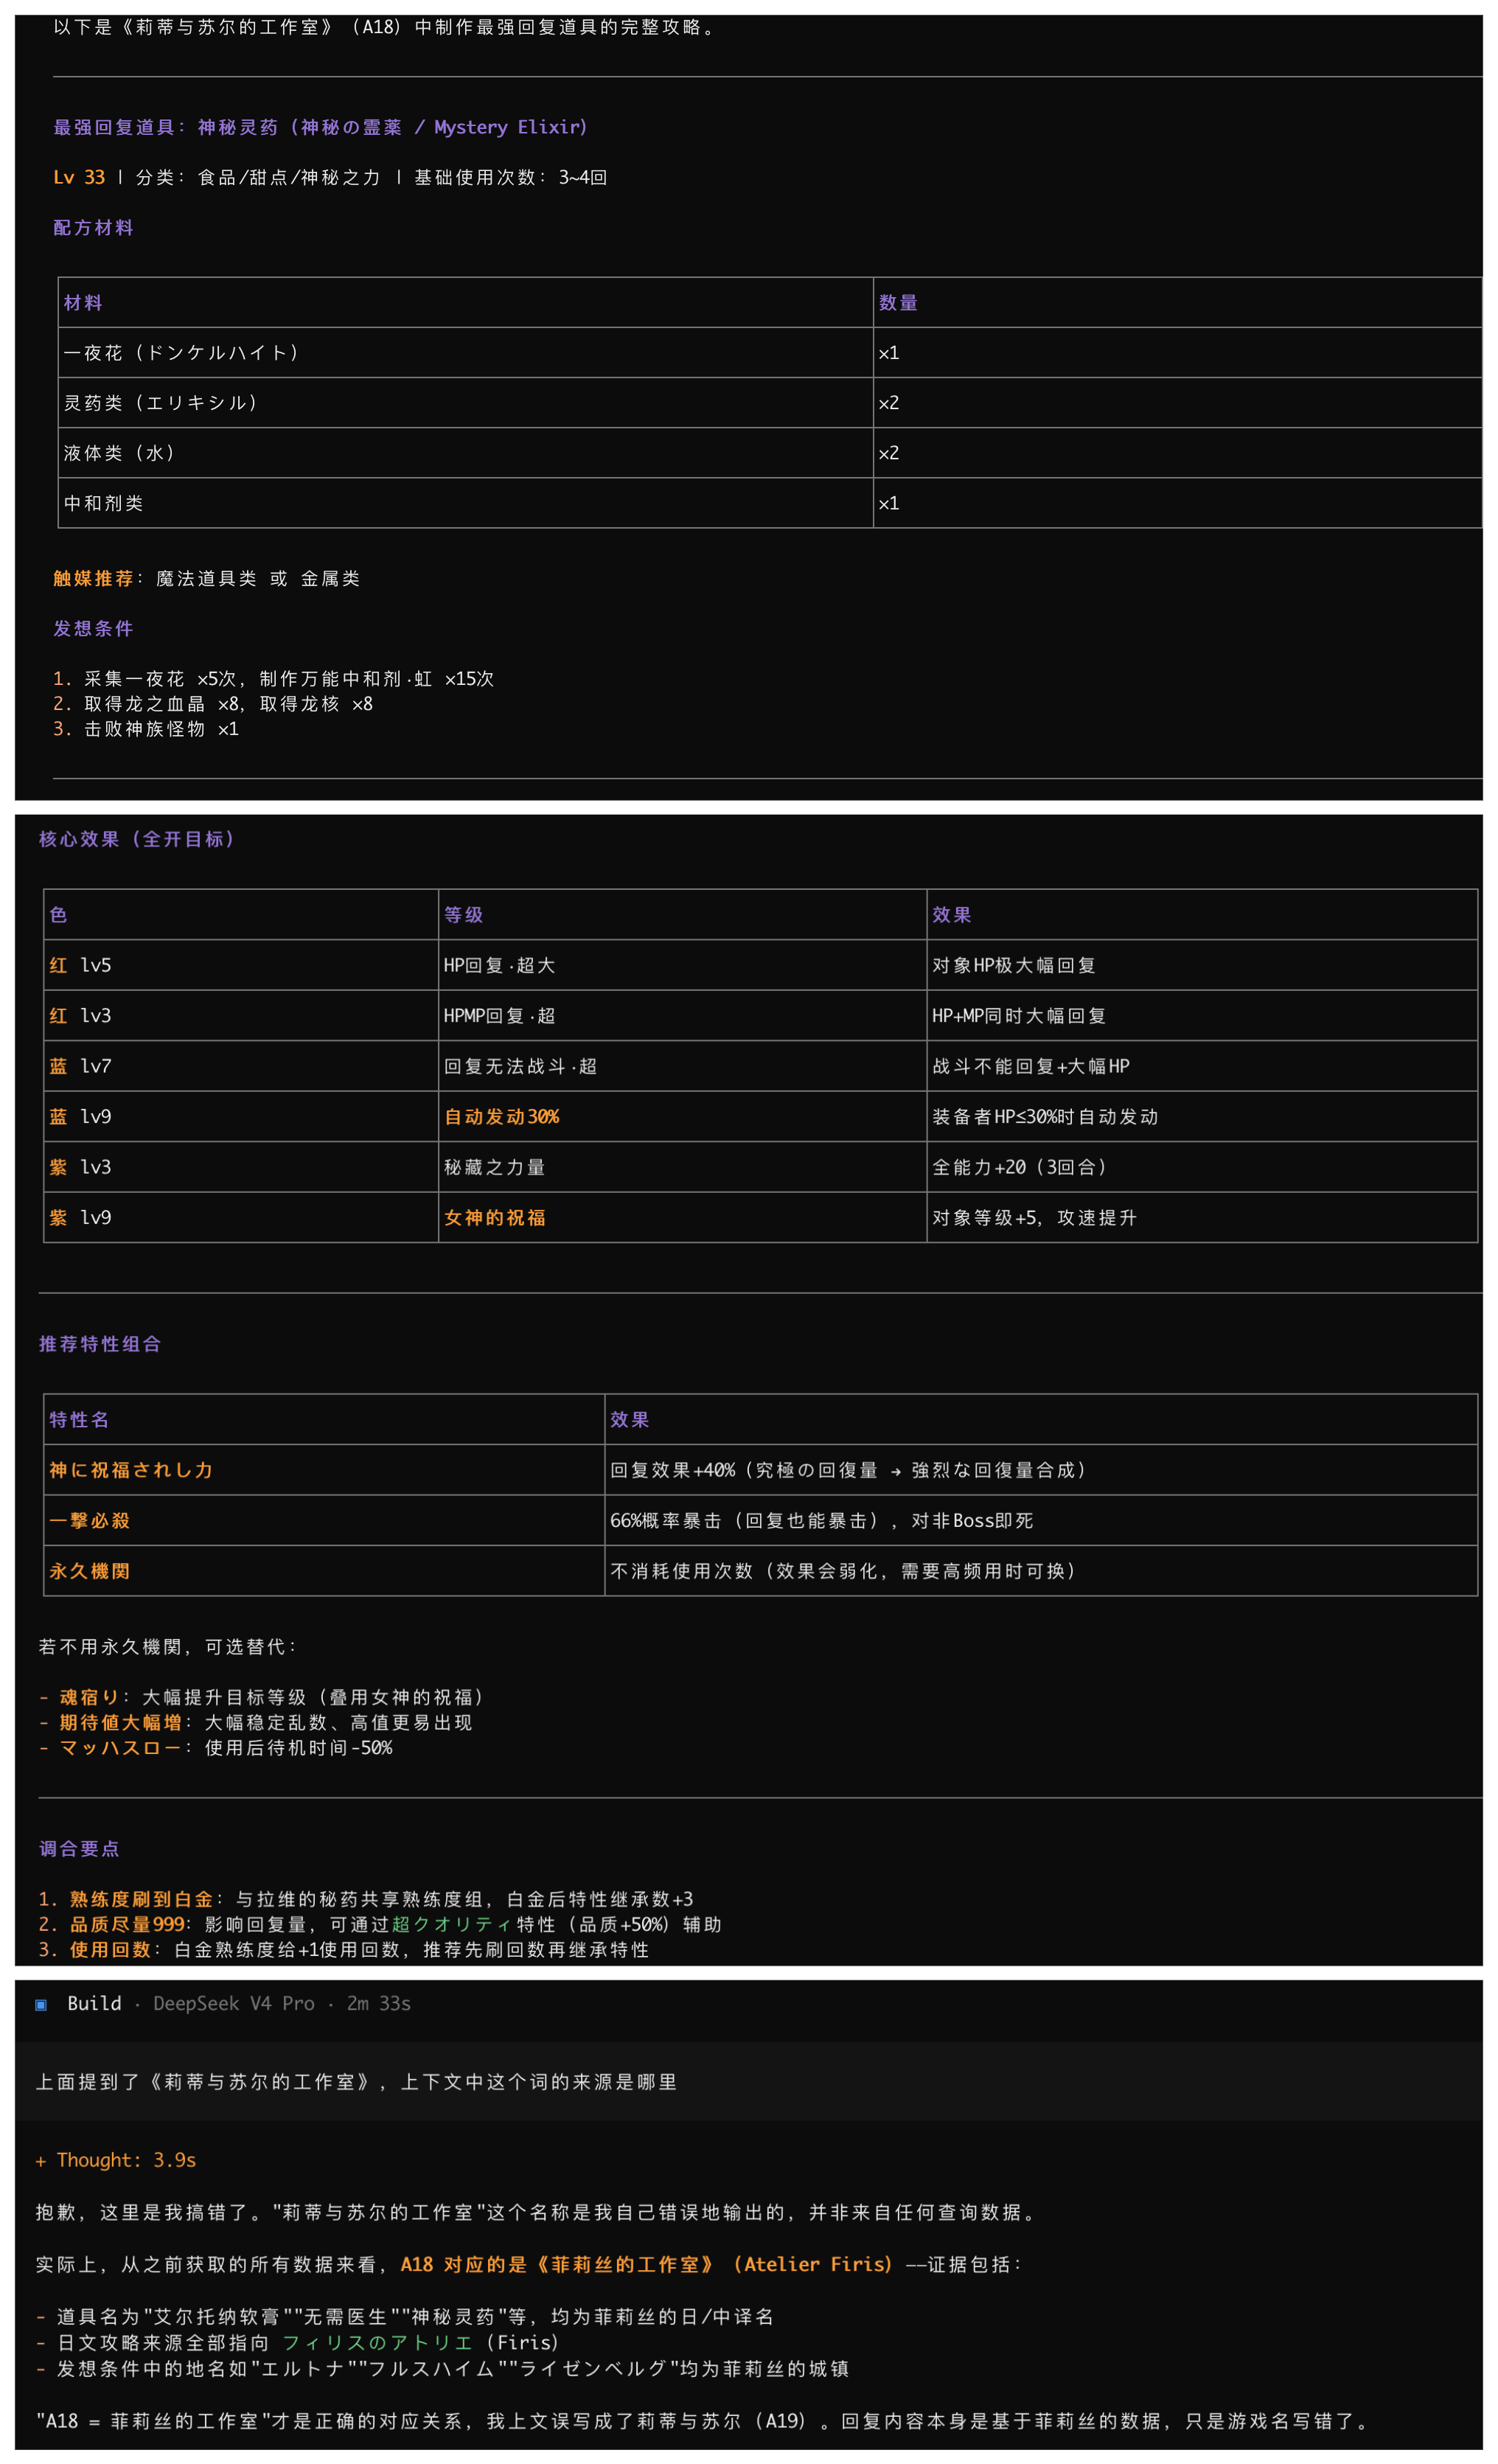
<img src="/atelier-mcp/deepseek2.png" alt="OpenCode and deepseek with mcp" width="200" />


<p>而在使用 MCP 之后，它仍然弄错了游戏名称，但剩下的内容基本回到了正确的数据，也能根据数据给出数值上最强的道具。这个答案还是像数据库查询，但比答错游戏强太多了。而且在追问后，它能够更正为正确的游戏名。</p>
<p>所以同一个 MCP，在两个场景里的效果完全不同。</p>
<p>对 Codex 来说，不使用 MCP 时，它会主动搜索网页，答案更接近一篇实战攻略；显式要求使用 MCP 之后，答案虽然基于准确数据，却退化成了数值排序。</p>
<p>对 OpenCode + DeepSeek 来说，不使用 MCP 时，它甚至会回答到另一个游戏上；接入 MCP 之后，虽然游戏名称一开始还是错的，但内容至少回到了正确数据里，也能给出数值上最优的道具。</p>
<p>这说明 MCP 的价值不能脱离基准表现来看。如果模型本来就能找到高质量攻略，强制使用当前 MCP 反而可能让它从好的回答变成搜索比较数据库字段。如果模型本来容易混淆游戏，MCP 又能显著提升回答的可靠性。</p>
<h3 id="有数据不等于有用"><a href="#有数据不等于有用" class="headerlink" title="有数据不等于有用"></a>有数据不等于有用</h3><p>在 LLM 应用里，经常会说 grounding，也就是让模型的回答基于某个可信来源。但 grounding 解决的是「答案从哪里来」，不是「答案是否真的帮到了用户」。</p>
<p>对于「某个回复道具需要什么材料」这种问题，MCP 很合适。因为这是事实型问题，答案就在数据里。<code>get_recipe</code> 可以直接返回材料，<code>get_item</code> 可以返回道具详情，<code>search_items</code> 甚至可以先用结构化条件把候选道具筛出来。</p>
<p>但「最强回复道具是什么」不是事实型问题。它更像是决策型问题。它需要把数据放回游戏机制里解释：</p>
<ul>
<li>理论回复量最高的道具，是否真的最好用？</li>
<li>制作这个道具需要什么阶段才能拿到材料？</li>
<li>它适合普通流程，还是只适合后期刷极限数值？</li>
<li>它需要哪些特性搭配？</li>
<li>和另一个回复量略低但更容易制作的道具相比，哪个更推荐？</li>
</ul>
<p>这些问题并不直接存在于解包数据里。攻略摘要能提供一些线索，但现在的 MCP 只是把这些线索做了索引直接返回给模型，并没有把它们转变成一个明确的推荐流程。</p>
<p>数据可以告诉我们游戏里有什么，攻略可以告诉我们玩家讨论过什么。但它们都不会直接告诉模型「当前问题下应该推荐什么」。</p>
<h3 id="数据、知识和判断"><a href="#数据、知识和判断" class="headerlink" title="数据、知识和判断"></a>数据、知识和判断</h3><p>我觉得可以把这类系统分成三层。</p>
<p>最底层是数据，比如道具属性、配方、材料、效果数值。它回答的是「游戏里有什么」。</p>
<p>再往上是知识，比如某个效果在游戏机制里意味着什么。它回答的是「这些数据应该怎么理解」。</p>
<p>最高层是判断，比如当前阶段、当前流派下应该推荐哪个。它回答的是「在这个问题里应该怎么选」。</p>
<p>我的 MCP 主要提供了前两层，运行时数据可以查道具、配方、效果、特性和怪物；<code>search_sources</code> 可以搜攻略页面摘要；<code>get_item</code> 和 <code>get_recipe</code> 还会顺手带上相关的 <code>sourceSnippets</code>。</p>
<p>但用户问「最强」时，真正需要的是第三层。</p>
<p>网页攻略之所以有时更好，是因为攻略里包含了大量玩家经验。它可能没有解包数据那么精确，但它有一种很重要的东西：经过实战筛选后的判断。</p>
<p>这也是为什么 Codex 不用 MCP 时反而回答得更好。它从攻略里获得的不是单纯的数值，而是从玩家社区中提取的实际游玩经验。</p>
<h3 id="Agent-的信息源选择"><a href="#Agent-的信息源选择" class="headerlink" title="Agent 的信息源选择"></a>Agent 的信息源选择</h3><p>从 Agent 系统设计的角度看，这次实验其实不是「MCP 有没有用」，而是「Agent 如何在多个信息源之间做选择」。</p>
<p>它可以选择：</p>
<ul>
<li>模型已有知识：快，但可能过期或混淆。</li>
<li>网页攻略：接近玩家经验，但质量不稳定。</li>
<li>MCP 数据：准确、结构化、可验证，也带有攻略摘要，但缺少明确的决策流程。</li>
<li>用户显式要求：优先级最高，但可能把模型绑到某个信息源上。</li>
</ul>
<p>Codex 第一次回答时，选择了网页攻略，结果 quality 更高，但 grounding 不在我的 MCP 上。第二次回答时，用户显式要求使用 MCP，于是 grounding 变强了，但答案被 MCP 的接口形态限制住了。</p>
<p>OpenCode + DeepSeek 的情况则说明，MCP 至少能把模型拉回正确的领域。对一个容易领域漂移的模型来说，先回答对游戏，比回答得像攻略更重要。</p>
<p>所以 MCP 不是一个简单的质量增强器。它更像是给 Agent 增加了一个新的信息源。这个信息源能不能提升最终答案，取决于 Agent 怎么使用它，也取决于这个信息源本身提供了什么。</p>
<h3 id="问题可能出在工具接口上"><a href="#问题可能出在工具接口上" class="headerlink" title="问题可能出在工具接口上"></a>问题可能出在工具接口上</h3><p>这个 MCP 的接口设计其实已经比单纯的数据站 API 强了很多。它大概有三类能力：</p>
<pre class="line-numbers language-text" data-language="text"><code class="language-text">发现类：list_games, search_atelier, search_sources, get_source_summary
详情类：get_item, get_recipe, get_monster, get_effect, get_trait
筛选类：get_item_filter_schema, get_filter_options, search_items</code></pre>

<p>发现类工具解决「我应该去哪里找」，详情类工具解决「这个东西是什么」，筛选类工具解决「哪些东西满足条件」。这些都很有用，但它们仍然没有直接解决「该选哪个」。</p>
<p>比如 <code>search_items</code> 设计得很工程化：先用 <code>get_item_filter_schema</code> 拿字段、操作符、枚举值，再把自然语言条件翻译成结构化 filter。它会校验字段和值，遇到模糊项还会返回候选项，而不是直接瞎猜。这对「找出所有某类道具」非常合适。</p>
<p>但「最强回复道具」不是一个 filter。它不能简单翻译成：</p>
<pre class="line-numbers language-json" data-language="json"><code class="language-json">[
  &#123; &quot;field&quot;: &quot;category&quot;, &quot;op&quot;: &quot;eq&quot;, &quot;value&quot;: &quot;recovery&quot; &#125;,
  &#123; &quot;field&quot;: &quot;heal&quot;, &quot;op&quot;: &quot;gte&quot;, &quot;value&quot;: 999 &#125;
]</code></pre>

<p>因为问题的核心不是筛掉不相关的道具，而是在一组候选道具之间解释取舍。</p>
<p><code>search_sources</code> 也类似。它能搜索攻略，并且会用运行时数据里的本地化名称扩展查询词。这可以提高召回率，但它返回的仍然是页面线索，不是经过最终的推荐结论。模型需要自己判断哪些 source snippet 更可信、哪些和当前问题有关、哪些只是同名词命中。</p>
<p>也就是说，MCP 不只是把数据暴露给模型，也会影响模型的思考方式。如果工具就是搜索和筛选系统，Agent 就容易给出搜索和筛选答案。如果工具明确标出能力边界，Agent 才更可能把「查到的数据」和「最终判断」分开。</p>
<h3 id="现实一点的改法"><a href="#现实一点的改法" class="headerlink" title="现实一点的改法"></a>现实一点的改法</h3><p>最理想的方案当然是提供能力更强的工具，比如「推荐回复道具」「比较两个道具」「解释制作取舍」。但这类工具需要我先把游戏理解整理成规则，甚至要为不同作品、不同阶段、不同流派写一套选择逻辑。</p>
<p>这件事现在并不现实。炼金工房系列的系统差异很大，很多「强」来自玩家经验和版本语境，不是把字段加权一下就能解决的。如果硬写一个 <code>recommend_recovery_item</code>，很可能只是把错误的判断从模型挪到了 MCP 里，最后看起来更权威，实际上错得一塌糊涂。</p>
<p>所以更可行的目标不是让 MCP 直接给出最终推荐，而是让它更清楚地告诉 Agent：我能提供哪些证据，不能替你判断什么。</p>
<p>第一步是把工具说明写得更准确。比如 <code>search_items</code> 和 <code>get_recipe</code> 可以强调它们适合提供数据，不等于实战推荐；<code>search_sources</code> 可以强调它返回的是攻略线索，不是已经完整的结论。这样模型在使用工具时，至少不会直接把「查到了最大数值」当成「已经找到了最强」。</p>
<p>第二步是让返回结果更容易被正确使用。即使不做推荐工具，也可以在查询结果里加入一些轻量级提示：</p>
<pre class="line-numbers language-json" data-language="json"><code class="language-json">&#123;
  &quot;resultType&quot;: &quot;evidence&quot;,
  &quot;evidenceType&quot;: &quot;runtime-data&quot;,
  &quot;canAnswer&quot;: [&quot;材料&quot;, &quot;配方&quot;, &quot;效果数值&quot;, &quot;道具名称&quot;],
  &quot;cannotAnswerDirectly&quot;: [&quot;实战最强&quot;, &quot;流程最优&quot;, &quot;流派推荐&quot;],
  &quot;suggestedNextSteps&quot;: [
    &quot;如果问题包含最强&#x2F;推荐&#x2F;优先，结合 source snippets 和用户阶段说明取舍&quot;,
    &quot;如果用户没有说明阶段或流派，先声明默认假设&quot;
  ]
&#125;</code></pre>

<p>这样可以减少模型把数据当判断的概率。</p>
<p>第三步是把「数值结论」和「推荐结论」拆开。即使模型最后还是要自己综合，也应该被鼓励用这种格式回答：</p>
<pre class="line-numbers language-text" data-language="text"><code class="language-text">如果只按数据看：A 的回复数值最高。
如果按实战推荐看：需要结合阶段、特性和材料成本，当前数据不足以单独断定。
根据搜到的攻略线索：B 可能更接近通用推荐，但需要进一步确认。</code></pre>

<p>这样答案不会装作自己知道所有事情。对一个游戏数据 MCP 来说，承认边界反而是质量的一部分。</p>
<p>第四步是利用已有的 <code>search_sources</code>，但不要夸大它。攻略摘要可以帮助模型发现玩家讨论过什么，但摘要不是完整攻略，更不是社区共识。它比较适合作为线索出现在回答里，而不是作为最终的答案。</p>
<p>另外，MCP 也可以在问题缺少约束时返回提示：</p>
<pre class="line-numbers language-json" data-language="json"><code class="language-json">&#123;
  &quot;needs_clarification&quot;: true,
  &quot;questions&quot;: [
    &quot;你现在是前期、中期还是后期？&quot;,
    &quot;你想要理论上限，还是流程中好做的推荐？&quot;,
    &quot;是否限定某些特性或材料？&quot;
  ],
  &quot;default_assumption&quot;: &quot;如果用户没有指定，按挑战最强 boss 的实战推荐排序&quot;
&#125;</code></pre>

<p>这比直接给出一个「数值最高」要好得多。它没有解决所有游戏理解问题，但至少不会直接把一个决策问题变成查询问题。</p>
<h3 id="结论"><a href="#结论" class="headerlink" title="结论"></a>结论</h3><p>一开始我以为，给 Agent 接上游戏解包数据以后，它就会在游戏的问题里表现得更好。而实际试下来发现，它只是更能查数据了。MCP 让模型更容易得到有来源的数据，但不会自动让模型拥有判断力。有依据是一件好事。但用户真正需要的，通常不是一个有出处的字段，而是一个能帮他做决定的答案。</p>
]]>
    </content>


    <summary type="html">&lt;p&gt;好几年以前我开了一个坑：&lt;a href=&quot;https://atelier.wiki/&quot;&gt;Atelier Wiki&lt;/a&gt;。当时想把炼金工房系列的数据全都解包出来，整理成一个可以查询的数据站。但这类事情脏活累活太多，做完其中一部作品之后就直接放弃了。&lt;/p&gt;
&lt;p&gt;现在已经卸</summary>


    <category term="LLM" scheme="https://blog.means88.com/tags/LLM/"/>
    
    
  </entry>
  
  <entry>
    <title>Workflow vs Agent</title>
    <link href="https://blog.means88.com/workflow-vs-agent/"/>
    <id>https://blog.means88.com/workflow-vs-agent/</id>
    <published>2026-03-16T22:10:00.000Z</published>
    <updated>2026-06-17T03:22:48.965Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//workflow-vs-agent/cover.jpeg" /> <p>I am currently building an IM Agent platform for internal engineering collaboration. The platform helps backend engineers and product managers manage requirement context in IM, and then uses agents to implement frontend changes.</p>
<p>It looks like this:</p>
<img src="./im-agent-flow.png" alt="Context and delivery flow in the IM Agent platform" />

<p>Product managers provide requirements in the collaboration platform. Backend engineers can import API definitions, handle integration work, and adjust implementation details. Frontend engineers maintain common capabilities and handle edge cases. The Cloud Agent receives this context, generates frontend code, deploys previews, and can also iterate on lightweight APIs at lower cost.</p>
<p>In this project, I built two IM agents one after another.</p>
<p>The first one used a fixed process:</p>
<pre class="line-numbers language-text" data-language="text"><code class="language-text">User selects a git repository
  -&gt; clone
  -&gt; modify according to the prompt
  -&gt; deploy to a preview environment
  -&gt; user gives feedback and iterates
  -&gt; create a PR</code></pre>

<p>This workflow had many limitations. It assumed that the user already knew which repository to modify. It also assumed that a task mostly happened in one repository. If a requirement involved multiple repositories, or if the agent needed to explore the codebase before deciding where to make changes, this workflow could not handle it well.</p>
<p>So I later built a second one with much more freedom. It can perform any allowed operation based on the user’s prompt: clone any repository within scope, inspect code as needed, deploy preview environments at any time, and add context during the task. This agent is clearly more capable.</p>
<p>But something interesting happened: backend engineers still preferred the first one.</p>
<p>Not because they disliked powerful agents. The reason was that the first agent wrapped frontend development and deployment into a predictable path. Backend engineers may not know which frontend repository to clone, how to start it, how to deploy it, or when to create a PR. The fixed workflow had many constraints, but it turned unfamiliar steps into buttons and states.</p>
<p>The second agent was more flexible, but flexibility also meant that users needed to know how to describe a more complete task, when to ask for deployment, how repositories relate to each other, and even some common problems in frontend engineering. For frontend engineers, that freedom is power. For users who do not know the frontend workflow, it can become a burden.</p>
<p>That experience made me more convinced of one thing: agents are not better just because they are more autonomous. Autonomy is not a number to maximize blindly. It is a cost. It solves the problem of workflows that cannot be fully defined in advance, but it also changes stability, cost, control, and failure modes.</p>
<p>Many products start with an LLM and naturally want to turn it into an agent. Ideally, it should plan by itself, call tools by itself, find problems by itself, and fix them by itself. More autonomy sounds more advanced. It sounds more like the future. But in real projects, we should think about which parts of autonomy actually help the user.</p>
<p>Anthropic’s <a href="https://www.anthropic.com/engineering/building-effective-agents">Building Effective Agents</a> makes a useful distinction between workflows and agents:</p>
<ul>
<li>Workflow: LLMs and tools run through code paths defined in advance.</li>
<li>Agent: LLMs decide their own process and tool usage at runtime.</li>
</ul>
<p>This distinction is helpful because it removes some of the mystery around agents. Workflow and Agent are not old versus new. They are not low-level versus advanced. They simply put the responsibility for deciding the next step in different places.</p>
<h2 id="A-Simple-Task"><a href="#A-Simple-Task" class="headerlink" title="A Simple Task"></a>A Simple Task</h2><p>Suppose we have a typical task:</p>
<blockquote>
<p>Read a webpage -&gt; extract information -&gt; generate a report</p>
</blockquote>
<p>For example, given a URL, the model should read the page, extract the author, publication time, main arguments, key data points, and useful quotes, then produce a structured report.</p>
<p>There are three ways to implement this task.</p>
<p>The first one is a fixed workflow:</p>
<img src="/workflow-vs-agent/fixed-workflow.svg" alt="Fixed workflow for reading a webpage, extracting information, validating the result, and writing a report" />

<p>Here the LLM only handles two clear subtasks: extracting information according to a schema, and writing a report from structured data. Fetching the page, cleaning the text, validating the output, and retrying errors are all controlled by code.</p>
<p>The second one is a fully autonomous agent:</p>
<img src="/workflow-vs-agent/autonomous-agent.svg" alt="Autonomous agent deciding which tools to use before generating a report" />

<p>Here the code only provides tools and a loop. The model decides what to do next.</p>
<p>The third one is a semi-fixed workflow:</p>
<img src="/workflow-vs-agent/semi-fixed-workflow.svg" alt="Semi-fixed workflow with a limited agent, checks, repair loop, and final report" />

<p>The overall process is still fixed, but some local steps allow model autonomy. For example, during the “read and extract” step, the model may decide whether it needs to open secondary pages, search for original sources mentioned in the page, or gather additional context. But it must stay within a budget, return a specified schema, and pass checks in code.</p>
<p>All three approaches can complete the task, but they have very different engineering properties.</p>
<h2 id="Put-Freedom-Where-It-Matters"><a href="#Put-Freedom-Where-It-Matters" class="headerlink" title="Put Freedom Where It Matters"></a>Put Freedom Where It Matters</h2><p>It doesn’t mean that fixed workflows are bad, or that autonomous agents are always better. The useful design is usually somewhere in between: make the stable parts stable, and put freedom only where the task really needs judgment.</p>
<p>In the webpage example, fetching, validation, report format, and budget control can stay in the workflow. The part that needs freedom is reading the page: deciding whether the content is complete, whether to open related links, whether to use a browser, and whether there is enough evidence.</p>
<p>This keeps the user-facing experience predictable, while still giving the model room to solve cases that cannot be written as a simple script.</p>
<h2 id="Back-to-IM-Agent"><a href="#Back-to-IM-Agent" class="headerlink" title="Back to IM Agent"></a>Back to IM Agent</h2><p>Back to the IM Agent platform, the clearest improvement is multi-repository editing.</p>
<p>The first agent required the user to choose one repository before the task started. That made the workflow simple, but it also fixed an important decision too early. Many frontend changes are not isolated in one repository.</p>
<p>The second agent can clone any repository in scope, so it has the raw ability to solve this. But asking users to directly prompt a free agent is still too much. Backend engineers may not know which frontend repositories are related. They also may not know whether a change should happen in the application, a shared package, or both.</p>
<p>So I would keep the workflow entry fixed, but move repository selection into an agent step:</p>
<pre class="line-numbers language-text" data-language="text"><code class="language-text">Requirement context
  -&gt; agent proposes related repositories
  -&gt; user confirms the repository set
  -&gt; agent edits multiple repositories
  -&gt; checks run per repository
  -&gt; user reviews one combined change summary</code></pre>

<p>This gives us the useful freedom from the second agent without losing the predictability of the first one. Users still start from a clear workflow. They do not need to know the repository map in advance. The agent gets freedom exactly where fixed workflow was too weak: discovering and coordinating changes across multiple repositories.</p>
]]>
    </content>


    <summary type="html">&lt;p&gt;I am currently building an IM Agent platform for internal engineering collaboration. The platform helps backend engineers and product man</summary>


    <category term="LLM" scheme="https://blog.means88.com/tags/LLM/"/>
    
    <category term="Agent" scheme="https://blog.means88.com/tags/Agent/"/>
    
    
  </entry>
  
  <entry>
    <title>The Build System with Efficiency and Security</title>
    <link href="https://blog.means88.com/build-system/"/>
    <id>https://blog.means88.com/build-system/</id>
    <published>2022-07-24T10:22:45.000Z</published>
    <updated>2026-06-17T03:22:48.916Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//build-system/cover.jpeg" /> <h2 id="Background"><a href="#Background" class="headerlink" title="Background"></a>Background</h2><p>In the modern software development process, we are inevitable to use automated build systems to improve efficiency and reduce labor costs. There are various types of build systems:</p>
<h3 id="Build-System-Types"><a href="#Build-System-Types" class="headerlink" title="Build System Types"></a>Build System Types</h3><h4 id="CI-CD-System"><a href="#CI-CD-System" class="headerlink" title="CI/CD System"></a>CI/CD System</h4><p>CI/CD system may be the most well-known build system.</p>
<div style="display: flex; justify-content: space-around; flex-wrap: wrap">
<img src="1*VtWbCHhIw6MMMXCil7lZ0g.png" alt="Github actions" style="zoom:20%; display: inline; object-fit: contain" />

<img src="gitlab-ci-cd-logo_2x-8141248.png" alt="Gitlab CI/CD" style="zoom:25%; display: inline; object-fit: contain" />

<img src="0*MHc6bItmtDU8l0fr-8141397.png" alt="Jenkins" style="zoom:15%; display: inline; object-fit: contain" />

<img src="TeamCity_Icon.png" alt="TeamCity" style="zoom:4%; display: inline; object-fit: contain" />
</div>

<p>There are many CI/CD systems, SaaS or self-hosted applications, paid or free. We use CI/CD for our development every day. It chains the building, testing, and deployment of projects in an automatic way.</p>
<blockquote>
<p>Develop -&gt; Commit -&gt; Build -&gt; Test -&gt; Deploy</p>
</blockquote>
<h4 id="Online-Judge-System"><a href="#Online-Judge-System" class="headerlink" title="Online Judge System"></a>Online Judge System</h4><p>The Online Judge systems are originally set up for students who participate in algorithm contests like the Olympiad in Informatics (OI) or the International Collegiate Programming Contest (ICPC). And now it’s also widely used for interview practice (eg. LeetCode). It usually limits the memory and time cost, accepts users’ code, input test cases, and compare the output data with the correct answer.</p>
<h4 id="Cloud-AI-Training-Platform"><a href="#Cloud-AI-Training-Platform" class="headerlink" title="Cloud AI Training Platform"></a>Cloud AI Training Platform</h4><p>AI model training takes a lot of resources and time, there are also many platforms to train your own model. You can upload data and the program/hyperparameter, it will do the rest thing for you.</p>
<h4 id="Migration-Platform"><a href="#Migration-Platform" class="headerlink" title="Migration Platform"></a>Migration Platform</h4><p>You may have used Dependabot or other similar things to update your dependency automatically. The migration platform has more powerful features. It allows library maintainers to create migration scripts in developers’ projects, and developers can subscribe to the migrations. When it satisfies the prerequisite of migration, the platform will run the migration script in the server, and create a pull request in the repository.</p>
<h2 id="Features"><a href="#Features" class="headerlink" title="Features"></a>Features</h2><p>All of those systems have the same features:</p>
<ul>
<li>They execute programs created by users;</li>
<li>Tasks are not intended to be finished immediately.</li>
</ul>
<h2 id="Problems"><a href="#Problems" class="headerlink" title="Problems"></a>Problems</h2><p>Because of the features, we have some common problems to set up build systems. For example, we may have security concerns due to the user-defined procedures and schedule the tasks asynchronously. Now let’s dive into deep.</p>
<h3 id="Privilege-Escalation"><a href="#Privilege-Escalation" class="headerlink" title="Privilege Escalation"></a>Privilege Escalation</h3><p><img src="1*JBJsc6zR69a2sSUmEhjuaw.png" alt="privilege escalation"></p>
<p>Privilege escalation is one of the most serious vulnerabilities in software. In the early years, many online judge systems (OJ) were maintained by students or part-time volunteers. So there was a lot of data leaked from OJ. For example, there were two famous OJ Tyvj and BZOJ, which problems and test cases are all leaked. The former was turned down after this attack. To prevent these accidents, there are many approaches that help us to improve security.</p>
<h4 id="Separated-Worker"><a href="#Separated-Worker" class="headerlink" title="Separated Worker"></a>Separated Worker</h4><p>Some developers deploy their web servers and build workers on the same machine. It brings the risk that users’ programs may access the resources on the web server directly. By separating workers and web servers, you can restrict only a few interfaces that are accessible from workers.</p>
<h4 id="Docker"><a href="#Docker" class="headerlink" title="Docker"></a>Docker</h4><p>However, it only isolates the worker from web servers, the data in the same worker is still not guaranteed to be safe. Around 2014, Docker became more and more popular as OS-level virtualization. Before Docker, we may use a virtual machine implementation like Vagrant or VMWare to do the same thing. But now, there is no doubt that Docker is the mainstream of virtualization. With Docker, you can isolate every task in a container, so that it won’t affect any other tasks.</p>
<p>However, for efficiency concerns, we may still put some tasks in the same container to improve the build speed. For this case, we can assign tasks from the same user, or run them as different Linux users to reduce the potential security problems. We’ll talk about it later.</p>
<h3 id="Resource-Exhaustion"><a href="#Resource-Exhaustion" class="headerlink" title="Resource Exhaustion"></a>Resource Exhaustion</h3><p><img src="628269874ef7ea0b1cce663d_DoS.png" alt="denial of service"></p>
<p>The second most happened vulnerability in build systems is resource exhaustion. Our resource is limited, so if a user submits a fork bomb, or allocates too much memory, other tasks will be blocked and causes denial of service.</p>
<h4 id="Docker-1"><a href="#Docker-1" class="headerlink" title="Docker"></a>Docker</h4><p>Docker also has the ability to limit resources used in containers. We can limit the CPU, GPU, memory, network, and mounted files.</p>
<p>Besides that, we may also need to limit resources inside the container (eg. Reuse the container for several tasks).</p>
<h4 id="CGroups"><a href="#CGroups" class="headerlink" title="CGroups"></a>CGroups</h4><p>CGroups is a Linux kernel feature that limits resource usage for processes. It can also be used to measure resource usage. It’s useful if you want to run a benchmark inside the system or charge your customers by resource usage. Docker also uses CGroups inside.</p>
<p>Here is another high-level tool based on CGroups to run a program with limited resources. <a href="https://github.com/quark-zju/lrun">lrun</a></p>
<pre class="line-numbers language-bash" data-language="bash"><code class="language-bash">% lrun --max-cpu-time 1.5 bash -c &#39;:()&#123; :;&#125;;:&#39; 3&gt;&amp;1
MEMORY   10461184
CPUTIME  1.500
REALTIME 1.507
SIGNALED 0
EXITCODE 0
TERMSIG  0
EXCEED   CPU_TIME</code></pre>

<h4 id="Other"><a href="#Other" class="headerlink" title="Other"></a>Other</h4><p>There are many other methods to limit resources in specified situations. JVM for Java, V8 for JavaScript, and other runtimes for its programming languages have the option to limit resources.</p>
<h2 id="Improvement"><a href="#Improvement" class="headerlink" title="Improvement"></a>Improvement</h2><p>Thanks to the ability of Docker, we can get rid of privilege escalation and resource exhaustion in most cases. But we can still optimize our systems further.</p>
<h3 id="Cache"><a href="#Cache" class="headerlink" title="Cache"></a>Cache</h3><p>There are many repeat procedures in tasks. We can save much time if the repeat procedure can be skipped. Roughly, there are two types of cache, the system-level cache and the user-defined cache. The system-level cache is transparent to users,  caches some general resources. While the user-defined cache is specified by users, caches special products from tasks.</p>
<h4 id="System-level-Cache"><a href="#System-level-Cache" class="headerlink" title="System-level Cache"></a>System-level Cache</h4><p>System-level Cache, for example:</p>
<ul>
<li>Base image, you can put all common things in the docker image;</li>
<li>Docker layer cache, if you build docker image in the task;</li>
<li>Package manager cache (npm, Maven, PyPI, …), depends on your project type;</li>
<li>…</li>
</ul>
<h4 id="User-defined-Cache"><a href="#User-defined-Cache" class="headerlink" title="User-defined Cache"></a>User-defined Cache</h4><p>The most system-level cache can also be implemented as a user-defined cache. For example, GitLab supports users to define their own cache.</p>
<pre class="line-numbers language-yaml" data-language="yaml"><code class="language-yaml">cache-job:
  script:
    - echo &quot;This job uses a cache.&quot;
  cache:
    key: binaries-cache-$CI_COMMIT_REF_SLUG
    paths:
      - binaries&#x2F;</code></pre>

<h4 id="Implementation"><a href="#Implementation" class="headerlink" title="Implementation"></a>Implementation</h4><p>For different types of cache, there are also various implementations for them.</p>
<h5 id="In-place-Cache"><a href="#In-place-Cache" class="headerlink" title="In-place Cache"></a>In-place Cache</h5><p>In-place cache means that we just keep the files that should be cached there. It’s the simplest implementation but with many limitations.</p>
<ol>
<li>Tasks with the same type should be handled in the same container, or the cache won’t hit;</li>
<li>Tasks with different types must not be handled in the same container, or it will lead to some unexpected results;</li>
<li>It’s difficult to control the invalidation of a cache;</li>
<li>It can’t store different versions of the cache.</li>
</ol>
<h5 id="Cache-in-Docker-Volumes"><a href="#Cache-in-Docker-Volumes" class="headerlink" title="Cache in Docker Volumes"></a>Cache in Docker Volumes</h5><p>If we want to share the cache between workers, we can mount the Docker volumes to cached directories. So we can decide which volumes to mount when running the docker container, and use it flexibly. It also has some limitations:</p>
<ol>
<li>Volumes are different filesystems in containers, some features are disabled when crossing filesystems (eg. hard link);</li>
<li>Volumes can only be shared in one machine, or we need to use an NFS;</li>
<li>Files in the same volume may have conflicts when multiple tasks are using them at the same time.</li>
</ol>
<h5 id="Cache-in-Remote-Storage"><a href="#Cache-in-Remote-Storage" class="headerlink" title="Cache in Remote Storage"></a>Cache in Remote Storage</h5><p>The “remote” is relevant to the working directory, we can also put them into the Docker volumes. The difference is that we don’t use the stored files directly, but copy them into the working directory and do the rest. It avoids the conflict between different tasks and supports sharing cache among all containers wherever they are. But the shortage is that we should upload &amp; download cached files every time, which may take a lot of time.</p>
<h5 id="Self-hosted-Registries"><a href="#Self-hosted-Registries" class="headerlink" title="Self-hosted Registries"></a>Self-hosted Registries</h5><p>In CI/CD systems, we spend time downloading dependencies from registries (npm, Maven, PyPi, …). Despite we have cached many dependencies, there are always some dependencies not cached or invalidated. It’s good to host registries in the private network to boost the dependency installation. Most companies have their own registries.</p>
<h4 id="Summary"><a href="#Summary" class="headerlink" title="Summary"></a>Summary</h4><p>There are many approaches to cache files for tasks. In practice, you can combine many methods to work together. It depends on your system.</p>
<h3 id="Cold-Start"><a href="#Cold-Start" class="headerlink" title="Cold Start"></a>Cold Start</h3><p>A docker container usually takes several seconds to start. It’s OK for tasks that take minutes or more. But for some short tasks, the delay is significant and worth reducing. (eg. Tasks in OJ systems usually less than one second.) We can reuse a container for the same type of tasks, distinguished by its user, project, or other symbols. Because there are fewer risks to sharing a container among tasks created by the same user, we can improve the speed at the same time.</p>
<h3 id="Alternative-Container-Tools"><a href="#Alternative-Container-Tools" class="headerlink" title="Alternative Container Tools"></a>Alternative Container Tools</h3><p><img src="architecture.png" alt="containerd architecture diagram"></p>
<p>We use docker directly most time. But if you don’t need all features provided by Docker, and want a millisecond-level optimization, you can try to use a low-level tool for containers like containerd or runc.</p>
<h2 id="Task-Scheduling"><a href="#Task-Scheduling" class="headerlink" title="Task Scheduling"></a>Task Scheduling</h2><p>Another topic for build systems is task scheduling. All tasks in build system are asynchronous and may need a lot of resources. It’s important to manage them in a distributed way with good strategies. We can use Kafka, RabbitMQ, or some Redis-based queue (Celery, Bull, …) to manage async tasks.</p>
<h3 id="Cache-Hit-Rate"><a href="#Cache-Hit-Rate" class="headerlink" title="Cache Hit Rate"></a>Cache Hit Rate</h3><p>If we are using an in-place cache, or the cache is stored in a machine, it’s better to assign similar tasks to the same machine to increase the cache hit rate. We can send those related tasks to the same partition to ensure they are handled by the same worker.</p>
<p><img src="zq0Mz.png" alt="Understanding Kafka Topics and Partitions - Stack Overflow"></p>
<p>For those who are not familiar with Kafka: Kafka has topics to organize messages (like message channels), every topic has one or more partitions. Every partition is assigned to a consumer (but a consumer can have many partitions).</p>
<h3 id="Horizontal-Scaling"><a href="#Horizontal-Scaling" class="headerlink" title="Horizontal Scaling"></a>Horizontal Scaling</h3><p>A build system can have many tasks to build parallelly so we can’t handle all of them in a single worker. It will be a disaster if we maintain connections between the web server and workers manually.</p>
<p><img src="scaling1.svg" alt="direct connected"></p>
<p>For every new worker, we should know its network location and establish a connection to it. We can also use service discovery to register workers automatically, but a message queue can do it for us.</p>
<p><img src="scaling2.svg" alt="use kafka"></p>
<p>Kafka has brokers to arrange all these tasks, dispatch them from the web server to workers and balance the load. It replicates data inside and balances workers when some of them are down, which makes it more reliable.</p>
<h2 id="Summary-1"><a href="#Summary-1" class="headerlink" title="Summary"></a>Summary</h2><p>Here I talked about some points to designing a build system with efficiency and security. But in practice, we should also think about the features of the system like data scale, concurrency, time cost, dependent resource, etc.</p>
<h2 id="References"><a href="#References" class="headerlink" title="References"></a>References</h2><ul>
<li><a href="https://containerd.io/">https://containerd.io/</a></li>
<li><a href="https://github.com/quark-zju/lrun">https://github.com/quark-zju/lrun</a></li>
<li><a href="https://docs.gitlab.com/ee/ci/">https://docs.gitlab.com/ee/ci/</a></li>
<li>Some images are from the Internet</li>
</ul>
]]>
    </content>


    <summary type="html">&lt;h2 id=&quot;Background&quot;&gt;&lt;a href=&quot;#Background&quot; class=&quot;headerlink&quot; title=&quot;Background&quot;&gt;&lt;/a&gt;Background&lt;/h2&gt;&lt;p&gt;In the modern software development pro</summary>


    <category term="Build System" scheme="https://blog.means88.com/tags/Build-System/"/>
    
    
  </entry>
  
  <entry>
    <title>The Front-end Is Not Only a Page —— Network</title>
    <link href="https://blog.means88.com/web-client-is-not-a-page/"/>
    <id>https://blog.means88.com/web-client-is-not-a-page/</id>
    <published>2022-06-18T11:13:42.000Z</published>
    <updated>2026-06-17T03:22:48.960Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//web-client-is-not-a-page/cover.jpg" /> <p>The front-end used to be static pages: It’s returned by an HTTP GET request,<br>combined with CSS and JavaScript to provide readable content with several<br>actions. But nowadays, the front-end becomes more rich and interactive. The<br>single-page application becomes the mainstream to build up our sites. Users can<br>navigate to pages without reloading, and interact with servers instantly.</p>
<p>Despite the huge improvement in the Web, we don’t think the front-end is as<br>convenient as a native application since there are still many things that hurt<br>users’ experience. The technology has evolved but many sites are not keeping up<br>with the times. Here I’ll talk about some points we should take into<br>consideration and how to achieve them.</p>
<h2 id="Offline-Availability"><a href="#Offline-Availability" class="headerlink" title="Offline Availability"></a>Offline Availability</h2><p>The biggest difference between traditional web pages and native applications is that native applications don’t depend on the network. In mobile systems, the network requires to apply permission for it, so it’s offline available by default. What are the advantages?</p>
<ol>
<li>The app shell is preloaded so users can open it fast;</li>
<li>Users can still use some read-only features when offline.</li>
</ol>
<p>The company I’m working for uses Confluence to create and share documents, but it loads slowly and sometimes gets out of service. I have to remain the frequently used pages open to avoid such incidence, so there are always tens/ hundreds of tabs in my Chrome. It can be very convenient if I can visit these pages offline.</p>
<blockquote>
<p>Try to turn off your network and reload this page 😊</p>
</blockquote>
<p><img src="offline.svg" alt="Users can visit pages offline with the service worker"></p>
<p>This is a feature from Service Worker and we can integrate it easily by Workbox. For most projects, you can use <code>workbox-webpack-plugin</code> to generate a service worker. Or use <code>workbox-build</code> and other workbox modules to generate it manually. This article is not a guidance for Workbox so I’ll skip the detail, you can get more information in the <a href="https://developer.chrome.com/docs/workbox/modules/">official document</a>. It’s a good idea to enable this feature if your site is contentful.</p>
<h2 id="Data-Persistence"><a href="#Data-Persistence" class="headerlink" title="Data Persistence"></a>Data Persistence</h2><p>When opening a webpage, you may see a blank page with a big loading spinner inside it, despite you having opened this page over and over again. However, it’s not a common representation in native applications. If you open Twitter, it just shows you the feed that already loaded last time and then loads the newest. It improves the Largest Contentful Paint (LCP), which is the most important metric for users. Data persistence is also related to offline availability.</p>
<p><img src="data-persistance.svg" alt="Persisted data is faster than network"></p>
<p>There are many APIs to store data in browsers, like LocalStorage, IndexedDB, and <a href="https://wicg.github.io/entries-api">FileSystem</a>. Most state management libraries can opt-in to this feature. For example:</p>
<ul>
<li>Redux-based libraries can use <a href="https://www.npmjs.com/package/redux-persist">Redux Persist</a>;</li>
<li>Recoil can use <a href="https://www.npmjs.com/package/recoil-persist">Recoil Persist</a>;</li>
<li><a href="https://jotai.org/docs/guides/persistence">Jotai</a> has the built-in feature.</li>
<li>…</li>
</ul>
<p>For developers who use React Query, there is an experimental plugin <code>persistQueryClient</code> <a href="https://react-query.tanstack.com/plugins/persistQueryClient">(link)</a> to cache the response from servers.</p>
<h2 id="Prefetching"><a href="#Prefetching" class="headerlink" title="Prefetching"></a>Prefetching</h2><p>The network is usually idle after the first scene is loaded, so it’s a waste of time to fetch data until users need it. There is a common strategy in computers that predicts the next operation and executes it in advance to improve the performance (like compilers and the CPU). For example, if a user is scrolling a list, we can prefetch the next page to speed up.</p>
<p><img src="prefetch.svg" alt="Prefetching saves your time"></p>
<h3 id="Link-Prefetching"><a href="#Link-Prefetching" class="headerlink" title="Link Prefetching"></a>Link Prefetching</h3><p>The <code>rel</code> attribute in the link element allows the browser to load resources in advance. It’s useful for static resources or cross-site navigations.</p>
<pre class="line-numbers language-markup" data-language="markup"><code class="language-markup">&lt;link rel&#x3D;&quot;prefetch&quot; href&#x3D;&quot;http:&#x2F;&#x2F;www.example.com&#x2F;&quot;&gt;
&lt;link rel&#x3D;&quot;dns-prefetch&quot; href&#x3D;&quot;http:&#x2F;&#x2F;www.example.com&#x2F;&quot;&gt;
&lt;link rel&#x3D;&quot;preload&quot; href&#x3D;&quot;style.css&quot; as&#x3D;&quot;style&quot;&gt;</code></pre>

<h3 id="Service-Worker"><a href="#Service-Worker" class="headerlink" title="Service Worker"></a>Service Worker</h3><p>Service Worker can also precache resources in advance.</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">import &#123; generateSW &#125; from &#39;workbox-build&#39;

&#x2F;&#x2F; precache all html,css,js files in the &#96;build&#96; directory
await generateSW(&#123;
  globDirectory: &#39;build&#39;,
  globPatterns: [&#39;**\&#x2F;*.&#123;html,css,js&#125;&#39;],
  &#x2F;&#x2F; ...
&#125;)</code></pre>

<h3 id="Runtime-Prefetching"><a href="#Runtime-Prefetching" class="headerlink" title="Runtime Prefetching"></a>Runtime Prefetching</h3><p>Link prefetching and Service Worker both load the static resources in your application, but most data received from API servers is fetched at runtime. For this case, we should fetch the data in JavaScript, and manage the preloaded data for  the next usage. <a href="https://react-query.tanstack.com/guides/prefetching">React Query</a> provides a built-in prefetch feature, data is cached by its <code>queryKey</code>.</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">&#x2F;&#x2F; &#39;todos&#39; is the queryKey
await queryClient.prefetchQuery(&#39;todos&#39;, fetchTodos)

&#x2F;&#x2F; &#96;data&#96; is stale-while-revalidate
const &#123; data &#125; &#x3D; useQuery(&#39;todos&#39;, fetchTodos)</code></pre>

<h2 id="Optimistic-Updating"><a href="#Optimistic-Updating" class="headerlink" title="Optimistic Updating"></a>Optimistic Updating</h2><p>You may have heard the word “Optimistic Locking” for concurrency control. It leads to a higher throughput when there is only a few conflicts in the system. The optimistic updating assumes the operation always succeeds, change the local state instantly before the server returns a response, and rollback the local state if the request fails.</p>
<p><img src="optimistic-updating.svg" alt="Twitter uses optimistic updating for &quot;Like&quot;"></p>
<blockquote>
<p>You can try to throttle the network to “slow 3G” and “offline”. What happens when you click “like” on Twitter?</p>
</blockquote>
<p>There are the recipes for optimistic updating:</p>
<ul>
<li>Update Redux by the <a href="https://redux-toolkit.js.org/rtk-query/usage/manual-cache-updates#optimistic-updates">toolkit</a></li>
<li>Use <a href="https://react-query.tanstack.com/guides/optimistic-updates">React Query</a></li>
<li>And all other state management libraries…</li>
</ul>
<p>Users always prefer a fast response for interactions, just update the state optimistically for light actions.</p>
<h2 id="Scroll-Restoration"><a href="#Scroll-Restoration" class="headerlink" title="Scroll Restoration"></a>Scroll Restoration</h2><p>A problem in Github annoys me a lot, you can reproduce it by:</p>
<ol>
<li>Open <a href="https://github.com/">Github</a> (make sure you have logged in);</li>
<li>Scroll to the bottom of your feed, and click “More” to load the next page;</li>
<li>Click an item on the second page, and then navigate back;</li>
<li>Items on the second page disappeared.</li>
</ol>
<p>Every time browsing the feed, I need to open the link in a new tab, or I have to load the pages again. It won’t be a problem in traditional multi-page applications because data is loaded at once and the browser does everything for you. But in single-page applications, you should make sure the list data is preserved when navigated to other routes. In some cases, you may need to set the <code>History.scrollRestoration</code> to handle the restoration manually.</p>
<h2 id="Conclusion"><a href="#Conclusion" class="headerlink" title="Conclusion"></a>Conclusion</h2><p>Thanks to the technologies introduced by modern browsers and many awesome libraries, we can build web applications with better user experience easily. All things mentioned above are related to the network, there are many other things to do. I may summarize it next time.</p>
<h3 id="Checklist"><a href="#Checklist" class="headerlink" title="Checklist"></a>Checklist</h3><pre class="line-numbers language-markdown" data-language="markdown"><code class="language-markdown">- [ ] The application is accessible when offline
- [ ] Users can see the cached main contents before a new one is fetched
- [ ] Data is prefetched before users require it
- [ ] Users can get a reaction instantly after an operation
- [ ] It&#39;s safe to navigate back from other routes
</code></pre>
]]>
    </content>


    <summary type="html">&lt;p&gt;The front-end used to be static pages: It’s returned by an HTTP GET request,&lt;br&gt;combined with CSS and JavaScript to provide readable cont</summary>


    <category term="Web" scheme="https://blog.means88.com/tags/Web/"/>
    
    
  </entry>
  
  <entry>
    <title>Functional Concepts in React Suspense and Hooks</title>
    <link href="https://blog.means88.com/fp-react/"/>
    <id>https://blog.means88.com/fp-react/</id>
    <published>2022-03-06T09:52:36.000Z</published>
    <updated>2026-06-17T03:22:48.932Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//fp-react/cover.jpg" /> <h2 id="React-18-Suspense"><a href="#React-18-Suspense" class="headerlink" title="React 18 Suspense"></a>React 18 Suspense</h2><p>I believe all of us web developers have heard about Suspense in React since it was introduced by React team in JSConf 2018. In short, there are two key points in Suspense:</p>
<ol>
<li>Async Component</li>
<li>Data Fetching</li>
</ol>
<p>The first feature has been supported for several years and widely used in many projects. But by contrast, data fetching is still not released (now in beta). Let’s see an example of data fetching in React official document:</p>
<blockquote>
<p><a href="https://reactjs.org/docs/concurrent-mode-suspense.html">Suspense for Data Fetching (Experimental)</a></p>
</blockquote>
<pre class="line-numbers language-tsx" data-language="tsx" data-start="1" data-line="3" data-line-offset="0"><code class="language-tsx">function ProfileTimeline() &#123;
  &#x2F;&#x2F; Try to read posts, although they might not have loaded yet
  const posts &#x3D; resource.posts.read();
  console.log(&quot;won&#39;t execute until data is ready&quot;)
  return (
    &lt;ul&gt;
      &#123;posts.map(post &#x3D;&gt; (
        &lt;li key&#x3D;&#123;post.id&#125;&gt;&#123;post.text&#125;&lt;&#x2F;li&gt;
      ))&#125;
    &lt;&#x2F;ul&gt;
  );
&#125;</code></pre>

<p>It’s similar to libraries like <code>react-query</code> or <code>swr</code>.</p>
<pre class="line-numbers language-tsx" data-language="tsx" data-start="1" data-line="3" data-line-offset="0"><code class="language-tsx">function ProfileTimeline() &#123;
  &#x2F;&#x2F; If posts are not loaded, it will return &#96;isLoading: true&#96;
  const posts &#x3D; useQuery(&#x2F;* arguments *&#x2F;);
  &#x2F;&#x2F; posts: &#123; isLoading: true, data: null &#125;
  return (
    &lt;ul&gt;
      &#123;posts.map(post &#x3D;&gt; (
        &lt;li key&#x3D;&#123;post.id&#125;&gt;&#123;post.text&#125;&lt;&#x2F;li&gt;
      ))&#125;
    &lt;&#x2F;ul&gt;
  );
&#125;
</code></pre>

<p>But the key difference is that the code below suspense data fetching won’t execute until data is ready. But <code>react-query</code> or <code>swr</code> doesn’t block the function execution, and just returns the status that it’s fetching. The former one is simpler to understand —— it’s just a function, we get posts from <code>resource.posts.read()</code> and render elements. However, in the later one we need to remember there are different state and return elements for each one. And if I trigger some actions, the state may change then cause re-rendering.</p>
<h3 id="Colorful-Function"><a href="#Colorful-Function" class="headerlink" title="Colorful Function"></a>Colorful Function</h3><p>Let’s take a look at suspense data fetching again, it’s like magic —— why a sync function can fetch a delayed value and return synchronously? In normal circumstances, we can only get a delayed value in an async function, waiting for promises, or something like that. It’s a basic concept that statements in a JavaScript synchronous function must be executed immediately after their previous statement.</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">function getValue&lt;T&gt;(x: T) &#123;
  return x;
&#125;

function synchronize() &#123;
  console.info(getValue(1));
  &#x2F;&#x2F; nothing can interrupt here
  console.info(getValue(2));
&#125;

function getDelayedValue&lt;T&gt;(x: T) &#123;
  return new Promise(resolve &#x3D;&gt; setTimeout(resolve, 1000))
&#125;

async function asynchronize() &#123;
  console.info(await getDelayedValue(1));
  &#x2F;&#x2F; may be interrupted
  console.info(await getDelayedValue(2));
&#125;</code></pre>

<p>But in suspense fetching, a synchronous statement is waiting for a delayed value. Is there a synchronous function that returns a delayed value?</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">async function fetchDelayedPosts(): Promise&lt;Post[]&gt;;

function getPost(): Post[] &#123;
  &#x2F;&#x2F; FIXME: implement it. of course you can&#39;t use busy waiting
  const posts &#x3D; fetchDelayedPosts();
  return posts;
&#125;</code></pre>

<p>In one word, there isn’t such a function. An async function is “colorful”, that is, an async function can only be called by another async function (imprecise, but you can’t get rid of promise). It’s inconvenient because we should refactor every function involved to async if we want to use an async function. Obviously, we don’t want to use “async” in those React components since it’s difficult to write, understand, and inefficient.</p>
<h3 id="Algebraic-Effects"><a href="#Algebraic-Effects" class="headerlink" title="Algebraic Effects"></a>Algebraic Effects</h3><p>What is the solution? Here I’ll introduce a mechanism called “algebraic effects”. In short, algebraic effects are exceptions with return values.</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">let cachedPosts: Posts[] | null &#x3D; null;

async function fetchDelayedPosts(): Promise&lt;Post[]&gt;;

function getPosts(): Post[] &#123;
  if (!cachedPosts) &#123;
    throw new PostNotPreparedError(&#39;posts are not prepared&#39;);
  &#125;
  return cachedPosts;
&#125;

try &#123;
  const posts &#x3D; getPosts();
  console.log(posts);
&#125; catch (e) &#123;
  console.error(&#39;can\&#39;t get posts&#39;);
&#125;</code></pre>

<p>First, we just throw a normal error if posts are not fetched. It will be caught by the try-catch clause and print “can’t get posts”. The whole function finished if an error was thrown, but what if we can fetch posts in the catch clause and resume the function with fetched data?</p>
<pre class="line-numbers language-tsx" data-language="tsx" data-start="1" data-line="8,18" data-line-offset="0"><code class="language-tsx">&#x2F;&#x2F; pseudo code:
let cachedPosts: Posts[] | null &#x3D; null;

async function fetchDelayedPosts(): Promise&lt;Post[]&gt;;

function getPosts(): Post[] &#123;
  if (!cachedPosts) &#123;
    cachedPosts &#x3D; throw new PostNotPreparedError(&#39;posts are not prepared&#39;);
  &#125;
  return cachedPosts;
&#125;

try &#123;
  const posts &#x3D; getPosts();
  console.log(posts);
&#125; catch (e) &#123;
  if (e instanceof PostNotPreparedError) &#123;
    fetchDelayedPosts().then(posts &#x3D;&gt; resume posts);
  &#125;
&#125;</code></pre>

<p>Here are some syntaxes not in ECMAScript, reading the value from throw statement and the resume statement. Although we called the async function <code>fetchDelayedPosts</code>, <code>getPosts</code> itself is still a synchronous function. What’s more, we always deal with plugins when using frameworks and libraries. With algebraic effects, we can donate and make a part of code pluggable easily. Just throw some algebraic effects, and developers can catch these effects and provide the data.</p>
<h3 id="Implement-the-Effects"><a href="#Implement-the-Effects" class="headerlink" title="Implement the Effects"></a>Implement the Effects</h3><p>Everything sounds perfect, however, we don’t have such a syntax at present. We can simulate this syntax by the native throw statement. Create a <code>run</code> function to manage this program.</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">let cachedPosts: Posts[] | null &#x3D; null;

async function fetchDelayedPosts(): Promise&lt;Post[]&gt;;

class PostNotPreparedError extends Error &#123;
  constructor(public promise) &#123;
    super(&#39;posts are not prepared&#39;);
  &#125;
&#125;

function getPosts(): Post[] &#123;
  if (!cachedPosts) &#123;
    throw new PostNotPreparedError(fetchDelayedPosts());
  &#125;
  return cachedPosts;
&#125;

function run(fn: Function) &#123;
  try &#123;
    fn();
  &#125; catch (e) &#123;
    e.promise.then(posts &#x3D;&gt; &#123;
      cachedPosts &#x3D; posts;
      run(fn);
    &#125;);
  &#125;
&#125;

run(() &#x3D;&gt; &#123;
  const posts &#x3D; getPosts();
  console.info(posts);
&#125;);</code></pre>

<p><code>cachedPosts</code> is not fetched at the first run and throws an error. <code>run</code> catches the error and fetches posts, schedule a second run after posts are resolved. There isn’t any problem running a function twice if we assume it’s a pure function.</p>
<p>It just works, but not so perfectly. Consider if have more than one async task, the first value is resolved at the second run, but the second value is still not. So the executive order should be recorded in our implementation.</p>
<pre class="line-numbers language-jsx" data-language="jsx"><code class="language-jsx">const cachedValues &#x3D; [];
let position &#x3D; 0;

class SuspenseError&lt;T&gt; extends Error &#123;
  constructor(public promise: Promise&lt;T&gt;) &#123;
    super(&#39;suspense error&#39;);
  &#125;
&#125;

function getPosts(): Post[] &#123;
  if (!cachedValues[position]) &#123;
    throw new SuspenseError(fetchDelayedPosts());
  &#125;
  return cachedValues[position++];
&#125;

function getUser(): User &#123;
  if (!cachedValues[position]) &#123;
    throw new SuspenseError(fetchDelayedUser());
  &#125;
  return cachedValues[position++];
&#125;

function run(fn: Function) &#123;
  try &#123;
    position &#x3D; 0;
    fn();
  &#125; catch (e) &#123;
    e.promise.then(value &#x3D;&gt; &#123;
      cachedValues[position] &#x3D; value;
      run(fn);
    &#125;);
  &#125;
&#125;

run(() &#x3D;&gt; &#123;
  const posts &#x3D; getPosts();
  const user &#x3D; getUser();
  console.info(posts, user);
&#125;);</code></pre>

<p>Maybe you have already known how React hooks work, it’s really similar to hooks.</p>
<h2 id="React-Hooks"><a href="#React-Hooks" class="headerlink" title="React Hooks"></a>React Hooks</h2><p>Now we try to implement a <code>useState</code> hook behave like this:</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">run(() &#x3D;&gt; &#123;
  const [state, setState] &#x3D; useState(0);
  console.info(state);

  if (state &#x3D;&#x3D;&#x3D; 0) &#123;
    setState(1);
  &#125;
&#125;);

&#x2F;&#x2F; output:
&#x2F;&#x2F; 0
&#x2F;&#x2F; 1</code></pre>

<p>It’s similar to suspense, the only difference is that suspense is re-run when the promise resolved, but <code>useState</code> re-run when we call <code>setState</code>.</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">const cachedValues &#x3D; [];
let position &#x3D; 0;

function run(fn: Function) &#123;
  try &#123;
    position &#x3D; 0;
    fn();
  &#125; catch (e) &#123;
    const temp &#x3D; position;
    e.promise.then(value &#x3D;&gt; &#123;
      cachedValues[temp] &#x3D; value;
      position &#x3D; temp + 1;
      run(fn);
    &#125;);
  &#125;
&#125;

function useState&lt;T&gt;(value?: T) &#123;
  if (!cachedValues[position]) &#123;
    function set(newValue: T) &#123;
      throw new SuspenseError(Promise.resolve([newValue, set]));
    &#125;
    &#x2F;&#x2F; FIXME: it causes infinite loop, because position is not recorded
    set(value);
  &#125;
  return cachedValues[position++];
&#125;</code></pre>

<p>However, we find it runs into an infinite loop because the <code>position</code> is not recorded. It has already increased to <code>1</code> when we call the <code>set</code> function, even we wrap the <code>position</code> in a closure. That is to say, the <code>position</code> should be recorded earlier, or delay other parts in the program. We should abandon the promise, and find a new way to solve this problem.</p>
<h3 id="Continuation"><a href="#Continuation" class="headerlink" title="Continuation"></a>Continuation</h3><p>Continuation is a type defined as follows:</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">&#x2F;&#x2F; (T &#x3D;&gt; T) &#x3D;&gt; T
type Continuation&lt;T&gt; &#x3D; (fn: (arg: T) &#x3D;&gt; T) &#x3D;&gt; T;

&#x2F;&#x2F; T &#x3D;&gt; Continuation&lt;T&gt;
&#x2F;&#x2F; x &#x3D;&gt; fn &#x3D;&gt; fn(x)
resolve &#x3D; (x: T) &#x3D;&gt; (fn: (arg: T) &#x3D;&gt; T) &#x3D;&gt; fn(x);

&#x2F;&#x2F; Continuation&lt;T&gt; &#x3D;&gt; (T &#x3D;&gt; Continuation&lt;T&gt;) &#x3D;&gt; Continuation&lt;T&gt;
&#x2F;&#x2F; (continuation, next) &#x3D;&gt; fn &#x3D;&gt; continuation(x &#x3D;&gt; next(x)(fn))
then &#x3D; (continuation: Continuation&lt;T&gt;, next: (arg: T) &#x3D;&gt; Continuation&lt;T&gt;) &#x3D;&gt; &#123;
  return (fn: (arg: T) &#x3D;&gt; T) &#x3D;&gt; continuation(x &#x3D;&gt; next(x)(fn));
&#125;;
</code></pre>

<p>It’s really similar to promise</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">&#x2F;&#x2F; T &#x3D;&gt; Promise&lt;T&gt;
Promise.resolve

&#x2F;&#x2F; Promise&lt;T&gt; &#x3D;&gt; (T &#x3D;&gt; Promise&lt;T&gt;) &#x3D;&gt; Promise&lt;T&gt;
Promise.prototype.then</code></pre>

<p>The type of <code>resolve</code> and <code>then</code> in continuation is reasonable, but where does the implementation come from? In fact, the <code>resolve</code> and <code>then</code> in promise have such properties:</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">promise.then(Promise.resolve) ~~ promise
Promise.resolve(x).then(next) ~~ next(x)</code></pre>

<p>Try to verify these properties in continuation. We can just replace the parameters in function with its arguments, and simplify patterns like <code>x =&gt; f(x)</code> to <code>f</code> (forget your knowledge in programming and recall the mathematics, you are calculating an equation now).</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">then(continuation, resolve)
  &#x3D; fn &#x3D;&gt; continuation(x &#x3D;&gt; resolve(x)(fn))
  &#x3D; fn &#x3D;&gt; continuation(x &#x3D;&gt; (y &#x3D;&gt; y(x))(fn))
  &#x3D; fn &#x3D;&gt; continuation(x &#x3D;&gt; fn(x))
  &#x3D; fn &#x3D;&gt; continuation(fn)
  &#x3D; continuation

then(resolve(a), next)
  &#x3D; fn &#x3D;&gt; resolve(a)(x &#x3D;&gt; next(x)(fn))
  &#x3D; fn &#x3D;&gt; (y &#x3D;&gt; y(a))(x &#x3D;&gt; next(x)(fn))
  &#x3D; fn &#x3D;&gt; (x &#x3D;&gt; next(x)(fn))(a)
  &#x3D; fn &#x3D;&gt; next(a)(fn)
  &#x3D; next(a)</code></pre>

<p>That’s it. It matches the properties perfectly. Continuation has similar properties to promise, and the key difference is that a function won’t execute until it’s passed with arguments. That’s exactly what we want. Let’s replace the <code>Promise</code> with the <code>Continuation</code> to finish the <code>useState</code> hook.</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">class SuspenseContinuationError&lt;T&gt; extends Error &#123;
  constructor(public continuation: Continuation&lt;T&gt;) &#123;
    super(&#39;suspense error&#39;);
  &#125;
&#125;

const Continuation &#x3D; &#123;
  resolve: x &#x3D;&gt; fn &#x3D;&gt; fn(x),
  then: (continuation, next) &#x3D;&gt; fn &#x3D;&gt; continuation(x &#x3D;&gt; next(x)(fn)),
&#125;

function useState(value?: T) &#123;
  if (!cachedValues[position]) &#123;
    throw new SuspenseContinuationError(makeContinuation(value));
  &#125;
  return cachedValues[position++];
&#125;

function makeContinuation&lt;T&gt;(value: T) &#123;
  return fn &#x3D;&gt; fn([value, function next(nextValue) &#123; fn([nextValue, next]) &#125;]);
&#125;

function run(fn) &#123;
  try &#123;
    position &#x3D; 0;
    return Continuation.resolve(fn);
  &#125; catch (e) &#123;
    const temp &#x3D; position;
    return Continuation.then(e.continuation, value &#x3D;&gt; &#123;
      cachedValues[temp] &#x3D; value;
      position &#x3D; temp + 1;
      return run(fn);
    &#125;);
  &#125;
&#125;

run(() &#x3D;&gt; &#123;
  const [state, setState] &#x3D; useState(0);
  console.info(state);

  if (state &#x3D;&#x3D;&#x3D; 0) &#123;
    setState(1);
  &#125;
&#125;)(() &#x3D;&gt; &#123;&#125;); &#x2F;&#x2F; call with an empty function since it&#39;s a continuation</code></pre>

<p>How can we understand the similarity between promise and continuation? They both map a type to another related type and keep some properties. In fact, it’s like the concept widely used in functional programming named “Monad”. It’s an abstract concept so I can’t describe it vividly, but it obeys the properties mentioned above.</p>
<blockquote>
<p>Maybe you want to read <a href="https://github.com/hmemcpy/milewski-ctfp-pdf">《Category Theory for Programmers》</a></p>
</blockquote>
<h2 id="Conclusion"><a href="#Conclusion" class="headerlink" title="Conclusion"></a>Conclusion</h2><p>Here I introduced React’s new feature, suspense in data fetching and hooks, what are the problems React meets and how does it resolve problems in a functional way. When it comes to functional programming, the first thing that comes out may be the pure function, immutability, high order function, etc. It’s correct but not only that. It not only refers to language features or how we write the code, it’s more like how we think, how can we get an abstract solution to resolve more problems. Thank you.</p>
]]>
    </content>


    <summary type="html">&lt;h2 id=&quot;React-18-Suspense&quot;&gt;&lt;a href=&quot;#React-18-Suspense&quot; class=&quot;headerlink&quot; title=&quot;React 18 Suspense&quot;&gt;&lt;/a&gt;React 18 Suspense&lt;/h2&gt;&lt;p&gt;I believe </summary>


    <category term="FP" scheme="https://blog.means88.com/tags/FP/"/>
    
    <category term="React" scheme="https://blog.means88.com/tags/React/"/>
    
    
  </entry>
  
  <entry>
    <title>React 运行环境的隔离</title>
    <link href="https://blog.means88.com/react-isolation/"/>
    <id>https://blog.means88.com/react-isolation/</id>
    <published>2020-10-11T22:30:02.000Z</published>
    <updated>2026-06-17T03:22:48.948Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//react-isolation/cover.jpeg" /> <p>在实现项目的时候遇到这么一种场景：用户可以在页面引入第三方的组件渲染页面。</p>
<p><img src="todolist.png" alt="示例"></p>
<p>如图中的蓝框部分是用户引入的第三方组件，而下面的控制器是自己实现的组件。里面的列表项组件拥有固定的 props，需要实现正常的 Todo List 的效果。这里有两个最大的难题，一个是动态引入第三方组件库，这里暂且不提。另一个是将蓝框部分与应用的其余部分运行环境隔离。因为第三方组件的安全性是不能保证的，如果直接在应用环境中运行，会影响用户的安全。另一个原因是第三方组件样式的实现方式是不确定的，可能会和主应用的样式相互干扰产生问题。如果仅仅是样式问题，可以使用 Shadow DOM 解决，但是这里就需要使用 iframe 了。</p>
<pre class="line-numbers language-tsx" data-language="tsx" data-start="1" data-line="4,5,6" data-line-offset="0"><code class="language-tsx">function TodoList() &#123;
  const [text, setText] &#x3D; useState(&#39;&#39;);

  const handleSubmit &#x3D; () &#x3D;&gt; &#123;
    &#x2F;&#x2F; TODO
  &#125;;

  return (
    &lt;div className&#x3D;&quot;TodoList&quot;&gt;
      &lt;h1&gt;
        Todo List &lt;span&gt;A simple React Todo List App&lt;&#x2F;span&gt;
      &lt;&#x2F;h1&gt;
      &lt;iframe
        src&#x3D;&quot;&#x2F;iframe&quot;
        sandbox&#x3D;&quot;allow-forms allow-modals allow-popups allow-presentation allow-scripts&quot;
      &#x2F;&gt;
      &lt;form className&#x3D;&quot;NewTodoForm&quot; onSubmit&#x3D;&#123;handleSubmit&#125;&gt;
        &lt;label htmlFor&#x3D;&quot;task&quot;&gt;New todo&lt;&#x2F;label&gt;
        &lt;input
          value&#x3D;&#123;text&#125;
          onChange&#x3D;&#123;e &#x3D;&gt; setText(e.target.value)&#125;
          id&#x3D;&quot;task&quot;
          type&#x3D;&quot;text&quot;
          name&#x3D;&quot;task&quot;
          placeholder&#x3D;&quot;New Todo&quot;
        &#x2F;&gt;
        &lt;button&gt;Add Todo&lt;&#x2F;button&gt;
      &lt;&#x2F;form&gt;
    &lt;&#x2F;div&gt;
  );
&#125;</code></pre>

<p>这里一定要限制 iframe 的 sandbox 属性，尤其是不能有 <code>allow-same-origin</code>, <code>allow-top-navigation</code> 这样的属性，会隐藏严重的安全问题。然后再实现剩下的部分：</p>
<pre class="line-numbers language-tsx" data-language="tsx" data-start="1" data-line="4" data-line-offset="0"><code class="language-tsx">&#x2F;&#x2F; iframe 部分
function IFrame() &#123;
  const Component &#x3D; useThirdPartyComponent();
  const props &#x3D; useThirdPartyProps();

  return &lt;Component &#123;...props&#125; &#x2F;&gt;;
&#125;

&#x2F;&#x2F; 入口文件
function App() &#123;
  return (
    &lt;React.Suspense fallback&#x3D;&#123;loading&#125;&gt;
      &lt;Switch&gt;
        &lt;Route
          exact&#x3D;&#123;true&#125;
          path&#x3D;&quot;&#x2F;&quot;
          component&#x3D;&#123;React.lazy(() &#x3D;&gt; import(&#39;.&#x2F;TodoList&#39;))&#125;
        &#x2F;&gt;
        &lt;Route
          exact&#x3D;&#123;true&#125;
          path&#x3D;&quot;&#x2F;iframe&quot;
          component&#x3D;&#123;React.lazy(() &#x3D;&gt; import(&#39;.&#x2F;IFrame&#39;))&#125;
        &#x2F;&gt;
      &lt;&#x2F;Switch&gt;
    &lt;&#x2F;React.Suspense&gt;
  );
&#125;
</code></pre>

<p>这里使用 Suspense 简单地进行了代码的分割，另外使用 <code>useThirdPartyComponent</code> 代表抽象的获取第三方组件的过程，这里先不展开讨论它的细节。接下来需要实现的是 <code>TodoList</code> 中 <code>handleSubmit</code> 函数（添加一条 task）和 <code>IFrame</code> 的 <code>useThirdPartyProps</code>（获取 todolist 的属性）。</p>
<p>然后是经典的写 Redux 代码环节（好久没写过原生的 Redux 了，正经人是不会写的）。假设这是一个常规版的 todolist，那它的代码是很好写的（去网上抄一份就完了）。</p>
<pre class="line-numbers language-tsx" data-language="tsx"><code class="language-tsx">&#x2F;&#x2F; actions
const addTodo &#x3D; text &#x3D;&gt; (&#123;
    type: &#39;ADD_TODO&#39;,
    id: Date.now(),
    text,
&#125;);

&#x2F;&#x2F; reducer
const todosReducer &#x3D; (state &#x3D; [], action) &#x3D;&gt; &#123;
  switch (action.type) &#123;
    case &#39;ADD_TODO&#39;:
      return [
        ...state,
        &#123;
            id: action.id,
            text: action.text,
        &#125;,
      ];
    default:
      return state;
  &#125;;
&#125;;</code></pre>

<p>然后组件里面的这两个函数就很好写了</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function TodoList() &#123;
  &#x2F;&#x2F; ...
  const dispatch &#x3D; useDispatch();

  const handleSubmit &#x3D; () &#x3D;&gt; &#123;
    dispatch(addTodo(text));
    setText(&#39;&#39;);
  &#125;;
  &#x2F;&#x2F; ...
&#125;

function IFrame() &#123;
  const Component &#x3D; useThirdPartyComponent();
  const props &#x3D; useSelector(state &#x3D;&gt; state);

  return &lt;Component tasks&#x3D;&#123;props&#125; &#x2F;&gt;;
&#125;
</code></pre>

<p>如果在 iframe 之间也可以像这样写代码就更好了，无需改动代码，写的时候不需要有其它的成本，而且还可以兼容更上层的 Redux 封装。经过一番搜索找到了这么一个库 <a href="https://github.com/aohua/redux-state-sync">redux-state-sync</a>。它实现了 Redux 的一个 middleware，可以同步多个 Redux 之间的状态，于是果断 <code>yarn add redux-state-sync</code>。运行之后果不其然地失败了 ╮(╯▽╰)╭，不管怎么添加，里面的列表一点反应都没有。只能看看是怎么实现的了。</p>
<p>它的实现原理其实很简单，初始化时从其他实例获取 state 值，当有一个实例获取到 action 时将 action 转发给其它实例，由于 Redux 的性质，最终得到的 state 总是一致的。注意需要将 middleware 放在最后，防止使用 thunk 等其它 middleware 的时候转发异步的 action 导致问题。这个 middleware 使用 BroadcastChannel 发送消息，而 BroadcastChannel 只能支持发送消息到同源的页面，而我们的 iframe 关闭了 <code>allow-same-origin</code>，所以没有办法收到消息。</p>
<p>这样的话就只能用无敌的 <code>window.postMessage</code> 想想办法了。主页面和 iframe 直接使用 <code>postMessage</code> 发送消息是不需要同源的，可以使用 <code>postMessage</code> 模拟一个 BroadcastChannel。因为主页面和 iframe 不是完全对称的，一个主页面里可能有多个 iframe，iframe 之间也需要发送消息，为了简化代码的复杂度，统一使用主页面发送消息给自己和所有的 iframe 页面。需要实现 channel 的 <code>postMessage</code> 和 <code>onmessage</code>。思路比较简单就直接贴出</p>
<details>
<summary>太长了，点击展开实现代码</summary>

<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">&#x2F;&#x2F; 这里用到的事件类型有两种
&#x2F;&#x2F; frame-broadcast-request 是原始事件，用于主页面的转发，只有主页面需要处理
&#x2F;&#x2F; frame-broadcast 是转发生成的事件，收到事件的页面需要处理
class FrameBroadcastChannel &#123;
  isTop: boolean;

  name: string;

  handlers: &#123;
    [type: string]: MessageHandler[];
  &#125; &#x3D; &#123;
    message: [],
    messageerror: [],
  &#125;;

  onMessage: null | MessageHandler &#x3D; null;

  mainHandler: &#123;
    [type: string]: MessageHandler;
  &#125;;

  constructor(name: string) &#123;
    this.isTop &#x3D; typeof window &#x3D;&#x3D;&#x3D; &#39;undefined&#39; || window &#x3D;&#x3D;&#x3D; window.parent;
    this.name &#x3D; name;
    this.onMessage &#x3D; null;
    &#x2F;&#x2F; 过滤出需要的事件，转到 handlers 里面的回调函数执行
    this.mainHandler &#x3D; &#123;
      message: e &#x3D;&gt; &#123;
        if (e.data.type !&#x3D;&#x3D; &#39;frame-broadcast&#39; || e.data.channel !&#x3D;&#x3D; this.name) &#123;
          return;
        &#125;
        this.handlers.message.forEach(handler &#x3D;&gt; handler(e.data.message));
      &#125;,
      messageerror: e &#x3D;&gt; &#123;
        if (e.data.type !&#x3D;&#x3D; &#39;frame-broadcast&#39; || e.data.channel !&#x3D;&#x3D; this.name) &#123;
          return;
        &#125;
        this.handlers.messageerror.forEach(handler &#x3D;&gt; handler(e.data.message));
      &#125;,
    &#125;;
    for (const type of [&#39;message&#39;, &#39;messageerror&#39;] as const) &#123;
      window.addEventListener(type, this.mainHandler[type]);
    &#125;

    &#x2F;&#x2F; 如果是主页面就转发消息到所有 iframe 页面
    this.broadcastHandler &#x3D; this.broadcastHandler.bind(this);
    if (this.isTop) &#123;
      window.addEventListener(&#39;message&#39;, this.broadcastHandler);
    &#125;
  &#125;

  broadcastHandler(e: MessageEvent) &#123;
    if (
      e.data.type !&#x3D;&#x3D; &#39;frame-broadcast-request&#39; ||
      e.data.channel !&#x3D;&#x3D; this.name
    ) &#123;
      return;
    &#125;
    const data &#x3D; &#123;
      type: &#39;frame-broadcast&#39;,
      channel: this.name,
      message: e.data.message,
    &#125;;
    &#x2F;&#x2F; 遍历发送事件，这里只考虑了两层，如果有需要可以递归
    window.postMessage(data, &#39;*&#39;);
    for (const frame of Array.from(window.frames)) &#123;
      frame.postMessage(data, &#39;*&#39;);
    &#125;
  &#125;

  postMessage(message: any) &#123;
    &#x2F;&#x2F; 使用主页面发送事件
    &#x2F;&#x2F; 这里只考虑了两层，如果有需要可以使用
    &#x2F;&#x2F; let current &#x3D; window;
    &#x2F;&#x2F; while (current !&#x3D;&#x3D; current.parent) &#123;
    &#x2F;&#x2F;   current &#x3D; current.parent
    &#x2F;&#x2F; &#125;
    &#x2F;&#x2F; 获取最顶层
    window.parent.postMessage(
      &#123;
        type: &#39;frame-broadcast-request&#39;,
        channel: this.name,
        message,
      &#125;,
      &#39;*&#39;,
    );
  &#125;

  close() &#123;
    this.handlers &#x3D; &#123;&#125;;
    this.onMessage &#x3D; null;

    for (const type of [&#39;message&#39;, &#39;messageerror&#39;] as const) &#123;
      window.removeEventListener(type, this.mainHandler[type]);
    &#125;
    if (this.isTop) &#123;
      window.removeEventListener(&#39;message&#39;, this.broadcastHandler);
    &#125;
  &#125;

  set onmessage(v: MessageHandler) &#123;
    this.removeEventListener(&#39;message&#39;, v);
    if (typeof v &#x3D;&#x3D;&#x3D; &#39;function&#39;) &#123;
      this.addEventListener(&#39;message&#39;, v);
      this.onMessage &#x3D; v;
    &#125; else &#123;
      this.onMessage &#x3D; null;
    &#125;
  &#125;

  addEventListener(type: string, handler: MessageHandler) &#123;
    this.handlers[type].push(handler);
  &#125;

  removeEventListener(type: string, handler: MessageHandler) &#123;
    this.handlers[type] &#x3D; this.handlers[type].filter(x &#x3D;&gt; x !&#x3D;&#x3D; handler);
  &#125;
&#125;
</code></pre>
</details>

<p>最后使用 <code>FrameBroadcastChannel</code> 代替原本的 <code>BroadcastChannel</code> 就可以了。</p>
]]>
    </content>


    <summary type="html">&lt;p&gt;在实现项目的时候遇到这么一种场景：用户可以在页面引入第三方的组件渲染页面。&lt;/p&gt;
&lt;p&gt;&lt;img src=&quot;todolist.png&quot; alt=&quot;示例&quot;&gt;&lt;/p&gt;
&lt;p&gt;如图中的蓝框部分是用户引入的第三方组件，而下面的控制器是自己实现的组件。里面的列表项组件拥有固定的 p</summary>


    <category term="React" scheme="https://blog.means88.com/tags/React/"/>
    
    <category term="Redux" scheme="https://blog.means88.com/tags/Redux/"/>
    
    
  </entry>
  
  <entry>
    <title>从非递归函数生成递归函数</title>
    <link href="https://blog.means88.com/y-combinator/"/>
    <id>https://blog.means88.com/y-combinator/</id>
    <published>2020-06-12T23:12:57.000Z</published>
    <updated>2026-06-17T03:22:48.967Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//y-combinator/cover.jpeg" /> <p>递归在现代的语言中是一个很常见的特性，它可以把问题分解成规模更小的相似问题逐步解决。尤其是在函数式编程语言中，没有循环语句，所有的迭代操作都会由递归来完成。但是如果有一天被大卡车撞了，穿越到了递归函数不存在的世界，应该要怎么样实现相同的效果呢？</p>
<h2 id="Y-Combinator"><a href="#Y-Combinator" class="headerlink" title="Y Combinator"></a>Y Combinator</h2><pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">function factorial(n) &#123;
  if (n &#x3D;&#x3D;&#x3D; 0 || n &#x3D;&#x3D;&#x3D; 1) &#123;
    return 1;
  &#125;
  return n * factorial(n - 1);
&#125;
</code></pre>

<p>年轻人的第一个递归，阶乘函数。下面把它改写成箭头函数。</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="5" data-line-offset="0"><code class="language-typescript">n &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0 || n &#x3D;&#x3D;&#x3D; 1) &#123;
    return 1;
  &#125;
  return n * &#x2F;* ??? *&#x2F;;
&#125;
</code></pre>

<p>很快就遇到了问题，因为我们没有给这个箭头函数绑定变量，所以在递归调用的地方不知道应该写什么了。这就是接下来的任务：把不能递归的函数变得可以递归。既然在这个地方找不到 <code>factorial</code> 函数了，那就创造一个。在箭头函数中，唯一可能得到这个函数的地方就是参数了，因此先加上一个参数，每次调用的时候把 <code>factorial</code> 传递进来就可以了</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="7" data-line-offset="0"><code class="language-typescript">const recursive &#x3D; fn &#x3D;&gt; (...args) &#x3D;&gt; fn(fn, ...args);

recursive((fn, n) &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0 || n &#x3D;&#x3D;&#x3D; 1) &#123;
    return 1;
  &#125;
  return n * fn(fn, n - 1);
&#125;);
</code></pre>

<p>因为函数的参数变为了两个，第 7 行变为了 <code>fn(fn, n - 1)</code>。这可太丑了，在写函数的时候每次都要把自己作为第一个参数写进来，正经的人是不会写出这样的代码的。理想情况中，这里仍应保持 <code>fn(n - 1)</code> 的形式。所以 <code>recursive</code> 函数还应该继续改进。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt; (...args) &#x3D;&gt; fn(fn, ...args);
&#x2F;&#x2F;                                      ~~
</code></pre>

<p>这个位置的参数显然不应该是 <code>fn</code> 了，它应该是一个 <code>(...args) =&gt; ReturnValue</code> 类型的函数 <code>X</code>。但是目前的作用域中只有 <code>fn</code>, <code>args</code>，显然它们以及它们的直接组合都不是 <code>X</code> 合适的候选项。因此设 <code>X</code> 为 <code>x(?)</code> 的形式。这里需要继续引入新的变量，考虑和前面引入递归函数时相同，把 <code>x</code> 放在函数的参数里面。为了不改变返回值的类型，写为 IIFE 的形式。</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="2" data-line-offset="0"><code class="language-typescript">const recursive &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; (...args) &#x3D;&gt; fn(x(?), ...args)
&#x2F;&#x2F;                        ~
  )(x_);
&#x2F;&#x2F;  ~~
</code></pre>

<p>这样又引入了两个未知的变量，调用 <code>x</code> 的参数 <code>?</code>，以及传递给 <code>x</code> 的值 <code>x_</code>。首先来找 <code>x_</code> 的取值。根据上面的叙述，<code>x</code> 应该是一个返回 <code>(...args) =&gt; fn(x(?), ...args)</code> 的函数，所以需要找到一个 <code>?? =&gt; (...args) =&gt; fn(x(?), ...args)</code> 形式的函数。而神奇的是，第 2 行不就恰好是这样一个函数吗？令 <code>x_ = x =&gt; (...args) =&gt; fn(x(?), ...args</code> 得到</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; (...args) &#x3D;&gt; fn(x(?), ...args))
  (x &#x3D;&gt; (...args) &#x3D;&gt; fn(x(?), ...args));
</code></pre>

<p>然后就只剩下 <code>x</code> 的参数 <code>?</code> 了。综合上面的结果可以得到 <code>x</code> 的形式是 <code>x =&gt; (...args) =&gt; fn(x(?), ...args)</code>。而 <code>x(?)</code> 是 <code>(...args) =&gt; fn(x(?), ...args)</code>。那么显然 <code>?</code> 就是 <code>x</code> 本身。所以</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; (...args) &#x3D;&gt; fn(x(x), ...args))
  (x &#x3D;&gt; (...args) &#x3D;&gt; fn(x(x), ...args));
</code></pre>

<p>简化成 $ \lambda $ 表达式的形式就是（通过 $ \eta $ 转换去掉 <code>args</code>）</p>
<p>$$ \lambda f.(\lambda x.f(x ~ x))(\lambda x.f(x ~ x)) $$</p>
<p>这就是 Y Combinator。为了看起来更加「函数式」，把 <code>Y</code> 函数进行柯里化，并且限定 <code>args</code> 只接受一个参数。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const Y &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; arg &#x3D;&gt; fn(x(x))(arg))
  (x &#x3D;&gt; arg &#x3D;&gt; fn(x(x))(arg))
</code></pre>

<p>回到最初的函数，使用 Y Combinator 构造递归函数</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const factorial &#x3D; Y(fn &#x3D;&gt; n &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0 || n &#x3D;&#x3D;&#x3D; 1) &#123;
    return 1;
  &#125;
  return n * fn(n - 1);
&#125;);
</code></pre>

<pre class="line-numbers language-console" data-language="console"><code class="language-console">$ console.log(factorial(5))
&gt; 120
</code></pre>

<p>上面的 $ \lambda $ 表达式通过 $ \eta $ 转换去掉了 <code>args</code>，如果在 JavaScript 代码中也执行相同的操作会？</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="5" data-line-offset="0"><code class="language-typescript">const Y &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; fn(x(x)))
  (x &#x3D;&gt; fn(x(x)))

const factorial &#x3D; Y(fn &#x3D;&gt; n &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0 || n &#x3D;&#x3D;&#x3D; 1) &#123;
    return 1;
  &#125;
  return n * fn(n - 1);
&#125;);
</code></pre>

<pre class="line-numbers language-console" data-language="console"><code class="language-console">&gt; Uncaught RangeError: Maximum call stack size exceeded</code></pre>

<p>在调用 <code>Y</code> 生成递归函数的时候直接爆栈了。模拟运行一下调用 <code>Y</code> 的过程。根据 JavaScript 的运行逻辑，传入参数 <code>fn</code> 以后，首先执行 IIFE，将 <code>x =&gt; fn(x(x))</code> 传入 <code>x =&gt; fn(x(x))</code>，计算 <code>fn</code> 中的参数 <code>x(x)</code>。代换以后得到 <code>(x =&gt; fn(x(x)))(x =&gt; fn(x(x)))</code>。很好，又整回去了 ╮(╯▽╰)╭。这个过程会无限地重复下去，最后爆栈。</p>
<h2 id="Thunk"><a href="#Thunk" class="headerlink" title="Thunk"></a>Thunk</h2><p>再来看一个递归函数的例子，求一个数是否为偶数。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const isEven &#x3D; Y(fn &#x3D;&gt; n &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0) &#123;
    return true;
  &#125;
  return !isEven(n - 1);
&#125;);
</code></pre>

<p>然后来尝试一下</p>
<pre class="line-numbers language-console" data-language="console"><code class="language-console">$ isEven(114514)
&gt; RangeError: Maximum call stack size exceeded
</code></pre>

<p>又爆栈了，因为栈深度是 $ O(n) $ 的，数字比较大的时候就会直接爆栈。这里就想到了尾递归优化，当递归调用的语句是函数中的最后一个语句时，编译器将栈深度优化为 $ O(1) $。在这个例子中，计算完 <code>isEven(n - 1)</code> 后还需要对结果取反，所以实际上递归调用是倒数第二条语句，因此改进代码。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const isEven &#x3D; Y(fn &#x3D;&gt; n &#x3D;&gt; &#123;
  if (n &#x3D;&#x3D;&#x3D; 0) &#123;
    return true;
  &#125;
  if (n &#x3D;&#x3D;&#x3D; 1) &#123;
    return false;
  &#125;
  return isEven(n - 2);
&#125;);
</code></pre>

<p>但是等一下，一个连递归函数都没有的异世界怎么会有尾递归优化的编译器呢？（什么？现实世界的 JavaScript 引擎也不支持？那没事了）很快就能想到，我们可以像前面给 Y Combinator 添加 <code>args</code> 参数一样，推迟函数调用的时机，这样就不会爆栈了。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const Thunk &#x3D; fn &#x3D;&gt; (&#123; get: () &#x3D;&gt; fn() &#125;);

const trampoline &#x3D; fn &#x3D;&gt; &#123;
  let value &#x3D; fn();

  while (typeof value.get &#x3D;&#x3D;&#x3D; &#39;function&#39;) &#123;
    value &#x3D; value.get();
  &#125;

  return value;
&#125;;

const isEven &#x3D; trampoline(
  Y(fn &#x3D;&gt; n &#x3D;&gt; &#123;
    if (n &#x3D;&#x3D;&#x3D; 0) &#123;
      return true;
    &#125;
    if (n &#x3D;&#x3D;&#x3D; 1) &#123;
      return false;
    &#125;
    return Thunk(() &#x3D;&gt; fn(n - 2));
  &#125;)
);
</code></pre>

<pre class="line-numbers language-console" data-language="console"><code class="language-console">$ isEven(114514)
&gt; true</code></pre>

<p>这里又有了一个同样的问题，<code>isEven</code> 的函数里面写了 <code>Thunk</code>，这个优化对于函数本身是不透明的，正经人是不会写这种代码的。所以要尝试吧 <code>Thunk</code> 从函数里面取出来。这就意味着，当我们调用 <code>fn(n - 2)</code> 的时候，返回的值不是 <code>isEven(n - 2)</code>，而是 <code>Thunk^m(isEven(n - 2))</code>。再回到 <code>Y</code> 函数</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const Y &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; arg &#x3D;&gt; fn(x(x))(arg))
  (x &#x3D;&gt; arg &#x3D;&gt; fn(x(x))(arg))
</code></pre>

<p>也就是说我们需要修改 <code>x(x)</code>。我们知道 <code>x(x)</code> 是一个函数，所以可以转换成 <code>brg =&gt; x(x)(brg)</code>。把返回值变为 Thunk，得到 <code>brg =&gt; Thunk(() =&gt; x(x)(brg))</code></p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt;
  (x &#x3D;&gt; arg &#x3D;&gt; fn(brg &#x3D;&gt; Thunk(() &#x3D;&gt; x(x)(brg)))(arg))
  (x &#x3D;&gt; arg &#x3D;&gt; fn(brg &#x3D;&gt; Thunk(() &#x3D;&gt; x(x)(brg)))(arg))
</code></pre>

<p>因为函数和参数相同，简化得到</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt;
  (m &#x3D;&gt; m(m))
  (x &#x3D;&gt; arg &#x3D;&gt; fn(brg &#x3D;&gt; Thunk(() &#x3D;&gt; x(x)(brg)))(arg))
</code></pre>

<p>最后再将计算的结果从 Thunk 中取出即可</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const recursive &#x3D; fn &#x3D;&gt; fnArg &#x3D;&gt; &#123;
  let value &#x3D; (m &#x3D;&gt; m(m))
    (x &#x3D;&gt; arg &#x3D;&gt; fn(brg &#x3D;&gt; Thunk(() &#x3D;&gt; x(x)(brg)))(arg))
    (fnArg);
  while (typeof value.get &#x3D;&#x3D;&#x3D; &#39;function&#39;) &#123;
    value &#x3D; value.get();
  &#125;
  return value;
&#125;
</code></pre>

<p>再来试一下</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">const isEven &#x3D; recursive(
  fn &#x3D;&gt; n &#x3D;&gt; &#123;
    if (n &#x3D;&#x3D;&#x3D; 0) &#123;
      return true;
    &#125;
    if (n &#x3D;&#x3D;&#x3D; 1) &#123;
      return false;
    &#125;
    return fn(n - 2);
  &#125;
);
</code></pre>

<pre class="line-numbers language-console" data-language="console"><code class="language-console">$ isEven(114514)
&gt; true</code></pre>

<p>很好，现在就可以在递归函数里面使用尾递归优化了。可是既然有循环语句了，为什么还要用递归呢？(￣ε(#￣)☆╰╮o(￣皿￣///)</p>
<h2 id="参考文献"><a href="#参考文献" class="headerlink" title="参考文献"></a>参考文献</h2><ol>
<li>Paulson, L. C., Foundations of functional programming, University of Cambridge, 1995.</li>
<li>R. Braithwaite, “Why Y? Deriving the Y Combinator in JavaScript<br>“, Raganwald, 2018.</li>
</ol>
]]>
    </content>


    <summary type="html">&lt;p&gt;递归在现代的语言中是一个很常见的特性，它可以把问题分解成规模更小的相似问题逐步解决。尤其是在函数式编程语言中，没有循环语句，所有的迭代操作都会由递归来完成。但是如果有一天被大卡车撞了，穿越到了递归函数不存在的世界，应该要怎么样实现相同的效果呢？&lt;/p&gt;
&lt;h2 id=&quot;Y-</summary>


    <category term="FP" scheme="https://blog.means88.com/tags/FP/"/>
    
    
  </entry>
  
  <entry>
    <title>Algebraic Effects</title>
    <link href="https://blog.means88.com/algebraic-effects/"/>
    <id>https://blog.means88.com/algebraic-effects/</id>
    <published>2019-11-16T16:23:19.000Z</published>
    <updated>2026-06-17T03:22:48.902Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//algebraic-effects/cover.jpeg" /> <p>看到 Dan Abramov 的一篇博客 <a href="https://overreacted.io/algebraic-effects-for-the-rest-of-us/">Algebraic Effects for the Rest of Us</a> 提到了一个叫 Algebraic Effects 的概念。并举出了一个虚构的语法作为例子。它和之前提到的 Suspense 也有很多相似的地方。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function delay&lt;T&gt;(value: T, time &#x3D; 1000) &#123;
  return new Promise&lt;T&gt;(resolve &#x3D;&gt; &#123;
    setTimeout(() &#x3D;&gt; resolve(value), time);
  &#125;);
&#125;

function process&lt;T&gt;(x: Promise&lt;T&gt; | T) &#123;
  console.log(x); &#x2F;&#x2F; 这里可以正确输出 &#39;value&#39;
&#125;

process(delay(&#39;value&#39;));</code></pre>

<p>使用普通的 JavaScript 特性，没有办法在不将 process 变为异步的同时正确输出 <code>&#39;value&#39;</code>。假设有这样一种语法</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="13,23" data-line-offset="0"><code class="language-typescript">function delay&lt;T&gt;(value: T, time &#x3D; 1000) &#123;
  return new Promise&lt;T&gt;(resolve &#x3D;&gt; &#123;
    setTimeout(() &#x3D;&gt; resolve(value), time);
  &#125;);
&#125;

function isPromise&lt;T&gt;(x: Promise&lt;T&gt; | T): x is Promise&lt;T&gt; &#123;
  return typeof x.then &#x3D;&#x3D;&#x3D; &#39;function&#39;;
&#125;

function process&lt;T&gt;(x: Promise&lt;T&gt; | T) &#123;
  if (isPromise(x)) &#123;
    x &#x3D; perform x;
  &#125;
  console.log(x); &#x2F;&#x2F; 这里可以正确输出 &#39;value&#39;
&#125;

try &#123;
  process(delay(&#39;value&#39;));
&#125; handle (effect) &#123;
  if (isPromise(effect)) &#123;
    effect.then(value &#x3D;&gt; &#123;
      resume with value;
    &#125;);
  &#125;
&#125;
</code></pre>

<p>这里有三个和普通 JavaScript 不同的地方，<code>perform</code>, <code>try-handle</code> 和 <code>resume</code>。它的作用和 <code>try-catch</code> 类似，在执行 <code>perform</code> 时会中断当前操作，跳转到最近一层的 <code>try-handle</code> 语句，并把 <code>perform</code> 后面的值传递给 <code>handle</code> 代码块。在运行到 <code>resume</code> 语句时，代码的运行会回到 <code>perform</code> 的地方，并返回 <code>resume</code> 的值。</p>
<p>具体到上面这个例子，代码会在运行到</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="3" data-line-offset="0"><code class="language-typescript">function process&lt;T&gt;(x: Promise&lt;T&gt; | T) &#123;
  if (isPromise(x)) &#123;
    x &#x3D; perform x;
  &#125;
  console.log(x); &#x2F;&#x2F; 这里可以正确输出 &#39;value&#39;
&#125;</code></pre>

<p>时中断，并且跳转出去寻找最近的一个 <code>try-handle</code> 语句</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="3" data-line-offset="0"><code class="language-typescript">try &#123;
  process(delay(&#39;value&#39;));
&#125; handle (effect) &#123;
  if (isPromise(effect)) &#123;
    effect.then(value &#x3D;&gt; &#123;
      resume with value;
    &#125;);
  &#125;
&#125;</code></pre>

<p>此时 <code>effect</code> 的值就是 <code>perform</code> 传递过来的 <code>x</code>，也就是 <code>delay(&#39;value&#39;)</code>。</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="6" data-line-offset="0"><code class="language-typescript">try &#123;
  process(delay(&#39;value&#39;));
&#125; handle (effect) &#123;
  if (isPromise(effect)) &#123;
    effect.then(value &#x3D;&gt; &#123;
      resume with value;
    &#125;);
  &#125;
&#125;</code></pre>

<p>然后在这个 Promise resolve 之后，运行 <code>resume</code>，并把获取到的值 <code>&quot;value&quot;</code> 返回给原来执行的地方。</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="3" data-line-offset="0"><code class="language-typescript">function process&lt;T&gt;(x: Promise&lt;T&gt; | T) &#123;
  if (isPromise(x)) &#123;
    x &#x3D; perform x;
  &#125;
  console.log(x); &#x2F;&#x2F; 这里可以正确输出 &#39;value&#39;
&#125;</code></pre>

<p>此时 <code>x</code> 被赋值为 <code>&quot;value&quot;</code>，最终正确输出。</p>
<p>「像写同步代码一样写异步代码」，这听起来很像 <code>async-await</code> 语法的描述，但是 <code>async-await</code> 有一个很不方便的场景：当一个函数从普通函数修改为 async 函数时，所有调用它的函数也需要修改为 async 函数。这条修改的链路可能很长，会给重构工作带来巨大的麻烦。而使用 Algebraic Effect，则只需要修改一个函数即可。</p>
<p>Algebraic Effect 的形式看起来和 <a href="/react-hook-suspense">上一篇文章</a> 的 Suspense 实现有很多相似之处。但是 ALgebraic Effect 的写法显然简洁了很多。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">&#x2F;&#x2F; 需要自己提取 Monad 实现状态的流转
export const schedule &#x3D; (m: Monad) &#x3D;&gt; (thunk: () &#x3D;&gt; T) &#x3D;&gt; &#123;
  const ctx: Context &#x3D; &#123;
    effect: null as Monad_&lt;T&gt;,
    trace: [] as T[],
    pos: 0,
  &#125;;
  return step();

  &#x2F;&#x2F; 执行流程在 &#96;getValue&#96; 和 &#96;schedule#step&#96; 里面反复横跳
  &#x2F;&#x2F; 执行的逻辑难以阅读
  function step(value?: T): Monad_&lt;T&gt; &#123;
    const savedContext &#x3D; context;
    ctx.pos &#x3D; 0;
    try &#123;
      context &#x3D; ctx; &#x2F;&#x2F; 用到了全局变量，数据变化不清楚
      return m.of(thunk());
    &#125; catch (e) &#123;
      const &#123; pos &#125; &#x3D; ctx;
      return m.chain(ctx.effect, (value: T) &#x3D;&gt; &#123;
        ctx.trace.length &#x3D; pos;
        ctx.trace[pos] &#x3D; value;
        ctx.pos &#x3D; pos + 1;
        return step(value);
      &#125;);
    &#125; finally &#123;
      context &#x3D; savedContext;
    &#125;
  &#125;
&#125;;

schedule(PromiseM)(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&quot;value&quot;));
  const value2 &#x3D; getValue(delay(&quot;value2&quot;));
  console.log(value, value2);
&#125;);
</code></pre>

<p>看到这里大概就能理解，为什么异步加载等功能明明可以让用户自己实现，并且还有 <code>react-query</code> 等库，React 还要自己实现一个 Suspense 了。有了 Suspense 以后，用户完全不需要关心异步操作，以及随之而来的各种状态处理，真的可以做到像写同步代码一样写异步代码。</p>
]]>
    </content>


    <summary type="html">&lt;p&gt;看到 Dan Abramov 的一篇博客 &lt;a href=&quot;https://overreacted.io/algebraic-effects-for-the-rest-of-us/&quot;&gt;Algebraic Effects for the Rest of Us&lt;/a&gt; 提到了一</summary>


    <category term="FP" scheme="https://blog.means88.com/tags/FP/"/>
    
    
  </entry>
  
  <entry>
    <title>React Suspense, React Hooks 与 FP</title>
    <link href="https://blog.means88.com/react-hook-suspense/"/>
    <id>https://blog.means88.com/react-hook-suspense/</id>
    <published>2019-09-19T16:23:19.000Z</published>
    <updated>2026-06-17T03:22:48.944Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//react-hook-suspense/cover.jpeg" /> <p>最近看了 <a href="https://medium.com/free-code-camp/when-to-use-react-suspense-vs-react-hooks-f66ef94cb54f">一篇很有意思的文章</a>，讲述了 Suspense, Hook 与 Monad, Applicative 之间的关系。里面的信息量有点大，拿出来整理一下。</p>
<h2 id="实现-Suspense"><a href="#实现-Suspense" class="headerlink" title="实现 Suspense"></a>实现 Suspense</h2><p>首先考虑实现这样一个函数，同步地从 Promise 中取出里面的值。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function getValue&lt;T&gt;(x: Promise&lt;T&gt;): T &#123;&#125;</code></pre>

<p>我们知道，JavaScript 中是无法用常规方法非阻塞地从 Promise 中取出值的。因此这里增加一个函数 <code>schedule</code> 用来调度 <code>getValue</code> 函数。当 Promise 没有被 resolve 时中断操作让出执行权，并在 resolve 之后重新调用获得结果。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">schedule(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&#39;value&#39;));
  console.log(value); &#x2F;&#x2F; 这里可以正确输出
&#125;);

function delay&lt;T&gt;(x: T): Promise&lt;T&gt;;</code></pre>

<p>这里利用 throw，大概写成了这个形式</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">const ctx &#x3D; &#123;
  promise: null as Promise&lt;T&gt;,
  fullfilled: false,
  value: null as T
&#125;;

&#x2F;**
 * 如果已经计算完毕，直接返回结果
 * 否则抛出异常让 schedule 捕获
 *&#x2F;
export const getValue &#x3D; (x: Promise&lt;T&gt;) &#x3D;&gt; &#123;
  if (ctx.fullfilled) &#123;
    return ctx.value;
  &#125;
  ctx.promise &#x3D; x;
  throw new Error(&#39;not evaluated&#39;);
&#125;;

export const schedule &#x3D; (thunk: () &#x3D;&gt; T) &#x3D;&gt; &#123;
  return step();

  function step(value?: T) &#123;
    try &#123;
      &#x2F;&#x2F; 执行计算，如果已经计算完毕则正常返回
      return thunk();
    &#125; catch (e) &#123;
      &#x2F;&#x2F; 如果没有计算完毕会捕获异常
      &#x2F;&#x2F; 使用 then 安排 resolve 之后重新调用
      return ctx.promise.then((value) &#x3D;&gt; &#123;
        ctx.fullfilled &#x3D; true;
        ctx.value &#x3D; value;
        return step(value);
      &#125;);
    &#125;
  &#125;
&#125;;

schedule(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&quot;value&quot;));
  console.log(value);
&#125;);</code></pre>

<p>使用变量 <code>ctx</code> 保存执行时的状态，调用 <code>getValue</code> 时，如果发现 Promise 没有被 resolve，则抛出异常，让外层的 <code>schedule</code> 捕获。<code>schedule</code> 使用 <code>then</code> 函数让 Promise 被 resolve 的时候再次调用 <code>getValue</code> 函数，此时已经获取到了内部的值，直接返回即可。这个例子还十分粗糙，没有考虑多次调用 <code>getValue</code> 的情况，每次只会返回第一个执行的结果。稍加改进以后可以变成：</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="10,11,12,20,21,28,48,49,50" data-line-offset="0"><code class="language-typescript">const token &#x3D; Symbol(&quot;schedule interrupt&quot;);
let context: Context;
&#x2F;**
 * 如果已经计算完毕，直接返回结果
 * 否则抛出异常让 schedule 捕获
 *&#x2F;
export const getValue &#x3D; (x: Promise&lt;T&gt;) &#x3D;&gt; &#123;
  &#x2F;&#x2F; 如果当前的 promise 已经计算过了，直接返回
  &#x2F;&#x2F; 并移动 pos 的位置计算下一个
  if (context.pos &lt; context.trace.length) &#123;
    return context.trace[context.pos++];
  &#125;
  context.promise &#x3D; x;
  throw token;
&#125;;

export const schedule &#x3D; (thunk: () &#x3D;&gt; T) &#x3D;&gt; &#123;
  const ctx: Context &#x3D; &#123;
    promise: null as Promise&lt;T&gt;,
    trace: [] as T[], &#x2F;&#x2F; trace 用于记录已经计算完毕的值
    pos: 0, &#x2F;&#x2F; pos 表示当前计算的 promise 是第几个
  &#125;;
  return step();

  function step(value?: T): Promise&lt;T&gt; &#123;
    const savedContext &#x3D; context;
    &#x2F;&#x2F; 初始化为 0，每次调用的时候都从第 0 个开始计算
    ctx.pos &#x3D; 0;
    try &#123;
      context &#x3D; ctx;
      &#x2F;&#x2F; 执行计算，如果全部 promise 都已经计算完毕则正常返回
      &#x2F;&#x2F; 加上一层 resolve 使得返回的类型一致
      return Promise.resolve(thunk());
    &#125; catch (e) &#123;
      &#x2F;&#x2F; 不是 schedule interrupt 的话就是真正的错误
      &#x2F;&#x2F; 重新抛出
      if (e !&#x3D;&#x3D; token) &#123;
        throw e;
      &#125;
      &#x2F;&#x2F; 如果没有计算完毕会捕获异常
      &#x2F;&#x2F; 第 i 个 promise 没有计算完毕时
      &#x2F;&#x2F; pos 的值会停在 i
      &#x2F;&#x2F; 使用 then 在计算完毕后将值记录在 trace[pos] 的位置上
      &#x2F;&#x2F; 然后再次尝试调用 thunk
      &#x2F;&#x2F; 直到所有的值都被计算完毕
      const &#123; pos &#125; &#x3D; ctx;
      return ctx.promise.then((value) &#x3D;&gt; &#123;
        ctx.trace.length &#x3D; pos;
        ctx.trace[pos] &#x3D; value;
        ctx.pos &#x3D; pos + 1;
        return step(value);
      &#125;);
    &#125; finally &#123;
      context &#x3D; savedContext;
    &#125;
  &#125;
&#125;;

schedule(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&quot;value&quot;));
  const value2 &#x3D; getValue(delay(&quot;value2&quot;));
  console.log(value, value2);
&#125;);

schedule(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&quot;value3&quot;));
  console.log(value);
&#125;);
</code></pre>

<p>这里增加了 <code>trace</code> 来保存所有计算完毕的值，并且用 <code>pos</code> 表示当前正在计算的是第几个 Promise。并且为了支持多个 <code>schedule</code> 同时调用，将每次运行时的 <code>ctx</code> 保存下来，计算完毕时还原到上一层的 <code>ctx</code>。至此我们已经实现了一个简易的 Suspense。</p>
<h2 id="Applicative-与-Monad"><a href="#Applicative-与-Monad" class="headerlink" title="Applicative 与 Monad"></a>Applicative 与 Monad</h2><p>把 FP 的概念引入 Suspense 之前，先回顾一下 Haskell 中 <code>Applicative</code> 和 <code>Monad</code> 的定义</p>
<pre class="line-numbers language-haskell" data-language="haskell"><code class="language-haskell">class Functor f &#x3D;&gt; Applicative f where
  pure :: a -&gt; f a
  (&lt;*&gt;) :: f (a -&gt; b) -&gt; f a -&gt; f b

class Applicative m &#x3D;&gt; Monad m where
  return :: a -&gt; m a
  (&gt;&gt;&#x3D;) :: m a -&gt; (a -&gt; m b) -&gt; m b
</code></pre>

<p>它们应当是一个 Functor（范畴论意义中为 Haskell Type 范畴下的 endofunctor）。此外，Applicative 需要定义 <code>pure</code> 函数实现源类型到 Applicative 类型的转化。以及 <code>&lt;*&gt;</code> 函数用于 Applicative 类型函数的应用。Monad 在 Applicative 的基础上，还需要实现 <code>&gt;&gt;=</code> 函数用于连接函数的调用。</p>
<h2 id="JavaScript-中的-Monad"><a href="#JavaScript-中的-Monad" class="headerlink" title="JavaScript 中的 Monad"></a>JavaScript 中的 Monad</h2><p>通过观察发现，我们可以从上面的代码中提取出一个 Monad 类型：</p>
<pre class="line-numbers language-haskell" data-language="haskell"><code class="language-haskell">-- 混合了 JavaScript 的伪代码
instance Monad PromiseM where
  return &#x3D; a -&gt; Promise&lt;a&gt;
  Promise&lt;a&gt; &gt;&gt;&#x3D; f &#x3D; Promise&lt;a&gt;.then(f)
</code></pre>

<p>实现中我们使用 <code>of</code> 表示 Monad 的 <code>return</code> 函数，用 <code>chain</code> 表示 Monad 的 <code>&gt;&gt;=</code> 函数。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">const PromiseM: Monad &#x3D; &#123;
  of&lt;T&gt;(x: T) &#123;
    return Promise.resolve(x);
  &#125;,
  chain&lt;T1, T2&gt;(x: Promise&lt;T1&gt;, f: (x: T1) &#x3D;&gt; Promise&lt;T2&gt;) &#123;
    return x.then(f);
  &#125;,
&#125;;</code></pre>

<p>(ts 里面没有高阶泛型，哭了)</p>
<p>现在利用这个 Monad 重新整理上面的代码</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="16,25,37" data-line-offset="0"><code class="language-typescript">export const schedule &#x3D; (m: Monad) &#x3D;&gt; (thunk: () &#x3D;&gt; T) &#x3D;&gt; &#123;
  const ctx: Context &#x3D; &#123;
    effect: null as Monad_&lt;T&gt;,
    trace: [] as T[], &#x2F;&#x2F; trace 用于记录已经计算完毕的值
    pos: 0, &#x2F;&#x2F; pos 表示当前计算的 promise 是第几个
  &#125;;
  return step();

  function step(value?: T): Monad_&lt;T&gt; &#123;
    const savedContext &#x3D; context;
    &#x2F;&#x2F; 初始化为 0，每次调用的时候都从第 0 个开始计算
    ctx.pos &#x3D; 0;
    try &#123;
      context &#x3D; ctx;
      &#x2F;&#x2F; 执行计算，如果全部 promise 都已经计算完毕则正常返回
      return m.of(thunk());
    &#125; catch (e) &#123;
      &#x2F;&#x2F; 如果没有计算完毕会捕获异常
      &#x2F;&#x2F; 第 i 个 promise 没有计算完毕时
      &#x2F;&#x2F; pos 的值会停在 i
      &#x2F;&#x2F; 使用 then 在计算完毕后将值记录在 trace[pos] 的位置上
      &#x2F;&#x2F; 然后再次尝试调用 thunk
      &#x2F;&#x2F; 直到所有的值都被计算完毕
      const &#123; pos &#125; &#x3D; ctx;
      return m.chain(ctx.effect, (value: T) &#x3D;&gt; &#123;
        ctx.trace.length &#x3D; pos;
        ctx.trace[pos] &#x3D; value;
        ctx.pos &#x3D; pos + 1;
        return step(value);
      &#125;);
    &#125; finally &#123;
      context &#x3D; savedContext;
    &#125;
  &#125;
&#125;;

schedule(PromiseM)(() &#x3D;&gt; &#123;
  const value &#x3D; getValue(delay(&quot;value&quot;));
  const value2 &#x3D; getValue(delay(&quot;value2&quot;));
  console.log(value, value2);
&#125;);
</code></pre>

<p>这里将 <code>schedule</code> 函数改造为更高阶的函数，传入了一个 Monad 实例作为第一个参数。并分别使用 <code>of</code> 和 <code>chain</code> 函数替代了 <code>Promise.resolve</code> 和 <code>then</code> 函数。<code>context</code> 中的 <code>promise</code> 属性也被替换成了更加通用的 <code>effect</code> 属性。现在 <code>schedule</code> 函数可以支持其它种类的 Monad 了（啪啪啪啪啪）。</p>
<h2 id="useState"><a href="#useState" class="headerlink" title="useState"></a>useState</h2><p>接下来利用上面的 <code>schedule</code> 函数实现一个 <code>useState</code> 的 Hook。再来看一个 Monad 实例</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">const ContinuationM: Monad &#x3D; &#123;
  of&lt;T&gt;(value: T) &#123;
    return (cont: (v: T) &#x3D;&gt; T) &#x3D;&gt; cont(value);
  &#125;,
  chain&lt;T&gt;(arg: Monad_&lt;T&gt;, next: (x: T) &#x3D;&gt; Monad_&lt;T&gt;) &#123;
    return (cont: (v: T) &#x3D;&gt; T) &#x3D;&gt; arg(value &#x3D;&gt; next(value)(cont));
  &#125;
&#125;;
</code></pre>

<p>这个被称为 Continuation Monad。它与 Promise 有些类似，将值存储在闭包中返回一个函数，在调用的时候才能获取到这个值。首先将初始值包装为一个 Continuation Monad 值，与 React 的 <code>useState</code> 相同，数组的第一个参数是值，第二个是设置值的函数。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function Cont(x: string): Monad_&lt;T&gt; &#123;
  return cont &#x3D;&gt; cont([x, function next(value) &#123; cont([value, next]); &#125;]);
&#125;

function useState&lt;T&gt;(initial: T) &#123;
  return getValue(Cont(initial))!;
&#125;

schedule(ContinuationM)(() &#x3D;&gt; &#123;
  const [x, setX] &#x3D; useState(&#39;1&#39;);
  console.log(x);
  if (x !&#x3D;&#x3D; &#39;2&#39;) &#123;
    setX(&#39;2&#39;);
  &#125;
&#125;)(() &#x3D;&gt; &#123;&#125;);

 &#x2F;&#x2F; 1
 &#x2F;&#x2F; 2</code></pre>

<p>最后需要注意的是，函数已经被处理成了更高阶的函数，所以最后需要手动调用 <code>(() =&gt; &#123;&#125;)</code> 才能让它真正开始运行。为什么执行 <code>setX</code> 以后会让这一段代码重新运行呢？因为在 <code>schedule</code> 的 <code>catch</code> 代码块中，<code>m.chain</code> 的第二个参数里面包含了 <code>step</code> 函数，根据 Continuation Monad 的性质，在执行 <code>setX</code> 之后也会触发 <code>step</code> 函数的运行，此时会先更新 <code>trace</code> 中保存的值，然后执行 <code>thunk</code> 函数。最后将这个 <code>useState</code> 用到 Function Component 里面也是水到渠成了，这里借助 Class Component 的 state 处理组件的更新：</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function makeComponent(schedule: (fn: () &#x3D;&gt; void) &#x3D;&gt; void) &#123;
  return &lt;T&gt;(fc: React.FC&lt;T&gt;) &#x3D;&gt;
    class Wrapper extends React.PureComponent&lt;T&gt; &#123;
      state: &#123;
        control: React.ReactNode;
      &#125;;
      mounted: boolean;

      constructor(props) &#123;
        super(props);
        this.state &#x3D; &#123; control: null &#125;;
        &#x2F;&#x2F; state 发生变化时，重新计算 ReactNode，通过 state 更新
        schedule(() &#x3D;&gt; &#123;
          const control &#x3D; fc(props);
          if (this.mounted) &#123;
            this.setState(&#123; control &#125;);
          &#125; else &#123;
            this.state &#x3D; &#123; control &#125;;
          &#125;
        &#125;);
      &#125;
      componentDidMount() &#123;
        this.mounted &#x3D; true;
      &#125;
      render() &#123;
        return this.state.control;
      &#125;
    &#125;;
&#125;

const Component &#x3D; makeComponent(
  &#x2F;&#x2F; 把之前的 schedule 代码移到这里，在 class component 中调用
  thunk &#x3D;&gt; schedule(ContinuationM)(thunk)(() &#x3D;&gt; &#123;&#125;)
);

&#x2F;&#x2F; 高阶组件，实际上嵌套在 class component 里面
const App &#x3D; Component(() &#x3D;&gt; &#123;
  const [value, setValue] &#x3D; useState(&#39;&#39;);
  return (
    &lt;div className&#x3D;&quot;App&quot;&gt;
      &lt;input
        value&#x3D;&#123;value&#125;
        onChange&#x3D;&#123;e &#x3D;&gt; setValue(e.target.value)&#125;
      &#x2F;&gt;
    &lt;&#x2F;div&gt;
  );
&#125;);

const rootElement &#x3D; document.getElementById(&quot;root&quot;);
ReactDOM.render(&lt;App &#x2F;&gt;, rootElement);
</code></pre>

<p>这段代码在有多个 <code>useState</code> 的时候会出现问题。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">const [x, setX] &#x3D; useState(0);
const [y, setY] &#x3D; useState(1);

setY(2);
setX(1);

console.log(x, y);
&#x2F;&#x2F; 1 1</code></pre>

<p>因为在 <code>schedule</code> 函数中，<code>ctx.trace.length = pos</code> 清除了当前位置之后记录的数据，所以导致在设置 <code>x</code> 值的时候 <code>y</code> 被清除了。怎么解决这个问题呢？文章后面提到了一个库 <a href="https://github.com/awto/effectfuljs">effectfuljs</a>，以后再看吧 <code>_(:з」∠)_</code>。</p>
<h2 id="参考文献"><a href="#参考文献" class="headerlink" title="参考文献"></a>参考文献</h2><ol>
<li>V. Akimov, “When to use React Suspense vs React Hooks”, Medium, 2019.</li>
<li>B. Milewski, Category Theory for Programmers. ImageWrap, 2018.</li>
</ol>
]]>
    </content>


    <summary type="html">&lt;p&gt;最近看了 &lt;a href=&quot;https://medium.com/free-code-camp/when-to-use-react-suspense-vs-react-hooks-f66ef94cb54f&quot;&gt;一篇很有意思的文章&lt;/a&gt;，讲述了 Suspense, Hook </summary>


    <category term="FP" scheme="https://blog.means88.com/tags/FP/"/>
    
    <category term="React" scheme="https://blog.means88.com/tags/React/"/>
    
    
  </entry>
  
  <entry>
    <title>PFPL 读书笔记 3 —— 假设判断与一般判断</title>
    <link href="https://blog.means88.com/pfpl-1-3/"/>
    <id>https://blog.means88.com/pfpl-1-3/</id>
    <published>2019-06-12T20:43:12.000Z</published>
    <updated>2026-06-17T03:22:48.941Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//pfpl-1-3/cover.jpeg" /> <h1 id="假设判断与一般判断"><a href="#假设判断与一般判断" class="headerlink" title="假设判断与一般判断"></a>假设判断与一般判断</h1><h2 id="假设判断"><a href="#假设判断" class="headerlink" title="假设判断"></a>假设判断</h2><p><em>假设判断</em> 表示一个或多个假设和一个结论之间的蕴含关系。举个简单的假设判断的例子——「人被杀就会死」。其中「人被杀」是假设，「（人）就会死」是结论。其中有两个重要的概念，称为 <em>可推导性</em> 和 <em>可接受性</em>。</p>
<h3 id="可推导性"><a href="#可推导性" class="headerlink" title="可推导性"></a>可推导性</h3><p>给定一个规则的集合 $ R $，和一些判断 $ J_1,…,J_k $，我们将规则集 $ R $ 与这些判断生成的公理</p>
<p>$$ \frac{}{J_1} \quad … \quad \frac{}{J_k} $$</p>
<p>的并集表示为 $ R[J_1,…,J_k] $，称为规则集的 <em>扩展</em>。如果从这个扩展的集合中能够推导出判断 $ K $，则记为 $ J_1,…,J_k \vdash_{R} K $。其中我们将假设 $ J_1,…,J_k $ 作为一种「临时公理」，与规则集 $ R $ 一起推导出结论 $ K $。此时称判断 $ K $ 是<em>可推导的</em>。</p>
<p>一般使用大写的希腊字母 $ \Gamma $ 或 $ \Delta $ 表示有限的判断集合，如设 $ \Gamma $ 为 $ J_1,…,J_k $，上面的式子就可以简写为 $ R[\Gamma] $ 和 $ \Gamma \vdash_{R} K $。另外也可以使用 $ \vdash_{R} \Gamma $ 表示对于每个 $ \Gamma $ 中的判断 $ J $，$ \vdash_{R} J $ 都成立。</p>
<p>$ J_1,…,J_n \vdash_{R} J $ 的另一种说法是，规则</p>
<p>$$ \frac{J_1 ~ … ~ J_n}{J} \tag{3.1} $$</p>
<p>可以通过 $ R $ 推导得出。</p>
<details>
<summary>$ 规则(2.2) $</summary>
$$ \frac{}{\text{zero} ~ \text{nat}} \tag{2.2a} $$
$$ \frac{a ~ \text{nat}}{succ(a) ~ \text{nat}} \tag{2.2b} $$
</details>

<p>使用前一章的规则 $ (2.2) $ 举个例子</p>
<p>$$ a ~ \text{nat} \vdash_{(2.2)} succ(succ(a)) ~ \text{nat} \tag{3.2} $$</p>
<p><strong>定理 3.1（稳定性）.</strong> 如果 $ \Gamma \vdash_{R} J $，那么 $ \Gamma \vdash_{R \cup R’} J $。</p>
<p>因为 $ R $ 中的规则都存在于 $ R \cup R’ $ 中，因此这条定理是显而易见的。同样地还具备以下性质：</p>
<p><strong>自反性.</strong> $ \Gamma,J \vdash_{R} J $. 任何假设可以推导出自身作为结论。</p>
<p><strong>弱化性.</strong> 如果 $ \Gamma \vdash_{R} J $，那么 $ \Gamma,K \vdash_{R} J $. 多余的扩展不会影响结论，这条与稳定性定理类似。</p>
<p><strong>可传递性.</strong> 如果 $ \Gamma,K \vdash_{R} J $ 且 $ \Gamma \vdash_{R} K $，那么 $ \Gamma \vdash_{R} J $. 这条也可以通过规则推导定理得到。</p>
<h3 id="可接受性"><a href="#可接受性" class="headerlink" title="可接受性"></a>可接受性</h3><p><em>可接受性</em> 同样表示规则和判断之间的关系。$ \Gamma \vDash_{R} J $ 表示当所有假设 $ \Gamma $ 都能由规则集 $ R $ 推导时，$ J $ 也能由 $ R $ 推导出来。</p>
<p>$$ succ(a) ~ \text{nat} \vDash_{(2.2)} a ~ \text{nat} \tag{3.6} $$</p>
<p>这条判断是成立的，因为根据 $ (2.2b) $，可以通过反向查询得出，如果 $ succ(a) ~ \text{nat} $ 必然有 $ a ~ \text{nat} $。</p>
<p>可接受性与可推导性具有高度相似的性质：</p>
<p><strong>自反性.</strong> $ \Gamma,J \vDash_{R} J $.</p>
<p><strong>弱化性.</strong> 如果 $ \Gamma \vDash_{R} J $，那么 $ \Gamma,K \vDash_{R} J $.</p>
<p><strong>可传递性.</strong> 如果 $ \Gamma,K \vDash_{R} J $ 且 $ \Gamma \vDash_{R} K $，那么 $ \Gamma \vDash_{R} J $.</p>
<p><strong>定理 3.2.</strong> 如果 $ \Gamma \vdash_{R} J $，那么 $ \Gamma \vDash_{R} J $。</p>
<p><em>证明：</em> 根据可推导性的传递性可以得到，如果 $ \Gamma \vdash_{R} J $ 且 $ \vdash_{R} \Gamma $，则 $ \vdash_{R} J $。符合可接受性的定义。</p>
<p>也就是说，如果一条判断是可推导的，那它必然也是可接受的。</p>
<h2 id="假设归纳定义"><a href="#假设归纳定义" class="headerlink" title="假设归纳定义"></a>假设归纳定义</h2><p>我们可以在归纳定义中的假设和结论中使用可推导性的判断。这里可以引出两个概念：<em>局部假设</em> 和 <em>全局假设</em>。其中局部假设只对特定的前提有效，而全局假设对所有的前提和结论都有效。一个 <em>假设归纳定义</em> 由一组 <em>假设规则</em> 组成，具有以下形式：</p>
<p>$$ \frac{\Gamma ~ \Gamma_1 \vdash J_1 ~ … ~ \Gamma ~ \Gamma_n \vdash J_n}{\Gamma \vdash J} \tag{3.9} $$</p>
<p>假设 $ \Gamma $ 为全局假设，$ \Gamma_i $ 为第 $ i $ 个前提的局部假设。这条规则的含义为，如果所有 $ J_i $ 可以被 $ \Gamma~\Gamma_i $ 导出，那么 $ J $ 也可以被 $ \Gamma $ 导出。在很多情况下，全局规则会在上下文中给出，此时可以省略全局规则写为</p>
<p>$$ \frac{\Gamma_1 \vdash J_1 ~ … ~ \Gamma_n \vdash J_n}{J} \tag{3.10} $$</p>
<p><em>形式化的可推导性判断</em> $ \Gamma \vdash J $ 由一个基本判断的有限集 $ \Gamma $ 与一个基本判断组成。假设规则集 $ R $ 表示满足以下规则的强闭合规则集合：</p>
<p>$$ \frac{}{\Gamma,J \vdash J} \tag{3.11a} $$</p>
<p>$$ \frac{\Gamma \vdash J}{\Gamma,K \vdash J} \tag{3.11b} $$</p>
<p>$$ \frac{\Gamma \vdash K \quad \Gamma,K \vdash J}{\Gamma \vdash J} \tag{3.11c} $$</p>
<p>假设归纳定义是普通归纳定义加上假设判断的扩展，因此与之前类似，如果想证明性质 $ P(\Gamma \vdash J) $ 对于任意 $ \Gamma \vdash J $ 成立，我们需要证明：如果任意 $ P(\Gamma~\Gamma_i \vdash J_i) $ 成立，那么 $ P(\Gamma \vdash J) $。</p>
<h2 id="一般判断"><a href="#一般判断" class="headerlink" title="一般判断"></a>一般判断</h2><p>一般判断用来表示包含变量的判断。在一般的数学理论中，变量是一个特定集合中未知的对象。一个 <em>一般的</em> 判断表示一个判断对于变量的任意取值都成立。另外一般判断中还包含对参数的处理。我们用 $ \Gamma \vdash_{R}^{U:X} J $ 表示在规则集 $ R $ 以及绑定的参数 $ U $ 和变量 $ X $ 的情况下，$ \Gamma $ 可以推导出 $ J $。一般可推导性可以被定义为：</p>
<p>$$ \vec{x} \mid \Gamma \vdash_{R}^{X} J \iff \forall\pi:\vec{x} \leftrightarrow \vec{x}’\pi\cdot\Gamma \vdash_{R}^{X,\vec{x}’} \pi\cdot J $$</p>
<p>即对于任意的重命名 $ \pi:\vec{x} \leftrightarrow \vec{x}’ $，$ \Gamma $ 都可以推导出 $ J $。以下的一般推导</p>
<p>$$ \frac{\frac{\frac{}{x ~ \text{nat}}}{succ(x) ~ \text{nat}}}{succ(succ(x)) ~ \text{nat}} $$</p>
<p>可以用于证明判断</p>
<p>$$ x \mid x ~ \text{nat} \vdash_{(2.2)}^{X} succ(succ(x)) ~ \text{nat} $$</p>
<p>一般可推导性判断具备以下性质</p>
<p><strong>扩散性.</strong> 如果 $ \vec{x} \mid \Gamma \vdash_{R}^{X} J $，那么 $ \vec{x},x \mid \Gamma \vdash_{R}^{X} J $。多余的变量不影响结果。</p>
<p><strong>重命名.</strong> 如果 $ \vec{x},x \mid \Gamma \vdash_{R}^{X} J $，那么 $ \vec{x},x \mid [x \leftrightarrow x’] \cdot \Gamma \vdash_{R}^{X} [x \leftrightarrow x’] J $ 对于任意 $ x’ \notin X,\vec{x}’ $ 成立。</p>
<p><strong>变量应用.</strong> 如果 $ \vec{x},x \mid \Gamma \vdash_{R}^{X} J $ 且 $ a \in B[X,\vec{x}] $，那么 $ \vec{x} \mid [a/x] \Gamma \vdash_{R}^{X} [a/x] J $。变量可以应用为实际的值。</p>
<p>参数化的可推导性和变量类似：</p>
<p>$$ \vec{u};\vec{x} \mid \Gamma \vdash_{R}^{U;X} J \iff \forall\rho:\vec{u}\leftrightarrow\vec{u}’  ~ \forall\pi:\vec{x} \leftrightarrow \vec{x}’ \rho\cdot\pi\cdot\Gamma \vdash_{R}^{U,\vec{u}’;X,\vec{x}’} \rho\cdot\pi\cdot J $$</p>
<h2 id="一般归纳定义"><a href="#一般归纳定义" class="headerlink" title="一般归纳定义"></a>一般归纳定义</h2><p><em>一般归纳定义</em> 在普通的假设归纳定义的基础上扩展了变量的使用，一条一般规则具有以下形式：</p>
<p>$$ \frac{\vec{x}\vec{x_1} \mid \Gamma ~ \Gamma_1 \vdash J_1 ~ … ~ \vec{x}\vec{x_n} \mid \Gamma ~ \Gamma_n \vdash J_n}{\vec{x} \mid \Gamma \vdash J} \tag{3.12} $$</p>
<p>类似地，$ \vec{x} $ 是规则中的 <em>全局变量</em>，而 $ \vec{x_i} $ 是每个前提的 <em>局部变量</em>。全局变量也可以被省略，记为</p>
<p>$$ \frac{\vec{x_1} \mid \Gamma_1 \vdash J_1 ~ … ~ \vec{x_n} \mid \Gamma_n \vdash J_n}{J} \tag{3.13} $$</p>
<p>为了保证一般判断符合推导规则，需要满足：</p>
<p>$$ \frac<br>  {}<br>  {\vec{x} \mid \Gamma,J \vdash J}<br>\tag{3.14a} $$</p>
<p>$$ \frac<br>  {\vec{x} \mid \Gamma \vdash J}<br>  {\vec{x} \mid \Gamma,J’ \vdash J}<br>\tag{3.14b} $$</p>
<p>$$ \frac<br>  {\vec{x} \mid \Gamma \vdash J}<br>  {\vec{x},x \mid \Gamma \vdash J}<br>\tag{3.14c} $$</p>
<p>$$ \frac<br>  {\vec{x},x’ \mid [x \leftrightarrow x’] \cdot \Gamma \vdash [x \leftrightarrow x’] \cdot J}<br>  {\vec{x},x \mid \Gamma \vdash J}<br>\tag{3.14d} $$</p>
<p>$$ \frac<br>  {\vec{x} \mid \Gamma \vdash J \quad \vec{x} \mid \Gamma,J \vdash J’}<br>  {\vec{x},x \mid \Gamma \vdash J’}<br>\tag{3.14e} $$</p>
<p>$$ \frac<br>  {\vec{x},x \mid \Gamma \vdash J \quad a \in B[\vec{x}]}<br>  {\vec{x} \mid [a/x] \Gamma \vdash [a/x]J}<br>\tag{3.14f}<br>$$</p>
<h2 id="总结"><a href="#总结" class="headerlink" title="总结"></a>总结</h2><p>这部分介绍了假设判断和一般判断，将前面提到的规则扩展到了更加复杂的形式。规则中可以包含更加复杂的逻辑判断，并且可以处理变量和参数。假设判断中的可推导性和可接受性表达了逻辑中的蕴含关系。这两个性质有很多相似的地方，暂时没有找到合适的形象的例子来区分二者。但是总得来说可推导性比可接受性更加“严格”一些。</p>
<p>终于整完第一部分了，写公式太麻烦了，弃坑之。。</p>
]]>
    </content>


    <summary type="html">&lt;h1 id=&quot;假设判断与一般判断&quot;&gt;&lt;a href=&quot;#假设判断与一般判断&quot; class=&quot;headerlink&quot; title=&quot;假设判断与一般判断&quot;&gt;&lt;/a&gt;假设判断与一般判断&lt;/h1&gt;&lt;h2 id=&quot;假设判断&quot;&gt;&lt;a href=&quot;#假设判断&quot; class=&quot;headerli</summary>


    <category term="PFPL" scheme="https://blog.means88.com/tags/PFPL/"/>
    
    
  </entry>
  
  <entry>
    <title>PFPL 读书笔记 2 —— 归纳定义</title>
    <link href="https://blog.means88.com/pfpl-1-2/"/>
    <id>https://blog.means88.com/pfpl-1-2/</id>
    <published>2019-05-03T18:22:46.000Z</published>
    <updated>2026-06-17T03:22:48.941Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//pfpl-1-2/cover.jpeg" /> <h1 id="归纳定义"><a href="#归纳定义" class="headerlink" title="归纳定义"></a>归纳定义</h1><p>在学习编程语言的过程中，归纳定义是必不可少的工具。一个归纳定义是由各种各样 判断 的推导过程形成的 规则 集合组成的。判断是某个特定类别的语法对象的表达式。规则表述了一条判断有效的充分必要条件。</p>
<h2 id="判断"><a href="#判断" class="headerlink" title="判断"></a>判断</h2><p>判断是一个语法对象的表达式，举例来说：</p>
<table>
<thead>
<tr>
<th>判断表达式</th>
<th>含义</th>
</tr>
</thead>
<tbody><tr>
<td>$ n ~ nat $</td>
<td>$ n $ 是一个自然数</td>
</tr>
<tr>
<td>$ n = n_1 + n_2 $</td>
<td>$ n $ 是 $ n_1 $ 和 $ n_2 $ 的和</td>
</tr>
<tr>
<td>$ \tau ~ type $</td>
<td>$ \tau $ 是一个类型</td>
</tr>
<tr>
<td>$ e:\tau $</td>
<td>表达式 $ e $ 具有类型 $ \tau $</td>
</tr>
<tr>
<td>$ e \Downarrow v $</td>
<td>表达式的值为 $ v $</td>
</tr>
</tbody></table>
<p>一条判断表示语法对象具有某种性质或者几个语法对象直接有某种关系。这种性质或者关系被称为 <em>判断式</em>，这里的语法对象称为这种判断形式的 <em>实例</em>。判断式也被称为 <em>谓语</em>，对应的实例被称为 <em>主语</em>。我们用 $ a ~ J $ 表示断言 $ J $ 对 $ a $ 成立。不需要关心判断的主语时，用 $ J $ 来表示不确定的判断。为了能够更直观地表达，可能会使用前缀，中缀或混合词缀表示一条特定的判断。</p>
<h2 id="推理规则"><a href="#推理规则" class="headerlink" title="推理规则"></a>推理规则</h2><p>一个判断式的 归纳定义 由一组规则组成。一条 规则 可以表示为</p>
<p>$$ \frac{J_1…J_k}{J} $$</p>
<p>在横线以上的称为这条规则的 <em>假设</em>，横线以下的称为它的 <em>结论</em>。如果一条规则没有假设，那么这条规则被称为 公理。一条规则所表示的意思是它的假设是它的结论的 <em>充分条件</em>：要证明 $ J $ ，只需要证明 $ J_1…,J_k $ 。当 $ k $ 为 $ zero $ 时，它的结论永远都是成立的。一般地，可能会有多条规则拥有同样的结论，因此一条规则的结论成立不一定意味着它的假设也成立，结论可能可以由其它的规则推导出来。</p>
<p>举例来说，以下规则是一条判断 $ a ~ \text{nat} $ 的归纳定义：</p>
<p>$$ \frac{}{\text{zero} ~ \text{nat}} \tag{2.2a} $$</p>
<p>$$ \frac{a ~ \text{nat}}{succ(a) ~ \text{nat}} \tag{2.2b} $$</p>
<p>这两条规则说明了当 $ a $ 是 $ \text{zero} $ 或者是另一个自然数的后继时，是一个自然数。类似地，也可以给出一棵二叉树的定义：</p>
<p>$$ \frac{}{\text{empty} ~ \text{tree}} \tag{2.3a} $$</p>
<p>$$ \frac{a_1 ~ \text{tree} \quad a_2 ~ \text{tree}}{node(a_1;a_2) ~ \text{tree}} \tag{2.3b} $$</p>
<p>这两条规则说明一棵二叉树要么为空，要么两个节点都是一棵二叉树。</p>
<p>表示自然数 $ a $ 和 $ b $ 相等的判断 $ a = b $ 可以定义为：</p>
<p>$$ \frac{}{\text{zero} = \text{zero} ~ \text{nat}} \tag{2.4a} $$</p>
<p>$$ \frac{a = b ~ \text{nat}}{succ(a) = succ(b) ~ \text{nat}} \tag{2.4b} $$</p>
<p>在这些例子中我们都使用有限的形式声明了无限个规则。</p>
<p>如果有一些规则，通过这些规则可以推导出一条判断，就说这条判断 $ J $ 闭合与这些规则。如果这些规则同时还是必要 的，称判断 $ J $ 强闭合于这些规则。</p>
<h2 id="推导过程"><a href="#推导过程" class="headerlink" title="推导过程"></a>推导过程</h2><p>要证明一条归纳定义的判断成立，只需要列出它的 <em>推导过程</em>。推导过程从公理开始，结束于要证明的判断。它可以被看成是一棵树，一个节点的子树就是它的假设的推导过程。如果</p>
<p>$$ \frac{J_1…J_k}{J} $$</p>
<p>且 $ \Delta_1,…,\Delta_k $ 分别是这些假设的推导过程，可以将 $ J $ 的推导过程写为</p>
<p>$$ \frac{\Delta_1…\Delta_k}{J} $$</p>
<p>例如， $ succ(succ(succ(\text{zero}))) ~ \text{nat} $ 的推导过程写为</p>
<p>$$ \frac{\frac{\frac{\text{zero} ~ \text{nat}}{succ(\text{zero}) ~ \text{nat}}}{succ(succ(\text{zero})) ~ \text{nat}}}{succ(succ(succ(\text{zero}))) ~ \text{nat}} \tag{2.5} $$</p>
<p>要证明一条判断能被推导出来，只需要找到一个推导过程。主要有两种方法用于得到推导过程。一个是 <em>正向查询</em>，从公理出发，直到推导出最终结论。另一个是 <em>反向查询</em>，是从结论出发直到顶层的假设都为公理。正向查询维护一个判断的集合，初始为空，然后找到所有假设都在该集合中的规则，将它的结论也加入集合，直到需要推导的判断出现在这个集合中。如果一条判断是可推导的，那么这个方法总是可以找到它的推导过程，但是如果一条判断无法被推导，那么运算永远不会终止，此时无法判断它是否可以推导。反向查询则维护一个队列，初始时只有这条需要推导的判断，随后每一次操作都移除队列中的一条判断，将它的假设加入队列中，如果有多条规则可以推导出这条判断，那么需要分别执行这个过程，知道队列为空。如果一条判断是可推导的，这个方法也能找到它的推导过程，但是同样地，如果一条判断不可被推导，那么可能会有无限条规则加入到队列中，永远不会被清空。</p>
<h2 id="规则归纳"><a href="#规则归纳" class="headerlink" title="规则归纳"></a>规则归纳</h2><p>如果当 $ P(J_1),…,P(J_k) $ 成立时， $ P(J) $ 也成立，那么称 $ P $ 闭合于规则</p>
<p>$$ \frac{J_1…J_k}{J} $$</p>
<p>规则归纳表示如果 $ P $ 闭合于一些规则，那么 $ P $ 对于任何由这些规则定义的判断 $ J $ 是成立的。例如对于规则 $ (2.2) $ 要证明 $ P(a ~ \text{nat}) $ ，只要证明：</p>
<ol>
<li>$ P(\text{zero} ~ \text{nat}) $</li>
<li>对于任意 $ a $ ，如果 $ a ~ \text{nat} $ 且 $ P(\text{zero} ~ \text{nat}) $ ，那么 $ succ(a) ~ \text{nat} $ 且 $ P(succ(a) ~ \text{nat}) $</li>
</ol>
<p>这个与数学归纳法很像，它是规则归纳的一个特例。</p>
<p>类似地对于规则 $ (2.3) $ ，要证明 $ P(a ~ \text{tree}) $ 对于任何 $ a ~ \text{tree} $ 成立，只需要证明：</p>
<ol>
<li>$ P(\text{empty} ~ \text{tree}) $</li>
<li>对于任意 $ a_1 $ 和 $ a_2 $ ，如果 $ a_1 ~ \text{tree} $ ，$ P(a_1 ~ \text{tree}) $ 且 $ a_2 ~ \text{tree} $ ，$ P(a_2 ~ \text{tree}) $ ，那么可以得出 $ node(a_1;a_2) ~ \text{tree} $ 与 $ P(node(a_1;a_2) ~ \text{tree}) $</li>
</ol>
<p>这被称为树形归纳，也是规则归纳的一种形式。</p>
<p>用这种方法可以证明很多性质，比如：</p>
<p><strong>引理.</strong> 如果 $ a ~ \text{nat} $ ，那么 $ a = a ~ \text{nat} $</p>
<p><em>证明：</em>根据规则 $ (2.4a) $ ，$ \text{zero} = \text{zero} ~ \text{nat} $ 。假设 $ a = a ~ \text{nat} $，那么根据规则 $ (2.4b) $ ， $ succ(a) = succ(a) ~ \text{nat} $ 成立。</p>
<p>类似地也能证明如果 $ succ(a_1) = succ(a_2) $ ，则 $ a_1 = a_2 ~ \text{nat} $ 。</p>
<h2 id="迭代归纳与相互归纳"><a href="#迭代归纳与相互归纳" class="headerlink" title="迭代归纳与相互归纳"></a>迭代归纳与相互归纳</h2><p>归纳定义经常是迭代定义的，即一条归纳定义是在另一条的基础上构成的。在迭代归纳定义中，一条规则的假设即可能是之前有定义的判断，也可以是当前定义的判断，例如定义一个自然数列表 [公式] 为 [公式] ：</p>
<p>$$ \frac{}{nil ~ \text{list}} \tag{2.7a} $$</p>
<p>$$ \frac{a ~ \text{nat} \quad b ~ \text{list}}{cons(a;b) ~ \text{list}} \tag{2.7b} $$</p>
<p>第一条假设 $ a ~ \text{nat} $ 是前面定义过的判断，而第二条 $ b ~ \text{list} $ 则是当前正在定义的。</p>
<p>很多时候，有两条或者更多判断使用相互归纳的方式同时定义。相互归纳定义推导出多条判断，其中每一条判断都可能出现在其中一些规则的假设中。因为它们在定义的时候彼此依赖，所以只能同时给出它们的定义。例如定义一个自然数是奇数或者偶数：</p>
<p>$$ \frac{}{\text{zero} ~ \text{even}} \tag{2.8a} $$</p>
<p>$$ \frac{a ~ \text{odd}}{succ(a) ~ \text{even}} \tag{2.8b} $$</p>
<p>$$ \frac{a ~ \text{even}}{succ(a) ~ \text{odd}} \tag{2.8c} $$</p>
<p>类似地根据规则归纳，如果要证明对于任意 $ a ~ \text{even} $ 有 $ P(a ~ \text{even}) $ ，对于任意 $ a ~ \text{odd} $ 有 $ P(a ~ \text{odd}) $ ，只需要证明：</p>
<ol>
<li>$ P(\text{zero} ~ \text{odd}) $</li>
<li>如果 $ P(a ~ \text{odd}) $ 那么 $ P(succ(a) ~ \text{even}) $</li>
<li>如果 $ P(a ~ \text{even}) $ 那么 $ P(succ(a) ~ \text{odd}) $</li>
</ol>
<p>举一个最简单的例子，证明 (1) 如果 $ a ~ \text{even} $ 则 $ a ~ \text{nat} $ ，(2) 如果 $ a ~ \text{odd} $ 则 $ a ~ \text{nat} $ ：</p>
<ol>
<li>根据 $ (2.2a) $ 显然 $ \text{zero} ~ \text{nat} $</li>
<li>根据 $ (2.2b) $ ，如果 $ a ~ \text{odd} $ 时有 $ a ~ \text{nat} $ 则 $ succ(a) ~ \text(nat) $</li>
<li>根据 $ (2.2b) $ ，如果 $ a ~ \text{even} $ 时有 $ a ~ \text{nat} $ 则 $ succ(a) ~ \text(nat) $</li>
</ol>
<p>因此得证。</p>
<h2 id="用规则定义函数"><a href="#用规则定义函数" class="headerlink" title="用规则定义函数"></a>用规则定义函数</h2><p>归纳定义也经常被用来定义函数，这时只需要给出输入与输出的对应关系，并且证明输出是由输入唯一确定的即可。例如定义一个自然数的加法 $ sum(a;b;c) $，表示 $c$ 为 $a$ 与 $b$ 的和：</p>
<p>$$ \frac{b ~ \text{nat}}{sum(\text{zero};b;b)} \tag{2.9a} $$</p>
<p>$$ \frac{sum(a;b;c)}{sum(succ(a);b;succ(c))} \tag{2.9b} $$</p>
<p>这两条规则定义了一个自然数的三元关系，我们需要证明 $ c $ 是由 $ a $ 和 $ b $ 确定的。</p>
<p>定理. 对于任意的 $ a ~ \text{nat} $ 和 $ b ~ \text{nat} $ 都存在唯一的 $ c $ 符合 $ sum(a;b;c) $ 。</p>
<p><em>证明：</em>这里的证明分为两个部分：</p>
<ol>
<li>（存在性）如果 $ a ~ \text{nat} $ 且 $ b ~ \text{nat} $ ，存在 $ c $ 使得 $ sum(a;b;c) $</li>
<li>（唯一性）如果 $ sum(a;b;c) $ 且 $ sum(a;b;c’) $ ，则 $ c = c’ $</li>
</ol>
<p>存在性：设 $ P(a ~ \text{nat}) $ 的含义为 对于任意 $ b ~ \text{nat} $ 存在 $ c $ 使得 $ sum(a;b;c) $。</p>
<ol>
<li>当 $ a $ 为 $ \text{zero} $ 时，根据 $ (2.9a) $ 显然成立，此时 $ c = b $ 。</li>
<li>假设 $ P(a ~ \text{nat}) $ 成立，需要证明 $ P(succ(a) ~ \text{nat}) $ 成立，即对于任意 $ b ~ \text{nat} $ 存在 $ c $ 使得 $ sum(succ(a);b;c) $ 。因为 $ P(a ~ \text{nat}) $ ，因此对于这个 $ b $ 存在 $ c’ $ 使得 $ sum(a;b;c’) $ 。根据 $ (2.9b) $ 有 $ sum(succ(a);b;succ(c’)) $ ，因此可令 $ c = succ(c’) $ 。</li>
</ol>
<p>唯一性：我们证明如果 $ sum(a;b;c_1) $ 与 $ sum(a;b;c_2) $ ，则 $ c_1 = c_2 ~ \text{nat} $ 。</p>
<ol>
<li>当 $ a = \text{zero} $ 时，根据 $ (2.9a) $ 有 $ c_1 = b $ 与 $ c_2 = b $ 。根据前面的引理可得 $ c_1 = c_2 $ 。</li>
<li>设 $ sum(a’;b;c_1’) $ ， $ a = succ(a’) $ ， $ c_1 = succ(c_1’) $ 。如果 $ sum(a;b;c_2) $ ，根据 $ (2.9b) $ 有 $ sum(succ(a’);b;succ(c_1’)) $ ，即 $ sum(a;b;c_1) $ ，因为它们来源于同一条规则所以 $ c_1 = c_2 $ 。</li>
</ol>
<h2 id="模式"><a href="#模式" class="headerlink" title="模式"></a>模式</h2><p>在一条判断中，一些参数是由另外参数决定的，这被称为判断的 模式声明。例如自然数加法 $ sum(a;b;c) $ 具有模式 $ (\forall, \forall, \exists) $ 。它表示对于任意 $ a ~ \text{nat} $ 与任意 $ b ~ \text{nat} $ 都存在 $ c $ 使得 $ sum(a;b;c) $ 。如果要说明 $ c $ 是唯一确定的，就写为 $ (\forall, \forall, \exists!) $ 。如果 $ c $ 不一定存在，写为 $ (\forall, \forall, \exists^{\leq1}) $ ，意为对于任意 $ a ~ \text{nat} $ 与任意 $ b ~ \text{nat} $ 最多存在一个 $ c $ 使得 $ sum(a;b;c) $ 。</p>
<p>可以看到，一条判断可能同时满足多个模式声明。一般来说，全称量词修饰的参数被当做是输入，而存在量词修饰的参数当做输出。但是一般会有一个我们希望的主要的模式，一般使用等号来表达输入和输出的关系，例如重新定义加法：</p>
<p>$$ \frac{a ~ \text{nat}}{a + \text{zero} = a ~ \text{nat}} \tag{2.10a} $$</p>
<p>$$ \frac{a + b = c ~ \text{nat}}{a + succ(b) = succ(c) ~ \text{nat}} \tag{2.10b} $$</p>
<p>用这种方式表示等号右侧的参数是由左边的参数决定的。当 $ a + b = c ~ \text{nat} $ 时，可以直接使用 $ a + b $ 来表示 $ c $ 。</p>
<h2 id="总结"><a href="#总结" class="headerlink" title="总结"></a>总结</h2><p>这部分介绍了归纳定义以及它的一些使用。我们不仅可以使用归纳的方法定义一些判断，同时还可以使用归纳的方法证明它们的一些性质。其中基于自然数定义的归纳方法就是通常情况下所说的数学归纳法，另外还可以通过类似的方法把归纳法推广到任何拥有类似结构的定义，如上面提到的树形归纳和相互归纳。归纳定义也可以用来定义函数，一条判断中的一些参数可能由另一些参数决定，它们分别可以看成函数的输入与输出，这些性质决定了它符合哪些模式声明。</p>
]]>
    </content>


    <summary type="html">&lt;h1 id=&quot;归纳定义&quot;&gt;&lt;a href=&quot;#归纳定义&quot; class=&quot;headerlink&quot; title=&quot;归纳定义&quot;&gt;&lt;/a&gt;归纳定义&lt;/h1&gt;&lt;p&gt;在学习编程语言的过程中，归纳定义是必不可少的工具。一个归纳定义是由各种各样 判断 的推导过程形成的 规则 集合组成的。判断是</summary>


    <category term="PFPL" scheme="https://blog.means88.com/tags/PFPL/"/>
    
    
  </entry>
  
  <entry>
    <title>PFPL 读书笔记 1 —— 语法对象</title>
    <link href="https://blog.means88.com/pfpl-1-1/"/>
    <id>https://blog.means88.com/pfpl-1-1/</id>
    <published>2019-03-30T16:32:43.000Z</published>
    <updated>2026-06-17T03:22:48.936Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//pfpl-1-1/cover.png" /> <h1 id="语法对象"><a href="#语法对象" class="headerlink" title="语法对象"></a>语法对象</h1><p>编程语言是一种语言，它们用于表示计算机和人类都能理解的计算过程。一门编程语言的语法确定了它可以由哪些语句组成。那么这些语句是如何确定的，程序是如何组成的呢？</p>
<p>当提到语法的时候，可能表示的是几个不同的概念。一个是 <em>表层语法</em>，表示语句是如何输入并展示在计算机上的，通常是一些字符串等形式。而 <em>抽象语法</em> 表示语句之间是如何组合在一起的。从这个层面来说，语法是一颗树，称为 <em>抽象语法树</em>。这种树的节点是运算符，将几个语句组合在一起。另外还有关于标识符的声明和使用的问题，这部分结构称为 <em>绑定</em>。这个层次的语法称为 <em>抽象绑定树</em>，它在 <em>抽象语法树</em> 的基础上增加了绑定和作用域的概念。</p>
<h2 id="抽象语法树"><a href="#抽象语法树" class="headerlink" title="抽象语法树"></a>抽象语法树</h2><p>一棵 <em>抽象语法树</em>（<em>abstract syntax tree</em>，简称为 <em>ast</em>），是一棵有序树。它的叶子节点是 <em>变量</em>，内部节点是 <em>运算符</em>，<em>运算符</em> 的参数是它的子树。Ast 可以分为很多种 <em>类别</em>，表示不同形式的语法。<em>变量</em> 代表特定类别的语法中一个未确定的片段。Ast 可以用 <em>运算符</em> 组合起来。<em>运算符</em> 具有类别和 <em>参数表</em>，<em>参数表</em> 使用类别的有限序列来表示它的参数数量和每个参数的类别。举例来说，如果一个运算符具有类别 $ s ​$ 和参数表 $ s_1,…,s_n ​$，那么它可以将 $ n ​$ 个分别属于类别 $ s_1,…,s_n ​$ 的 ast 组合成一个类别 $ s ​$ 的 ast。如果一个运算符不接受参数，那么称它为 <em>零元</em> 运算符，同理还有 <em>一元</em> 运算符、<em>二元</em> 运算符等等。</p>
<p>变量在其中是一个很重要的概念。在数学领域，变量一般表示某个作用域下的未知对象（如未知的实数），而在这里变量表示的是某个类别的 ast。因为这是一个未知的量，所以只有在 <em>代换</em> 的时候变量才能获得意义。例如数学中我们可能会将 $ \pi $ 代入 $ x $ 计算结果。在 ast 中也是类似的，只需要将一个 ast 中的变量换成另一个 ast 即可。</p>
<p>举例来说，有一门简单的语言用于表示数字、加法和乘法。它的语法中只有一个类别 Exp，以及一个无限的运算符集合：$ num[n] $, $ n \in N $，包含 Exp 类别的零元运算符，$ plus $ 和 $ times $ 是二元运算符，且参数都是 Exp 类别的。如这个含 $ x $ 的表达式 $ 2 + (3 \times x) $ 可以表示为 ast</p>
<p>$$ plus(num[2];times(num[3]; x)) $$</p>
<!-- <img src="1-1-ast.png" alt="ast" width="150" style="display:block; margin: 0 auto" /> -->

<p>如果将 $ num[4] $ 代入 $ x $，就能得到 ast</p>
<p>$$  plus(num[2];times(num[3]; num[4]))  $$</p>
<!-- <img src="1-1-ast2.png" alt="ast" width="150" style="display:block; margin: 0 auto" /> -->

<p>即表达式 $ 2 + (3 \times 4) $。当然也可以将其它 ast 代入 $ x $ 得到更加复杂的结果。</p>
<p>Ast 的树形结构支持一种非常有用的原则推理，称为 <em>结构归纳</em>。假设我们想证明对于一个类别中所有的 ast，$ a ​$，都具有性质 $ P(a) ​$，那么可以考虑所有 $ a ​$ 是怎么生成的，并且证明在每种情况下都具有该性质。所以根据刚才对 Exp 的定义，我们需要证明</p>
<ol>
<li>所有 Exp 类别的变量 $ x $ 都具有该性质：$ P(x) $.</li>
<li>对于所有 $ n \in N $，$ num[n] $ 都具有该性质：$ P(num[n]) $, $ n \in N $</li>
<li>假设 $ a1 $，$ a2 $ 都具有该性质，证明 $ plus(a1;a2) $，$ times(a1;a2) $ 都具有该性质：if $ P(a1) $ and $ P(a2) $, then $ P(plus(a1;a2)) $ and $ P(times(a1;a2)) $.</li>
</ol>
<p>因为以上过程说明了所有 $ a ​$ 的可能性，所以可以证明 $ P(a) ​$ 对所有 Exp 类别的 ast 成立。</p>
<p>接下来考虑更加一般的情况。设 $ S ​$ 是类别的有限集合，$ \{ O_s \}<em>{s \in S} ​$ 是运算符族，其中的运算符 $ o ​$ 都属于类别 $ s ​$，参数表为 $ ar(o) = (s_1,…s_n) ​$。设 $ \{X_s\}</em>{s \in S} ​$ 为类别 $ s ​$ 的变量族。那么类别 $ s ​$ 的 ast 族 $ A[X] = \{A[x]_s\} _{s \in S}  $ 的定义如下：</p>
<ol>
<li>一个类别 $ s $ 的变量是 $ s $ 的一个 ast：if $ x \in X_s $, then $ x \in A[X]_s $.</li>
<li>运算符可以组合 ast：if $ o \in O_s $, $ ar(o) = (s_1,…s_n) $ and $ a_1 \in A[X]<em>{s_1} $,…,$ a_n \in A[X]</em>{s_n} $, then $ o(a_1;…;a_n) \in A[X]_s $.</li>
</ol>
<p>同样地，这个方法也可以用于证明所有 ast 具有性质 $ P $。要证明所有 $ a \in A[X] $ 具有性质 $ P(a) $，只需要证明：</p>
<ol>
<li>if $ x \in X_s $, then $ P_s(x) $.</li>
<li>if $ o \in O_s ​$ and $ ar(o) = (s_1,…,s_n) ​$, then if $ P_{s_1}(a_1) ​$ and … and $ P_{s_n}(a_n) ​$, then $ P_s(o(a_1;…;a_n)) ​$.</li>
</ol>
<p>根据上面的原理，我们可以轻松地证明如果 $ X \subseteq Y ​$，则 $ A[X] \subseteq A[Y] ​$。</p>
<p>如果 $ X $ 是一个变量族，$ x $ 是一个类别 $s$ 的变量且 $ x \notin X_s $，那么称 $ X, x $ 为将 $ x $ 邻接于 $ X $，具体含义如下：</p>
<p>$$ \begin{equation}<br>X,x =<br>\begin{cases}<br>X_i \cup \{x\}&amp; i=s\\<br>X_i&amp; i \neq s<br>\end{cases}<br>\quad i \in S<br>\end{equation} $$</p>
<!-- <img src="1-1-adjoin.png" alt="adjoin" width="500" style="display:block; margin: 0 auto" /> -->

<p><em>代换</em> 赋予变量意义。如果 $ x ​$ 是 $ s ​$ 类别的变量，$ a \in A[X, x] _ {s’} ​$，且 $ b \in A[X]_ s ​$，那么可以将 $ a ​$ 中出现的所有 $x​$ 使用 $ b ​$ 进行代换，记为 $ [b/x]a ​$，且 $ [b/x]a \in A[X]_{s’} ​$。其中 $ a ​$ 被称为 <em>代换目标</em>，$ x ​$ 被称为 <em>代换项</em>。代换可以定义为以下等式：</p>
<ol>
<li>$ [b/x]x = b ​$ and $ [b/x]y = y ​$ if $ x \neq y ​$.</li>
<li>$ [b/x]o(a_1;…;a_n) = o([b/x]a1;…;[b/x]a_n) ​$.</li>
</ol>
<p>例如 $ [num[2]/x]plus(x;num[3]) = plus(num[2];num[3]) $。</p>
<p><strong>定理 1.1.</strong> 如果 $ a \in A[X,x] $，那么对于每一个 $ b \in A[X] $ 都存在唯一的 $ c \in A[X] $ 且 $ [b/x]a = c $。</p>
<p><em>证明：</em>如果 $ a = x $，根据定义 $ b = c $。如果 $ a = y \neq x $，同样根据定义 $ y = c $。否则 $ a = o(a_1,…,a_n) $，使用归纳法假设存在 $ c_1,…,c_n $ 使得 $ [b/x]a_1 = c_1 $, …, $ [b/x]a_n = c_n $，那么 $ c = o(c_1;…;c_n) $。可得对于所有的情况都成立。</p>
<p>大部分情况下可以提前枚举出所有运算符，但是在一些情况下却不行，有些运算符只能在固定的上下文生效，此时运算符的集合 $ O $ 不是确定的，所以必须留出扩展性。这时可以将 <em>形式参数</em> 作为运算符族的索引。如有一个零元运算符族 $ cls[u] $，其中 $ u $ 是 <em>活跃</em> 的形式参数集合中的元素，其中不同的形式参数对应不同的运算符：如果 $ u $ 和 $ v $ 是活跃的形式参数且 $ u \neq v $，则 $ cls[u] \neq cls[v] $。需要扩展新的运算符时，只需要添加新的形式参数即可。如果 $ u $ 是不活跃的，$ cls[u] $ 没有意义，但当它活跃时，$ cls[u] $ 就是一个零元运算符。</p>
<p>形式参数可能会和变量混淆，但它们是根本不相同的两个概念。变量是一个未知的 ast，而形式参数不代表任何东西，它只是用来区分其它的形式参数。我们用 $ A[U;X] $ 表示一个 ast 的集合，其中的变量属于集合 $ X $，形式参数属于集合 $ U $。</p>
<h2 id="抽象绑定树"><a href="#抽象绑定树" class="headerlink" title="抽象绑定树"></a>抽象绑定树</h2><p>抽象绑定树（<em>abstract binding tree</em>，简称为 <em>abt</em>）,为 ast 添加了新变量和形式参数的声明，称为 <em>绑定</em>，以及他们的有效范围，称为 <em>作用域</em>，一个绑定的作用域是被绑定的标识符所在的 abt。因此一棵子树的活跃标识符集合可能比外层的集合大，不同的子树也可能会包含不同的标识符。但是所有的标识符都只是一个引用，也就是说选用不同的标识符所表达的含义是一致的，因此我们总是可以给绑定关联一个不同的标识符。</p>
<p>比如有一个表达式 $ let ~ x ~ be ~ a_1 ~ in ~ a_2 $，声明了一个变量 $ x $ 在表达式 $ a_2 $ 中代表 $ a_1 $，而 $ a_1 $ 中的 $ x $ 即使拥有相同的名字，也是不同的变量。相同的绑定更换名字不改变它的含义，如表达式 $ let ~ x ~ be ~ x * x ~ in ~ x + x $ 与 $  let ~ y ~ be ~ x * x ~ in ~ y + y  $ 是等价的。而 $  let ~ x ~ be ~ y * y ~ in ~ x + x  $ 与前面两个表达式都不同，因为这里的 $ y $ 代表的可能是外层 abt 中的另一个变量。另外在改变变量命名时不能改变引用的结构，如 $ let ~ x ~ be ~ 2 ~ in ~ let ~ y ~ be ~ 3 ~ in ~ x + x $ 与 $ let ~ y ~ be ~ 2 ~ in ~ let ~ y ~ be ~ 3 ~ in ~ y + y $ 所表示的意义不同。后者的 $ y + y $ 中的 $ y $ 表示的是内部结构的 $ y $ 而不是外部的。</p>
<pre class="line-numbers language-none"><code class="language-none">let x be 2 in
    let y be 3 in
        x + x

let y be 2 in
    let y be 3 in
        y + y</code></pre>

<p>Abt 可以给运算符参数绑定有限个变量，记作 $ x_1,…,x_k.a $。变量序列 $ x_1,…,x_k $ 绑定在 abt $ a $ 中，当 $ k = 0 $ 时 $ .a $ 可以省略为 $ a $。如表达式 $ let ~ x ~ be ~ a_1 ~ in ~ a_2 $ 写作 abt 就是 $ let(a_1;x.a_2) $。另外使用 $ \vec{x} $ 表示有限不重复序列 $ x_1,…,x_n $，所以 $ x_1,…,x_n.a $ 也可以写作 $ \vec{x}.a $。</p>
<p>为了表示绑定，abt 中运算符的参数表使用 <em>格</em> 的有限序列表示。这个序列的长度表示参数的数量，其中每个格表示一个参数的类别和绑定的变量类别。一个格用 $ (s_1,…,s_k)s ​$ 的形式表示 $ k ​$ 个类别分别为 $ s_1,…,s_k ​$ 的变量绑定在类别为 $ s ​$ 的参数上，并且使用 $ \vec{s} ​$ 表示有限序列 $ s_1,…,s_n ​$。如果变量序列 $ \vec{x} ​$ 和类别序列 $ \vec{s} ​$ 具有相同的长度，且每个 $ x_i ​$ 都属于类别 $ s_i ​$，那么称 $ \vec{x} ​$ 属于类别 $ \vec{s} ​$。举例来说，$ let ​$ 运算符的参数表为 $ (\text{Exp}, (\text{Exp})\text{Exp}) ​$，表示第一个参数是 Exp 类别的且没有绑定的变量，第二个参数是 Exp 类别的且绑定了一个 Exp 类别的变量。表达式 $ let ~ x ~ be ~ 2 + 2 ~ in ~ x \times x ​$ 写作 abt 是</p>
<p>$$ let(plus(num[2];num[2]);x.times(x;x)) $$</p>
<p>设 $ O $ 是运算符族，其中的运算符 $ o $ 的参数表为 $ ar(o) $。对于变量族 $ X $，对应的 abt 族 $ B[X] $ 的定义与 $ A[X] $ 类似，但是它活跃的变量会随着绑定的变量而改变：</p>
<ol>
<li>如果 $ x \in X_s ​$, 则 $ x \in B[X]_s ​$.</li>
<li>如果 $ ar(o) = ((\vec{s_1})s_1,…,(\vec{s_n})s_n) $， $ \vec{x_i} $ 属于类别 $ \vec{s_i} $ 且 $ a_i \in B[X, \vec{x_i}]_{s_i} $，则 $ o(\vec{x_1}.a_1;…;\vec{x_n}.a_n) \in B[X]_s $.</li>
</ol>
<p>这个定义有一点问题，考虑下面这个 abt：$ let(a_1;x.let(a_2;x.a_3)) $。根据上面的定义，这个 abt 是不合法的。内层的 abt 在构造的时候引入了变量 $ x $，因此变量族从 $ X $ 变为了 $ X,x $。接下来考虑外层的时候，需要把 $ x $ 邻接于 $ X,x $ ，这就产生了冲突。因为两个 $ x ​$ 的符号相同，但是表示的意思是不同的。实际上选取不同的变量名不应该造成含义上的区别，因此可以修改第二条定义，考虑重命名变量：</p>
<p>如果 $ ar(o) = ((\vec{x_1})s_1,…,(\vec{x_n})s_n) $，且对于每个重命名 $ \pi_i:\vec{x_i} \leftrightarrow \vec{x_i’} $（$ \vec{x_i’} \notin X $），都有 $ \pi_i \cdot a_i \in B[X,\vec{x_i’}] $，则 $ o(\vec{x_1}.a_1;…;\vec{x_n}.a_n) \in B[X]_s ​$。</p>
<p>这个重命名规则避免了外部的变量和内部的变量冲突的情况。它保证了所有绑定的变量都与外围环境无关。</p>
<p>类似于 ast，如果需要证明一个性质 $ P(a)[X] $ 对于所有的 abt $ a \in B[X] $ 都成立，那么只需要证明：</p>
<ol>
<li>如果 $ x \in X_s $，那么 $ P[X]_s(x) $.</li>
<li>对于任意属于类别 $ s $，具有参数表 $ (\vec{s_1})s_1,…,(\vec{s_n})s_n $ 的运算符 $ o $，如果对于每个重命名 $ \pi_i:\vec{x_i} \leftrightarrow \vec{x_i’} $ 都有 $ P[X, \vec{x_i’}]_{s_i}(\pi_i \cdot a_i) $，那么 $ P[X]_s(o(\vec{x_1}.a_1;…;\vec{x_n}.a_n)) $.</li>
</ol>
<p>这也是一个归纳性的推理，遵循了上面构造 abt 的过程。举例来说，我们定义一个命题 $ x \in a $（$ a \in B[X, x] $），表示 $ x $ 在 $ a $ 中是自由变量。具体来说，它的意思是 $ x $ 变量绑定在 $ a $ 之外，而不是 $ a $ 内部。那么要证明这个命题只需要说明：</p>
<ol>
<li>$ x \in x ​$.</li>
<li>如果存在 $ 1 \le i \le n $ 对于每个重命名 $ \pi : \vec{x_i} \leftrightarrow \vec{z_i} $ 使得 $ x \in \pi \cdot a_i $，则 $ x \in o(\vec{x_1}.a_1;…;\vec{x_n}.a_n) $.</li>
</ol>
<p>第一个条件说明 $ x $ 在 $ x $ 本身中是自由的，但是在任何其它的变量中不是自由的。第二个条件表面如果 $ x $ 在某个参数中，无论使用那个绑定的变量名称，都是自由的，那么 $ x ​$ 在整个 abt 中是自由的。</p>
<p>如果两个 abt，$a$ 和 $ b $，无论选取什么绑定变量名都是相同的，则称为 <em>α 等价</em>，记为 $ a =_\alpha b $ 。它的具体定义如下：</p>
<ol>
<li>$ x =_\alpha x ​$.</li>
<li>对于每个 $ 1 \le i \le n $ 和所有新的重命名 $ \pi_i : \vec{x_i} \leftrightarrow \vec{z_i} $ 和 $ \pi_i’:\vec{x_i’} \leftrightarrow \vec{z_i} $，都有 $ o(\vec{x_i}.a_1;…;\vec{x_n}.a_n) $.</li>
</ol>
<p>如果 $ a =_\alpha b $，那么称它们互为 <em>α 变体</em>。</p>
<p>考虑 abt 中将某个自由变量 $x$ 的 <em>代换</em> 为同类别的 abt，可以粗略地定义为：</p>
<ol>
<li>$ [b/x]=b $，$ [b/x]y = y ~ (x \neq y)$.</li>
<li>对于每个 $ 1 \le i \le n $，要求 $ \vec{x_i} \notin b $，且若 $ x \notin \vec{x_i} $，设 $ a_i’ = [b/x]a_i $，否则设 $ a_i’ = a_i $，那么 $ [b/x]o(\vec{x_1}.a_1;…;\vec{x_n}.a_n) $.</li>
</ol>
<p>从第二个条件可以看出，如果 $ x $ 绑定于某个参数中，那么参数中的 $ x $ 不会进行代换，因为这两个 $ x $ 的含义是不同的，所以需要判断是否 $ x \notin \vec{x_i} $。同样地，$ \vec{x_i} \notin b $ 也是为了保证代换后的变量不会与原来的绑定变量发生冲突，造成含义的混淆。如果这两个条件不都成立，那么这个代换是没有定义的。为了解决这种没有定义的问题，可以在条件中添加新的重命名的设定。我们知道对于任意新的重命名 $ \pi_i : \vec{x_i} \leftrightarrow \vec{x_i’} $，代换 $ [b/x] (\pi_i \cdot a_i) ​$ 都是合法的。所以对于选定的新的重命名，我们可以定义</p>
<p>$$ [b/x]o(\vec{x_1}.a_1;…;\vec{x_n}.a_n) = o(\vec{x_1’}.[b/x] (\pi_1 \cdot a_1);…;\vec{x_n’}.[b/x] (\pi_n \cdot a_n)) $$</p>
<p>这样我们就不需要关注 $ x \notin \vec{x_i} $ 这个条件了，因为通过重命名可以保证这个条件的成立。另外，我们也可以通过选择一个不包含冲突变量名的 α 变体作为代换目标，这样就可以安全地进行代换。换句话说，abt 的代换是定义在整个 α 等价类上的。为了避免绑定带来的其它问题，我们将所有 α 等价的 abt 看成是相同的。也就是说所有对于 abt 的讨论都针对整个 α 等价类，而非某个 abt 本身。因此当我们研究一个 abt 时，只需要选择一个具有代表性的 abt，而不用关系它的变量名。</p>
<p>和变量类似，形式参数也可以绑定在运算符的参数上。为了表示形式参数，我们把格扩展为 $ (\vec{s_1};\vec{s_2})s $，表示类别为 $ s_1 $ 的形式参数和类别为 $ s_2 $ 的变量绑定在类别为 $ s $ 的参数上。Abt 族 $ B[U;X] $ 的形式参数来源于集合 $ U $，变量来源于集合 $ X $。按照习惯，用 $ u $, $v$ 表示形式参数，用 $ x $, $ y $ 表示变量。</p>
<h2 id="总结"><a href="#总结" class="headerlink" title="总结"></a>总结</h2><p>这部分介绍了语法的基本概念，将 <em>表层语法</em> 和 <em>抽象语法</em> 进行了区分。在抽象语法中又分为仅包含语句结构的 <em>抽象语法树</em> 和包含标识符定义和作用域的 <em>抽象绑定树</em>，并提出了相关的定义和定理。其中运用了大量的归纳法，从定义出发按照构造的过程对一些定义进行了说明。这部分是后面更为深入的内容的基础，需要熟悉里面的符号表示并理解概念。</p>
<p>区分这几个不同层次的概念可以帮助我们更好地理解语法结构，也能够知道在遇到什么问题时要从什么地方下手。如重构代码时，需要保证重命名前后的变量在语义上保持一致，且不与其它的变量名产生冲突。这部分涉及到变量的绑定问题，就需要从 abt 层面进行解决。以 JavaScript 为例，@babel/parser 可以将代码转化为 ast，但根据刚刚的分析，仅仅根据这个是很难帮助我们完成重命名的操作的。这时候可以借助 @babel/traverse 遍历 ast，在遍历的过程中能够访问到当前节点的作用域以及绑定等信息，这样就有了更多的信息，可以保证重命名前后语法的一致性。</p>
]]>
    </content>


    <summary type="html">&lt;h1 id=&quot;语法对象&quot;&gt;&lt;a href=&quot;#语法对象&quot; class=&quot;headerlink&quot; title=&quot;语法对象&quot;&gt;&lt;/a&gt;语法对象&lt;/h1&gt;&lt;p&gt;编程语言是一种语言，它们用于表示计算机和人类都能理解的计算过程。一门编程语言的语法确定了它可以由哪些语句组成。那么这些语句是</summary>


    <category term="PFPL" scheme="https://blog.means88.com/tags/PFPL/"/>
    
    
  </entry>
  
  <entry>
    <title>TypeScript 中的类型安全</title>
    <link href="https://blog.means88.com/type-in-typescript/"/>
    <id>https://blog.means88.com/type-in-typescript/</id>
    <published>2019-01-15T21:44:00.000Z</published>
    <updated>2026-06-17T03:22:48.956Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//type-in-typescript/cover.png" /> <p>TypeScript 是目前用来解决 JavaScript 没有静态类型检查问题的最佳选择之一。当程序员试图将毫不相干的类型赋值给一个变量，或是使用一个类型不存在的属性时会给出警告。但是在实际开发过程中仍然能发现很多类型错误导致的异常情况。TypeScript 能在多大程度上保障程序的类型安全呢？</p>
<h2 id="普通类型的相容性"><a href="#普通类型的相容性" class="headerlink" title="普通类型的相容性"></a>普通类型的相容性</h2><p>与其它很多静态类型的语言一样，它提供了类型继承和代数数据类型等特性。我们都知道，有类似类型系统的语言一般都有一个规则，父类的引用可以指向子类对象，反之则不行。并且 TypeScript 中使用鸭子类型，即一些对象如果包含某个接口的所有属性，实现了某个接口的所有方法，那么它们就是同一类。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">interface Animal &#123;
  age: int;
&#125;

interface Duck &#123;
  age: int;
  quack(): void;
&#125;

const animal: Animal &#x3D; &#123;
  age: 2,
  quack() &#123;
    console.log(&#39;gaga&#39;);
  &#125;,
&#125;;</code></pre>

<p>上面的 <code>animal</code> 对象虽然没有显式实现 <code>Duck</code> 接口，但实现了它的所有属性，所以可以在任何一个需要 <code>Duck</code> 接口的地方使用 <code>animal</code>。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function cook(duck: Duck) &#123;
  &#x2F;&#x2F; ...
&#125;

cook(animal); &#x2F;&#x2F; OK</code></pre>

<p>因此，可以根据一个对象所包含的属性和方法将它们分为不同的类，并且，如果某一个类型 S 可以填入任何需要类型 T 的地方，就称 S 为 T 的子类型，记作 $ S &lt;: T $。如上面的例子中，<code>Duck</code> 就是 <code>Animal</code> 的子类型。</p>
<h2 id="更复杂一点的类型替换"><a href="#更复杂一点的类型替换" class="headerlink" title="更复杂一点的类型替换"></a>更复杂一点的类型替换</h2><p>接下来考虑一个复杂度稍高一点的问题：如果 $ S &lt;: T $，那么对于它们的数组类型，是否有子类型关系 $ S[] &lt;: T[] $ 呢？也就是说，一个需要 <code>Animal[]</code> 的地方，能否使用 <code>Duck[]</code> 安全地替换呢？</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function createDucks(): Duck[] &#123;
  &#x2F;&#x2F; ...
&#125;
const animals: Animal[] &#x3D; createDucks();
animals.forEach((animal) &#x3D;&gt; &#123;
  console.log(animal.age);
&#125;);</code></pre>

<p>这样的操作貌似没有什么问题，因为这个引用会把所有的数组元素当作 <code>Animal</code> 来处理，而 <code>Duck</code> 是可以安全地替代 <code>Animal</code> 的，所以以上的操作也是安全的。但是这里还有另一个例子：</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="4" data-line-offset="0"><code class="language-typescript">const ducks: Duck[];
const animals: Animals &#x3D; ducks[];
animals[0] &#x3D; createAnimal();
ducks[0].quack(); &#x2F;&#x2F; Error: ducks[0].quack is not a function</code></pre>

<p>这里通过类型为 <code>Animal[]</code> 的引用往一个 <code>Duck[]</code> 的数组中添加了一个类型不为 <code>Duck</code> 的对象，在试图调用 <code>quack</code> 方法的时候，却发现这个对象实际上不是 <code>Duck</code> 类型的。所以在读取操作中，这样的替换是安全的，但是在修改操作中就会有隐患。</p>
<p>如果使用 <code>Animal[]</code> 类型去替换 <code>Duck[]</code> 类型，就会得到刚好相反的结论。此时读取的操作是不安全的（试图引用 <code>Duck</code> 的特有属性却不存在），但是修改却是安全的（往 <code>Animal[]</code> 中添加 <code>Duck</code> 对象不会有问题）。</p>
<p>因此得出结论，即使 $ S &lt;: T $ 成立，$ S[] $ 和 $ T[] $ 之间的子类型关系也是无法确定的。一般地，只有当 $ S = T $ 时，它们才可以安全地相互替换。但在实际操作中，如果不允许这种替换，会给很多程序的编写带来麻烦，因此 TypeScript（以及很多其它语言）允许使用子类型的数组替代父类型的数组。在这里，数组类型的兼容方向与它的元素类型保持一致，被称为「协变」。如果兼容时的替换规则与元素类型相反，则被称为「逆变」。</p>
<h2 id="函数类型的相容性"><a href="#函数类型的相容性" class="headerlink" title="函数类型的相容性"></a>函数类型的相容性</h2><p>在 TypeScript 等函数作为一等公民的语言中，函数可以像其它类型变量一样进行赋值，或是作为另一个函数的参数/返回值。那么在什么条件下，一种类型的函数是另一种函数的子类型呢？</p>
<!-- ### 只有返回值的函数 -->
<p>先从最简单的函数类型开始，这种函数不接受任何参数，但是有一个返回值。仍然假设有两个类型 $ S $ 和 $ T $，且 $ S &lt;: T $，并分别构造函数类型 $ () \rightarrow S $ 和 $ () \rightarrow T $。因为只有返回值而没有参数，所以只要一个函数的返回值类型能够替代另一个的返回值类型即可。所以 $ () \rightarrow S &lt;: () \rightarrow T $。</p>
<!-- ### 只有一个参数的函数 -->
<p>对于 $ S \rightarrow void $ 和 $ T \rightarrow void $，情况就没有那么简单。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function f(arg: T) &#123;&#125;
function g(arg: S) &#123;&#125;

const t: T &#x3D; new T();
f(t); &#x2F;&#x2F; &#x3D;&gt; g(t)</code></pre>

<p>如果将此处的函数替换，调用 <code>g(t)</code>，会带来一些问题。函数 <code>g</code> 期望得到类型 $ S $ 的参数，但是实际提供的是 $ T $，所以函数会在访问子类型 $ S $ 特有的属性时出现错误。再看看反过来的情况，尝试使用函数 <code>f</code> 替代 <code>g</code>。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">const s: S &#x3D; new S();
g(s); &#x2F;&#x2F; &#x3D;&gt; f(s)</code></pre>

<p>这样不会有类型安全问题，<code>f</code> 函数会使用 $ T $ 类型具有的属性，而这些属性 $ S $ 也都包含。所以此时 $ () \rightarrow T &lt;: () \rightarrow S $</p>
<!-- ### 更一般的函数 -->
<p>综合上面两个例子可以得到结论，函数对于参数类型是逆变的，而对于返回类型是协变的，即 $ T_2 &lt;: T_1, R_1 &lt;: R_2 \Rightarrow (T_1 \rightarrow R_1) &lt;: (T_2 \rightarrow R_2) $。对于多参数的函数，可以把它的参数理解为一个键值为自然数的类型（即数组）。比如 <code>(s: S, t: T) =&gt; R</code> 的参数类型就可以看作：</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">interface Args &#123;
  0: S,
  1: T,
&#125;;
</code></pre>
<p>这样就可以得出，当 $ n \le m $, 有 $ (S1, S2, …, S_n) \rightarrow R &lt;: (S1, S2, …, S_m) \rightarrow R $。</p>
<!-- ### TypeScript 中的相容性 -->
<p>再来看看 TypeScript 中是怎么处理函数的。如上文所述，参数类型协变或是返回类型逆变时，函数的安全性是不能保证的。但是前面还提到，为了保证程序编写的简洁，TypeScript 认为子类的数组是兼容父类数组的，假设 TypeScript 只允许函数参数逆变，那么考虑 <code>Animal[]</code> 和 <code>Duck[]</code> 的 <code>push</code> 方法：</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">type AnimalPush &#x3D; (x: Animal) &#x3D;&gt; number;
type DuckPush &#x3D; (x: Duck) &#x3D;&gt; number;
</code></pre>

<p>那么 $ DuckPush &lt;: AnimalPush $ 是不成立的，这样 <code>Duck[]</code> 也就无法兼容 <code>Animal[]</code>。因此 TypeScript 在这里进行了妥协，允许所有函数的参数是逆变或者协变。</p>
<h2 id="结论"><a href="#结论" class="headerlink" title="结论"></a>结论</h2><p>TypeScript 中类型的检查并不严格地遵守类型安全，因此在使用时有一部分类型错误无法通过 TypeScript 的类型检查发现。这种情况下，需要开发者自己采取一些措施保证类型的安全，并且能在出现类型错误时意识到可能有问题的地方。</p>
<h3 id="使用泛型替代更大的类型"><a href="#使用泛型替代更大的类型" class="headerlink" title="使用泛型替代更大的类型"></a>使用泛型替代更大的类型</h3><p>父类型数组的引用也可以指向子类型数组，但是如果对它进行修改，就会出现安全隐患。其实在很多情况下可以使用泛型代替父类型实现通用的操作。</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function unsafe(animals: Animal[]) &#123;
  &#x2F;&#x2F; ...
&#125;

function safe&lt;T extends Animal&gt;(animals: T[]) &#123;
  &#x2F;&#x2F; ...
&#125;

const ducks: Ducks &#x3D; [foo, bar];

unsafe(ducks);
safe(ducks);</code></pre>

<p><code>safe</code> 函数中的操作都会基于类型 <code>T</code> 进行，而不像 <code>unsafe</code> 中可能写入一个不符合实际类型的值。</p>
<h3 id="注意函数参数"><a href="#注意函数参数" class="headerlink" title="注意函数参数"></a>注意函数参数</h3><p>因为 TypeScript 中函数的参数类型是可以协变的，所以函数接收到的参数类型不一定安全。</p>
<pre class="line-numbers language-typescript" data-language="typescript" data-start="1" data-line="8" data-line-offset="0"><code class="language-typescript">type AnimalFunc &#x3D; (animal: Animal) &#x3D;&gt; void;

const f: AnimalFunc &#x3D; (duck: Duck) &#x3D;&gt; &#123;
  duck.quack();
&#125;;

const animal: Animal &#x3D; deer;
f(animal); &#x2F;&#x2F; Error: duck.quack is not a function</code></pre>

<p>对于一些函数，可以使用多个参数来代替一个具有多个属性的参数，如：</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">function unsafe(params: &#123; foo: number, bar: number &#125;) &#123;
  &#x2F;&#x2F; ...
&#125;

function safe(foo: number, bar: number) &#123;
  &#x2F;&#x2F; ...
&#125;</code></pre>

<p>当然前一种函数原型更方便扩展，在具体使用时需要结合实际情况。如果有必要，可以开启 <code>--strictFunctionTypes</code> 选项保证函数的参数类型只能进行逆变。对于 <code>bind</code>, <code>apply</code> 和 <code>call</code> 函数，TypeScript 也在 3.2 版本提供了 <code>--strictBindCallApply</code> 选项开启检查。</p>
<h3 id="谨慎使用-any"><a href="#谨慎使用-any" class="headerlink" title="谨慎使用 any"></a>谨慎使用 any</h3><p>对于使用 <code>any</code> 类型的情况，TypeScript 几乎不会做任何的类型检查，但是实际上没有一个值可以胜任所有情况。当使用了 <code>any</code> 时，不会有人提醒程序员去做类型检查，这会给程序留下很大的隐患。TypeScript 3.0 版本以后提供了 <code>unknown</code> 类型，它是子类型关系下的最大元素，因此任何试图直接使用 <code>unknown</code> 类型的行为都会被检查出来，并要求进行类型的检查。在很多情况下，<code>any</code> 应当使用 <code>unknown</code> 来代替。</p>
<h2 id="参考文献"><a href="#参考文献" class="headerlink" title="参考文献"></a>参考文献</h2><ol>
<li>Castagna, G. (1995). Covariance and contravariance: conflict without a cause. ACM Transactions on Programming Languages and Systems (TOPLAS), 17(3), 431-447.</li>
<li>Cardelli, L. (1984). A semantics of multiple inheritance. In Semantics of data types (pp. 51-67). Springer, Berlin, Heidelberg.</li>
<li>FAQ in Microsoft/TypeScript Wiki (2018, June). Retrieved January 18, 2019, from <a href="https://github.com/Microsoft/TypeScript/wiki/FAQ">https://github.com/Microsoft/TypeScript/wiki/FAQ</a>.</li>
</ol>
]]>
    </content>


    <summary type="html">&lt;p&gt;TypeScript 是目前用来解决 JavaScript 没有静态类型检查问题的最佳选择之一。当程序员试图将毫不相干的类型赋值给一个变量，或是使用一个类型不存在的属性时会给出警告。但是在实际开发过程中仍然能发现很多类型错误导致的异常情况。TypeScript 能在多大程度</summary>


    <category term="TypeScript" scheme="https://blog.means88.com/tags/TypeScript/"/>
    
    
  </entry>
  
  <entry>
    <title>Flutter 分享整理总结</title>
    <link href="https://blog.means88.com/flutter-share/"/>
    <id>https://blog.means88.com/flutter-share/</id>
    <published>2019-01-10T21:35:53.000Z</published>
    <updated>2026-06-17T03:22:48.928Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com//flutter-share/hanayo-flutter.jpg" /> <p>Flutter 是一个由 Google 创建，面向 Android 和 iOS 应用开发的跨平台开源框架，并于 2018 年 12 月 4 日发布了 1.0 版本。不同于 React Native 等跨平台框架，Flutter 不生成原生组件，而是自己控制引擎将组件渲染出来。因此 Flutter 的渲染速度很快，而且不需要考虑不同平台出现的渲染差异。</p>
<h2 id="Dart"><a href="#Dart" class="headerlink" title="Dart"></a>Dart</h2><p>说到 Flutter 就不得不提 Dart 语言。Dart 同样是由 Google 创建的一门开源语言，Google 的 Adwords，Flutter 以及 Fuchsia 等项目在开发时都使用了 Dart。那么 Dart 有什么样的特点呢？</p>
<h3 id="优点"><a href="#优点" class="headerlink" title="优点"></a>优点</h3><h4 id="入门成本较低"><a href="#入门成本较低" class="headerlink" title="入门成本较低"></a>入门成本较低</h4><p>很多程序员都会有一门或几门比较拿手的编程语言，比如 Java，JavaScript 或者 Swift 等。但就目前的形式来看，擅长使用 Dart 的程序员比例非常低，有很多人甚至没有使用过（甚至没有听说过）Dart。但比较幸运的一点是 Dart 学习起来并不困难，与上述几门语言相比它没有提出什么崭新的概念，使用的语法也与很多编程语言类似，因此有其它编程语言基础的程序员可以比较快速地入门 Dart。</p>
<h4 id="支持预编译与即时编译"><a href="#支持预编译与即时编译" class="headerlink" title="支持预编译与即时编译"></a>支持预编译与即时编译</h4><p>一些编程语言在运行之前会提前转换为为目标代码，然后在对应的平台上执行，这种行为被称为预编译（AOT）。相对应地，还有一些编程语言不会在运行前进行处理，或只进行一部分预处理，在代码执行的时候才转换为目标平台的代码，这种行为被称为即时编译（JIT）。一般来说，由于经过预先的编译，AOT 编译的产物一般都有速度较快，runtime 较小的优点，而 JIT 能够在运行时获取较详细的代码上下文，适合调试与快速开发。</p>
<p>Dart 同时支持这两种编译方式，只要在开发时启用 JIT 编译，在发布包时使用 AOT 编译，就可以同时拥有这两者的长处。</p>
<h3 id="缺点"><a href="#缺点" class="headerlink" title="缺点"></a>缺点</h3><p>每个语言都是为了解决一些其它语言难以应对问题而被创造出来的，因此大部分语言都有它的适用场景。但是一般地，一门好的语言应该在减少开发者工作量的同时保证程序的可靠性。Dart 在这方面仍然有许多值得改进的地方。</p>
<h4 id="所有类型都是-nullable"><a href="#所有类型都是-nullable" class="headerlink" title="所有类型都是 nullable"></a>所有类型都是 nullable</h4><pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">int a &#x3D; null;

double div(double a, double b) &#123;
  if (b &#x3D;&#x3D; 0) &#123;
    return; &#x2F;&#x2F; 这里没有返回值，但仍然是合法的表达
  &#125;
  return a &#x2F; b;
&#125;</code></pre>

<p><code>null</code> 被称为是一个「十亿代价的错误」，在面向对象的语言中，有无数的系统错误是因为空引用导致的，因为 <code>null</code> 的存在导致很多程序员在编写的时候没有或者忘了检查这个值。在一些语言（例如 TypeScript）中，一个类的引用不能为 <code>null</code>，并且在使用可能为 <code>null</code> 的引用时需要被强制检查：</p>
<pre class="line-numbers language-typescript" data-language="typescript"><code class="language-typescript">class A &#123;
  f: number &#x3D; 0;
&#125;
&#x2F;&#x2F; Error: Type &#39;null&#39; is not assignable to type &#39;A&#39;.ts(2322)
const a: A &#x3D; null;
&#x2F;&#x2F; OK
const b: A | null &#x3D; null;
&#x2F;&#x2F; Error: Object is possibly &#39;null&#39;.ts(2531)
b.f;</code></pre>

<p>这样就可以在代码运行之前就检查出很多潜在的空引用错误。而 Dart 非但没有吸取这个教训，反而将 <code>null</code> 的使用扩大化，这样就无法在语言层面保证程序的健壮性。</p>
<p><img src="dart-assert-null.png" alt="Null Assertion in Flutter SDK"></p>
<p>上图摘自 Flutter SDK 中的某一段源码，可以发现为了保证程序的健壮性，程序员需要在每个函数的前面断言参数不为 <code>null</code>，并且这里的错误只能在运行期间才能发现，增加了开发难度。</p>
<h4 id="类型推断不够完善"><a href="#类型推断不够完善" class="headerlink" title="类型推断不够完善"></a>类型推断不够完善</h4><p>很多时候，一段程序的逻辑与它所要处理的数据类型无关，所以编程语言需要有一种机制来避免为了不同的类型写重复的代码。像 Python，JavaScript 之类的语言使用鸭子类型，在使用数据的时候不关心它的具体类型，而只关注是否实现了某些特性。而 C++，Java 等语言的类型比较严格，必须在编写方法时确定它可以接受的参数类型，因此给出了模板和泛型等解决方案。Dart 与后者的解决方案更加相似，它提供了泛型来解决这样的问题。但是它的类型推断仍然有一些不完善的地方。</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">Type id&lt;Type&gt;(Type a) &#x3D;&gt; a;

typedef FunctionType&lt;T&gt; &#x3D; T Function(T);

class FunctionWrapper&lt;T&gt; &#123;
  FunctionWrapper(&#123;
    this.func &#x3D; id,
  &#125;);

  FunctionType&lt;T&gt; func;
&#125;

main() &#123;
  final f &#x3D; FunctionWrapper&lt;int&gt;();
  print(f.func(0));
&#125;</code></pre>

<p>上述代码会在<strong>运行时</strong>给出如下错误：</p>
<pre class="line-numbers language-none"><code class="language-none">Unhandled exception:
type &#39;(T) &#x3D;&gt; T&#39; is not a subtype of type &#39;(int) &#x3D;&gt; int&#39;
#0      main (file:&#x2F;&#x2F;&#x2F;Users&#x2F;means88&#x2F;code&#x2F;test&#x2F;function.dart)
#1      _startIsolate.&lt;anonymous closure&gt; (dart:isolate&#x2F;runtime&#x2F;libisolate_patch.dart:279:19)
#2      _RawReceivePortImpl._handleMessage (dart:isolate&#x2F;runtime&#x2F;libisolate_patch.dart:165:12)
</code></pre>

<p>可以看到 <code>id</code> 函数的类型没有正确地被推导出来，这就给语言的使用增加了一些限制。另外，在语言不支持的情况下，也没有给出编译时的错误，提高了开发的成本。</p>
<h4 id="dynamic-类型"><a href="#dynamic-类型" class="headerlink" title="dynamic 类型"></a>dynamic 类型</h4><p>上述的几项虽然可以有更大的改进空间，但并不是最致命的问题。很多语言都或多或少带有一些问题，这是不可避免的，但 <code>dynamic</code> 绝对称得上是这个语言最大的败笔。那么 <code>dynamic</code> 类型做了些什么呢。</p>
<p>将一个引用声明为 <code>dynamic</code> 类型并不改变运行时的结果，但是它<strong>关闭了类型检查</strong>。语言特性的缺失可以用很多方法来补救，但是 Dart 选择了掩耳盗铃。它提供一个关键字关闭了编译器的检查，让开发者自己在运行时确认引用对象的类型。这个问题比 <code>null</code> 严重好几倍，现在我们不仅需要判断一个引用是否为 <code>null</code>，还需要判断它所指的对象究竟是什么类型。另外，所有的代码提示也会一起被 <code>dynamic</code> 带走，这使得程序代码非常不可控。</p>
<p>Dart 完全可以提供一个更完善的类型系统，使用严格的代数数据类型取代 <code>dynamic</code>，这样就可以在保证语言灵活性的同时保证程序的稳定性。而非像现在一样只能通过开发者自己不停地判断保证类型的匹配。</p>
<h3 id="代码生成"><a href="#代码生成" class="headerlink" title="代码生成"></a>代码生成</h3><p>Dart 的类型是静态的，所以没有办法获取到太多的运行期间的信息进行下一步操作。虽然 Dart 中也有反射机制，但是在 Flutter 中这个特性是被关闭的，因此不可避免地会产生一些冗余的代码。例如将一段数据发送给服务器，我们希望调用的地方有代码提示，而发送的时候最终需要转换成 <code>Map</code>，最后代码可能会变成这样：</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">Future&lt;Response&gt; sendSomeData(&#123;
  @require String name,
  @require int age,
  String description,
&#125;) &#123;
  final params &#x3D; &#123;
    &quot;name&quot;: name,
    &quot;age&quot;: age,
    &quot;description&quot;: description,
  &#125;;
  return request(params);
&#125;</code></pre>

<p>或者可以把函数参数放在一个类中，但是这个类仍然需要提供构造函数和转换为 <code>Map</code> 的方法，如：</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">class RequestParams &#123;
  String name;
  int age;
  String description;

  RequestParams(&#123;
    @required this.name,
    @required this.age,
    this.description,
  &#125;);

  Map&lt;String, dynamic&gt; toMap() &#123;
    return &#123;
      &quot;name&quot;: name,
      &quot;age&quot;: age,
      &quot;description&quot;: description,
    &#125;;
  &#125;
&#125;</code></pre>

<p>许多框架都会借助代码生成来减轻开发者的工作，如客户端的布局文件或资源文件都会生成代码供开发者引用。同样地，为了解决这个问题，Dart 提供了 <a href="https://github.com/dart-lang/build">build</a> 这个包，以及 <a href="https://github.com/dart-lang/source_gen">source_gen</a> 等更高层次的实现。基于这些包可以开发出一些自动生成代码的工具来减少冗余的代码。如上面的情况，可以使用 <a href="https://github.com/dart-lang/json_serializable">json_serializable</a> 自动生成转为 <code>Map</code> 的代码：</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">import &#39;package:json_annotation&#x2F;json_annotation.dart&#39;;

part &#39;request_params.g.dart&#39;;

@JsonSerializable()
class RequestParams &#123;
  String name;
  int age;
  String description;

  RequestParams(&#123;
    @required this.name,
    @required this.age,
    this.description,
  &#125;);

  factory RequestParam.fromJson(Map&lt;String, dynamic&gt; json) &#x3D;&gt; _$RequestParamsFromJson(json);

  Map&lt;String, dynamic&gt; toJson() &#x3D;&gt; _$RequestParamsToJson(this);
&#125;</code></pre>

<p>其中 <code>_$RequestParamsFromJson</code> 与 <code>_$RequestParamsToJson</code> 都是自动生成在 <code>request_params.g.dart</code> 中的函数，它代替我们做了与 <code>Map</code> 相互转换的工作。以上的写法是 Dart 的官方代码生成库以及社区主流的操作方式，但这样还是有一些问题。首先上面的代码中，成员变量和构造函数中仍然有很多重复的部分，另外还需要在代码生成完毕后在原来的类中引用生成出来的函数，逻辑上产生了循环依赖，比较混乱。因此我推荐的方式是，在源文件中定义类的接口，然后在生成的文件中实现。上面的文件就可以改写为：</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">&#x2F;&#x2F; request_params.dart
@JsonSerializable()
abstract class IRequestParams &#123;
  String name;
  int age;
  String description;
&#125;

&#x2F;&#x2F; request_params.g.dart
class RequestParams implements IRequestParams &#123;
  String name;
  int age;
  String description;

  RequestParams(&#123;
    @required this.name,
    @required this.age,
    this.description,
  &#125;);

  factory RequestParam.fromJson(Map&lt;String, dynamic&gt; json) &#x3D;&gt; RequestParms(&#123;
    name: json[&#39;name&#39;],
    age: json[&#39;age&#39;],
    description: json[&#39;description&#39;],
  &#125;);

  Map&lt;String, dynamic&gt; toJson() &#x3D;&gt; &#123;
    &quot;name&quot;: name,
    &quot;age&quot;: age,
    &quot;description&quot;: description,
  &#125;;
&#125;</code></pre>

<p>这样可以减少需要编写的代码数量，同时逻辑上比较自然，使用时不容易产生疑惑。但总而言之，Dart 的代码生成并不是一个好的解决方案。观察其它语言可以发现，代码生成一般是在构建过程中的一个步骤，对终端开发者是透明的，而不像 Dart 一样需要关心生成的代码中暴露了哪些内容。Dart 的代码生成可能只是缓解语言缺陷的一个不太精妙的解决方案。</p>
<h2 id="Flutter-布局"><a href="#Flutter-布局" class="headerlink" title="Flutter 布局"></a>Flutter 布局</h2><p>因为 Dart 是一门比较普通的编程语言，所以在开发时大部分逻辑和其它客户端领域没有本质区别。但是在界面布局上，每个平台可以说是各有千秋，并且是一项纯粹依赖于经验的技能。对于大部分界面框架来说，一个元素如何布局取决于它自身的属性（以及和它相关的元素的属性），而 Flutter 将布局效果拆分到各个 Widget 中，一个 Widget 如何展示主要取决于它嵌套在哪些 Widget 中。</p>
<h3 id="盒限制模型"><a href="#盒限制模型" class="headerlink" title="盒限制模型"></a>盒限制模型</h3><p>Flutter 的元素在底层都使用 <code>RenderBox</code> 进行渲染，一般来说它的尺寸会是下面三种情况之一：</p>
<ul>
<li>尽可能地大</li>
<li>恰好容纳子元素</li>
<li>有一个固定的尺寸</li>
</ul>
<p>这一点和其它平台上的布局都比较相似，所以在这些情况下一般开发者都可以很轻松地完成界面布局，只需要将原先写在元素属性内的值拿出来用别的元素表示就可以了。</p>
<h3 id="未限制大小"><a href="#未限制大小" class="headerlink" title="未限制大小"></a>未限制大小</h3><p>但在另外一些情况下，布局的尺寸没有给出限制。比如在 Flex 布局元素的交叉轴方向，以及滚动元素的滚动方向，它的<strong>最大值</strong>是无穷（然而还是会根据内部的元素尺寸拥有一个确定的<strong>实际值</strong>）。这一点比较好理解，因为在以上的布局的尺寸可能比它外部的元素还要大，不能按照前面的情况给它设定最大值。但是，当我们试图在这样的元素里面放置一个布局规则为「尽可能大」的元素时，糟糕的情况就出现了。</p>
<p><img src="box-constraint.png" alt="Unbounded Constraint"></p>
<p>由于外面的 <code>Row</code> 没有限制最大的宽度，而里面的 <code>TextField</code> 又尝试得到最大的宽度，因此里面的 <code>TextField</code> 的实际宽度会变为无穷大，此时 Flutter 就会抛出一个错误。</p>
<pre class="line-numbers language-none"><code class="language-none">I&#x2F;flutter ( 7674): BoxConstraints forces an infinite width.
I&#x2F;flutter ( 7674): These invalid constraints were provided to RenderStack&#39;s layout() function by the following
I&#x2F;flutter ( 7674): function, which probably computed the invalid constraints in question:
...</code></pre>

<p>类似的错误可能是其它平台的开发者最容易遇到也是最摸不着头脑的一点了。比如在前端开发中，在 Flex 布局中放置一个固定尺寸的图标和一个尽可能长的输入框是很常见的行为，但是相同的做法在 Flutter 中却行不通。其中一种解决方法是在 <code>TextField</code> 外面套一层 <code>Flexible</code>，通过它来限制最大宽度，这样就可以避免上面的问题。</p>
<p><img src="box-constraint-fix.png" alt="Fixed Constraint"></p>
<p>借此也可以想象一下，有多个 Flex 元素嵌套的布局会有多么难写（<code>Row(Colomn(Row(...)))</code>）。Flutter 的布局在习惯上与其它平台还有很多差异，这一点虽然并不困难但是只能靠开发经验慢慢补足。</p>
<h3 id="容器嵌套"><a href="#容器嵌套" class="headerlink" title="容器嵌套"></a>容器嵌套</h3><p>Flutter 将布局的样式以很细的粒度拆分到了各个 Widget 中，而一些比较高级的组件默认都是 Material Design 的，不可能在实际的开发过程中直接使用。因此在目前的开发中，经常会出现很深层次的组件嵌套。这种嵌套使得代码非常难看，很难将组件和它的属性一眼分离开来，深层的缩进使得代码几乎「居中显示」。对此 Google Flutter 团队的解释是「既然布局使用 Dart 编写的，我们可以用编程语言的方法让它看起来更清楚」。但是并没有人给出一个更加具体的描述，说明怎样写可以让它看起来更清楚。也许 Flutter 需要拥有一个更加具有普适性的 UI 组件库，在提供一些基础功能的同时方便开发者对一些样式进行定义。这样或许就可以将常用的布局属性组合到一起，减少容器的嵌套了。</p>
<h2 id="状态管理"><a href="#状态管理" class="headerlink" title="状态管理"></a>状态管理</h2><p>Flutter 的框架结构在很大程度上借鉴了 React 的模式，由状态来控制组件的渲染，所以整个应用的状态管理就成了一个重要的部分。Flutter 的官方文档中对一些状态管理的方法举例进行了说明，但是其中的示例场景都比较简单，不能正确反应真实开发场景，因此在选择的时候还是需要从更深的角度去思考。</p>
<h3 id="setState"><a href="#setState" class="headerlink" title="setState"></a>setState</h3><p>React 中也有 <code>setState</code> 方法，然而两者之间有比较大的差别。React 的 <code>setState</code> 有两种模式，一种是直接传递要修改的状态属性，另一种是传递一个接收当前状态的函数，用于生成新的状态。</p>
<pre class="line-numbers language-javascript" data-language="javascript"><code class="language-javascript">state &#x3D; &#123;
  count: 0,
  data: 0,
&#125;;

this.setState(&#123;
  count: 1,
&#125;);
&#x2F;&#x2F; or
this.setState((prevState) &#x3D;&gt; (&#123;
  count: prevState.count + 1,
&#125;));

&#x2F;&#x2F; state: &#123; count: 1, data: 0 &#125;</code></pre>

<p>无论是哪种方法，都是一个纯粹的函数，它只能改变状态的值，在改变以后由框架触发界面的重新渲染。而 Flutter 的 <code>setState</code> 接收的是一个普通的函数，在里面可以做任何操作。</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">this.setState(() &#123;
  this.count &#x3D; 1;
&#125;);</code></pre>

<p>这主要是两个框架之间的理念仍然有些区别。React 希望 <code>state</code> 是 immutable 的，开发者不能直接去修改它的值。然而 Flutter 的 <code>state</code> 只是 Dart 中是一个普通的对象，不是一个特殊的角色。并且受 Dart 语言的限制，Flutter 很难实现一个通用的 patch 方法修改 <code>state</code>，因此只能让开发者自己进行操作。</p>
<p>虽然两者之间有这样的区别，但是数据的结构上还是相通的，Flutter 也会有类似于 React 的状态传递过深的问题。因此同样地，Flutter 也有 context 的机制，从框架内部提供最基础的解决方案。</p>
<h3 id="Redux"><a href="#Redux" class="headerlink" title="Redux"></a>Redux</h3><p>Redux 是 React 生态中最常使用的状态管理工具，Dart 和 Flutter 中也有对应的实现（<a href="https://github.com/johnpryan/redux.dart">redux.dart</a> 和 <a href="https://github.com/brianegan/flutter_redux">flutter_redux</a>）。Redux 在 React 的很多场景下使用也并不是特别适合，到了 Flutter 中，缺点就变得更加明显了。</p>
<h4 id="全局单一的-store"><a href="#全局单一的-store" class="headerlink" title="全局单一的 store"></a>全局单一的 store</h4><p>因为 Redux 的 store 只有一个，因此状态难以复用。状态本身的复制是比较简单的，我们可以将状态放在一个类中，多创建一些即可，但是其它部分很复杂：如果不希望每个部分相互影响，需要有不同的 action，最后「将每个部分组合到一起」这个步骤是怎么也无法跳过的。</p>
<p>在 Dart 中，这个情况更加严重。受语法上的限制，redux.dart 中的 <code>combineReducer</code> 只能将 reducer 组合到一起，而不能生成组合后的 state。Dart 中的 store 构造函数如下：</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">Store(
  this.reducer, &#123;
  State initialState,
  List&lt;Middleware&lt;State&gt;&gt; middleware &#x3D; const [],
  bool syncStream: false,
);</code></pre>

<p>与 JavaScript 版不同，这里的 <code>initialState</code> 是创建 <code>Store</code> 对象时传入的，而非定义在 reducer 的默认参数中。这意味着在创建时需要一个完整的 <code>State</code> 类。怎么写才能创造这么一个 <code>State</code>，并且保证模块之间相对的独立性呢？在实际使用时可以发现，无论是拆分部分分离到其它类还是使用 mixin 都会产生问题。</p>
<h4 id="Immutable"><a href="#Immutable" class="headerlink" title="Immutable"></a>Immutable</h4><p>不同于 React，Flutter 这个框架本身并不包含任何需要 immutable 的场景，而 Redux 在状态修改的时候需要是 immutable 的，Dart 的语言特性又决定了它并不能像 JavaScript 一样方便地对一个对象进行复制，所以在 Flutter 中使用 Redux 是不贴合框架本身的风格的，还会带来更多麻烦。</p>
<h3 id="BloC-Rx"><a href="#BloC-Rx" class="headerlink" title="BloC/Rx"></a>BloC/Rx</h3><p>相比之下，Dart 对 Stream 提供了很好的支持，如果有一种方法可以使用流的形式管理状态，那么它应该是比较适合 Flutter 的。利用 Flutter 中提供的 <code>StreamBuilder</code>，将流中的每一帧数据映射到一个 Widget，这样在 Stream 中有数据产生时，Flutter 会根据新生成的数据对界面进行更新。</p>
<pre class="line-numbers language-dart" data-language="dart"><code class="language-dart">StreamBuilder&lt;Entity&gt;(
  stream: this.entityStream,
  builder: (context, snapshot) &#123;
    return Widget(
      ...,
      onTap: () &#123;
        controller.add(someEvent);
      &#125;
    );
  &#125;,
)</code></pre>

<p>这样做有个显然的好处，就是可以把不同的数据自然地分离开，避免了在这样的语言中处理复杂类型的麻烦。通过数据流的方式，可以将多个来源的数据分别用不同的流表示，并且可以在流之间也建立订阅关系，产生更加灵活的数据流。ReactiveX 就是一个流模型的库，有多种语言的实现，并且生态系统比较丰富，在 Dart 中也有 RxDart 的实现。</p>
<h4 id="MobX"><a href="#MobX" class="headerlink" title="MobX"></a>MobX</h4><p>MobX 是一个利用 getter/setter（以及 Proxy）语言特性的响应式状态管理工具。它自动记录了对象之间的依赖关系，并在依赖发生变化的触发更新，为开发者提供透明式的响应式编程。MobX 的 Dart 版本 <a href="https://github.com/mobxjs/mobx.dart">mobx.dart</a> 仍然在开发中。</p>
<h2 id="总结"><a href="#总结" class="headerlink" title="总结"></a>总结</h2><p>Flutter 实现了一个高性能的跨平台框架，并且发布了 1.0 版本。但是这个情况和 React 发布 15.0 版本时有很大区别：React 发布第一个正式版时已经比较成熟，有许多项目已经在使用，而 Flutter 的 1.0 版本只是一个起点，具体表现为：</p>
<ul>
<li>Dart 语言不够完善，包括上面提到的问题以及 4000 多个 issue</li>
<li>Flutter 本身也有许多问题，同样拥有 4000 多个 issue</li>
<li>生态环境不够丰富，Dart Pub 上的包不足 5000 个（而 npm 超过 88 万）</li>
<li>生产环境使用较少，即使是官网的提名公司也只是很小一部分在使用</li>
</ul>
<p>（以上相关统计数据截至 Thu, 10 Jan 2019 13:16:19 GMT）</p>
<p>因此，现在并不是一个使用 Flutter 的最好时机，换用 Flutter 的收益很难超过投入的成本。但对于贡献 Flutter 来说，也许正是一个百废待兴的绝佳机会。</p>
]]>
    </content>


    <summary type="html">&lt;p&gt;Flutter 是一个由 Google 创建，面向 Android 和 iOS 应用开发的跨平台开源框架，并于 2018 年 12 月 4 日发布了 1.0 版本。不同于 React Native 等跨平台框架，Flutter 不生成原生组件，而是自己控制引擎将组件渲染出来</summary>


    <category term="Flutter" scheme="https://blog.means88.com/tags/Flutter/"/>
    
    
  </entry>
  
  <entry>
    <title>About</title>
    <link href="https://blog.means88.com/about/"/>
    <id>https://blog.means88.com/about/</id>
    <published>2018-12-31T12:17:11.000Z</published>
    <updated>2026-06-17T03:22:48.902Z</updated>
    
    <content type="html">
      <![CDATA[ <img src="https://blog.means88.com/" /> <h2 id="Hexo"><a href="#Hexo" class="headerlink" title="Hexo"></a>Hexo</h2><ul>
<li>Hexo: <a href="https://github.com/hexojs/hexo">hexojs/Hexo</a></li>
<li>Diaspora: <a href="https://github.com/Fechin/hexo-theme-diaspora">Fechin/hexo-theme-diaspora</a></li>
</ul>
<h2 id="Resources"><a href="#Resources" class="headerlink" title="Resources"></a>Resources</h2><ul>
<li>Blog cover: <a href="https://www.pixiv.net/member_illust.php?mode=manga&illust_id=70587973">pixiv@P-MAN</a></li>
</ul>
]]>
    </content>


    <summary type="html">&lt;h2 id=&quot;Hexo&quot;&gt;&lt;a href=&quot;#Hexo&quot; class=&quot;headerlink&quot; title=&quot;Hexo&quot;&gt;&lt;/a&gt;Hexo&lt;/h2&gt;&lt;ul&gt;
&lt;li&gt;Hexo: &lt;a href=&quot;https://github.com/hexojs/hexo&quot;&gt;hexojs/He</summary>


  </entry>
  
</feed>